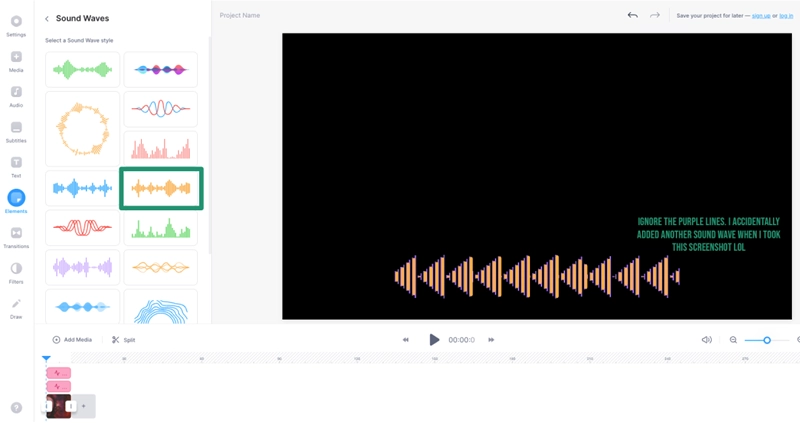
The intersection of artificial intelligence and audio engineering has produced one of the most fascinating tools available to creators today: the sound wave generator from text. This technology converts written content into audible sound waves, opening doors for accessibility, creative projects, educational content, and professional audio production—all without requiring a recording studio or complex hardware.
How Text-to-Sound Technology Actually Works
At its core, a sound wave generator from text relies on digital signal processing and machine learning models trained on vast datasets of human speech and environmental sounds. When a user inputs text, the system analyzes phonetic structure, rhythm, and intonation patterns to produce an audio output that mimics natural speech or generates unique soundscapes. These generators can produce everything from realistic voice narration to abstract tonal interpretations of written words.
Modern implementations use neural network architectures such as Tacotron, WaveNet, and more recently, diffusion-based models to achieve high-fidelity audio synthesis. The process involves tokenizing the input text, predicting acoustic features, and then rendering those features into actual sound waveforms. The result is a seamless bridge between textual information and auditory experience.
Key Applications Across Industries
Content Creation and Media Production
Podcasters, video producers, and game developers increasingly turn to text-based sound generation to create voiceovers, ambient background audio, and dynamic sound effects. Instead of hiring voice actors or hunting through sound libraries, a few seconds of text input can generate exactly the tone, pitch, and mood required for a project.
Accessibility and Inclusivity
Perhaps the most impactful application lies in accessibility. Text-to-sound tools allow visually impaired individuals to consume written content naturally, offer language learners a way to hear correct pronunciation, and help people with reading disabilities engage with written material in a format that works for them.
Education and Training
Educators use sound wave generators to create narrated summaries of textbooks, produce audio flashcards for multilingual classrooms, and develop interactive learning modules where textual information is complemented by auditory reinforcement—a method proven to improve retention.
Choosing the Right Text-to-Sound Solution
Not all generators are created equal. The following comparison highlights what to look for when evaluating different platforms:
| Feature | What to Evaluate |
|---|---|
| Voice Quality | Naturalness, articulation clarity, and emotional range |
| Language Support | Number of supported languages and accents |
| Customization | Control over pitch, speed, tone, and style parameters |
| Output Formats | MP3, WAV, OGG, and streaming compatibility |
| Privacy & Security | Data handling policies and encryption standards |
| Pricing Model | Free tier limits, subscription costs, and enterprise options |
A solid generator should offer at least baseline quality across these categories before committing to it for professional use.
SEO Implications for Content Creators
As audio content gains traction in search engine rankings, integrating text-generated sound waves into your content strategy can boost engagement metrics. Google and other search engines increasingly factor dwell time and multimedia diversity into their algorithms—both of which benefit from adding high-quality audio versions of your written articles, product descriptions, and tutorials.
Embedding auto-generated audio players on blog posts, for example, gives visitors an alternative consumption method and keeps them on the page longer. This directly influences bounce rate and session duration, two critical ranking factors.
Future of Text-Based Audio Generation
The rapid pace of advancement in this field suggests we are only scratching the surface. Real-time text-to-sound synthesis with emotional intelligence—where the generator understands context and adjusts tone accordingly—is already in development. Multi-speaker generation from a single text input, cross-lingual voice cloning, and integration with virtual reality environments are all on the near horizon.
For businesses and creators, staying ahead means experimenting with these tools now, understanding their capabilities and limitations, and building workflows that incorporate audio-first thinking alongside traditional text-based strategies.