In the intricate world of data management, the term data waterfall often surfaces to describe a specific methodology for handling information flows. Unlike chaotic and unstructured streams, this concept refers to a systematic approach where data moves through distinct, sequential stages, much like water cascading down a series of steps. This structured progression ensures that each phase of processing is completed before the next one begins, providing a clear and traceable path from initial acquisition to final delivery. Understanding this linear progression is essential for any organization seeking to impose order on complex information ecosystems.
Deconstructing the Data Waterfall Concept
At its core, the data waterfall is a model rooted in traditional engineering and software development practices. It represents a linear and sequential design process, where the output of one stage becomes the direct input for the next. This methodology is characterized by its rigidity and planning, requiring comprehensive documentation and clear objectives before any implementation begins. The allure of this approach lies in its predictability; stakeholders can easily visualize the entire lifecycle of the data, from raw collection through transformation and analysis to archival or deletion. This clarity is particularly valuable in environments where accuracy and compliance are non-negotiable, as it minimizes ambiguity and defines responsibilities at every step of the flow.
The Sequential Stages of Flow
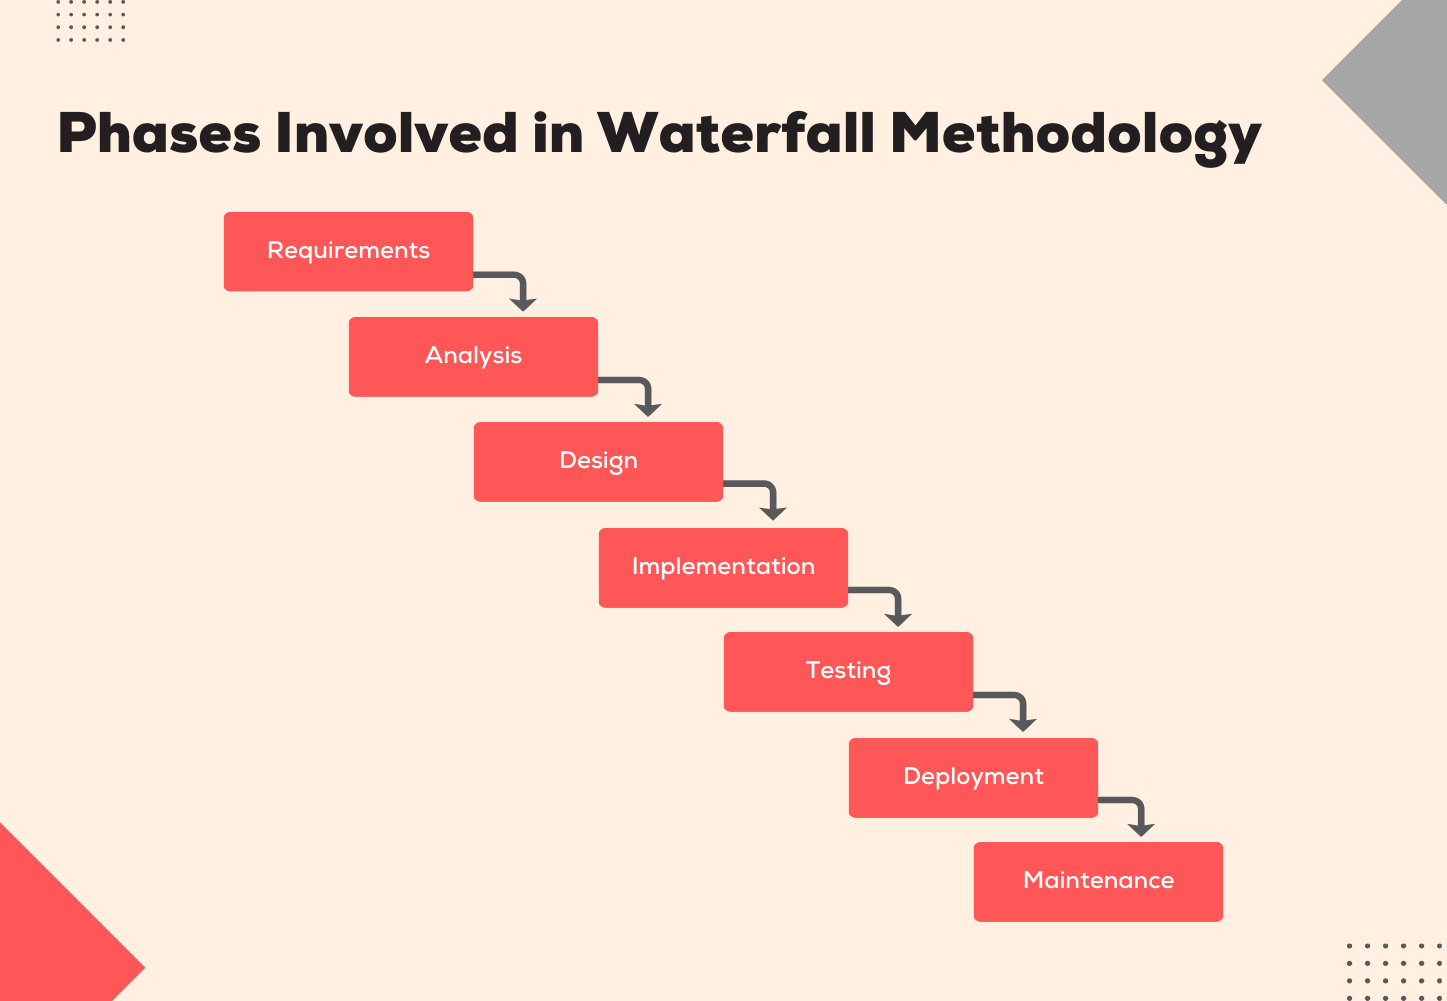
The strength of the data waterfall methodology is defined by its distinct phases, which create a reliable framework for data governance. These stages are typically executed in a strict top-down order, making it difficult to revisit a previous step without restarting the process. The logical progression ensures that errors or inconsistencies are caught early, before they propagate through the system and become more costly to fix. Adhering to this sequence provides a structured environment where data integrity is maintained from the initial entry point to the final output, reducing the risk of chaotic or unmanaged data proliferation.
- Requirement Gathering and Analysis: The foundational stage where business needs and data sources are identified.
- System Design: Architecting the structure and rules for how data will be stored and processed.
- Implementation: The coding and configuration phase where the system is built according to the design.
- Testing: Rigorous verification to ensure the system meets all specified requirements without error.
- Deployment: Releasing the processed data into the live environment for end-user consumption.
- Maintenance: Ongoing monitoring and updates to ensure the system continues to function correctly over time.
Advantages and Ideal Use Cases
One of the primary advantages of adopting a data waterfall strategy is the immense predictability it offers regarding timelines and deliverables. Because the scope is defined upfront, teams can accurately estimate project duration and resource allocation, which is beneficial for budget planning. This model thrives in contexts where the requirements are stable and unlikely to change mid-project. Industries such as finance, healthcare, and regulated government agencies often favor this approach because it creates a clear audit trail. The detailed documentation generated at every stage provides a robust record that is invaluable for compliance audits and regulatory reviews, ensuring that data handling practices are always verifiable.
Comparing Waterfall to Modern Approaches
While the data waterfall provides structure, it is important to understand how it contrasts with more adaptive methodologies, such as Agile. The rigid nature of the waterfall model can be a double-edged sword; it excels in stability but struggles with flexibility. In today’s fast-paced digital landscape, where business requirements can shift rapidly, the inability to easily revisit earlier stages can lead to obsolescence before a project is even completed. Modern alternatives often favor iterative development, allowing for constant feedback and incremental changes. However, the data waterfall remains a vital tool for specific high-stakes environments where precision and exhaustive planning are significantly more critical than speed and adaptability.
Visualizing the Data Journey
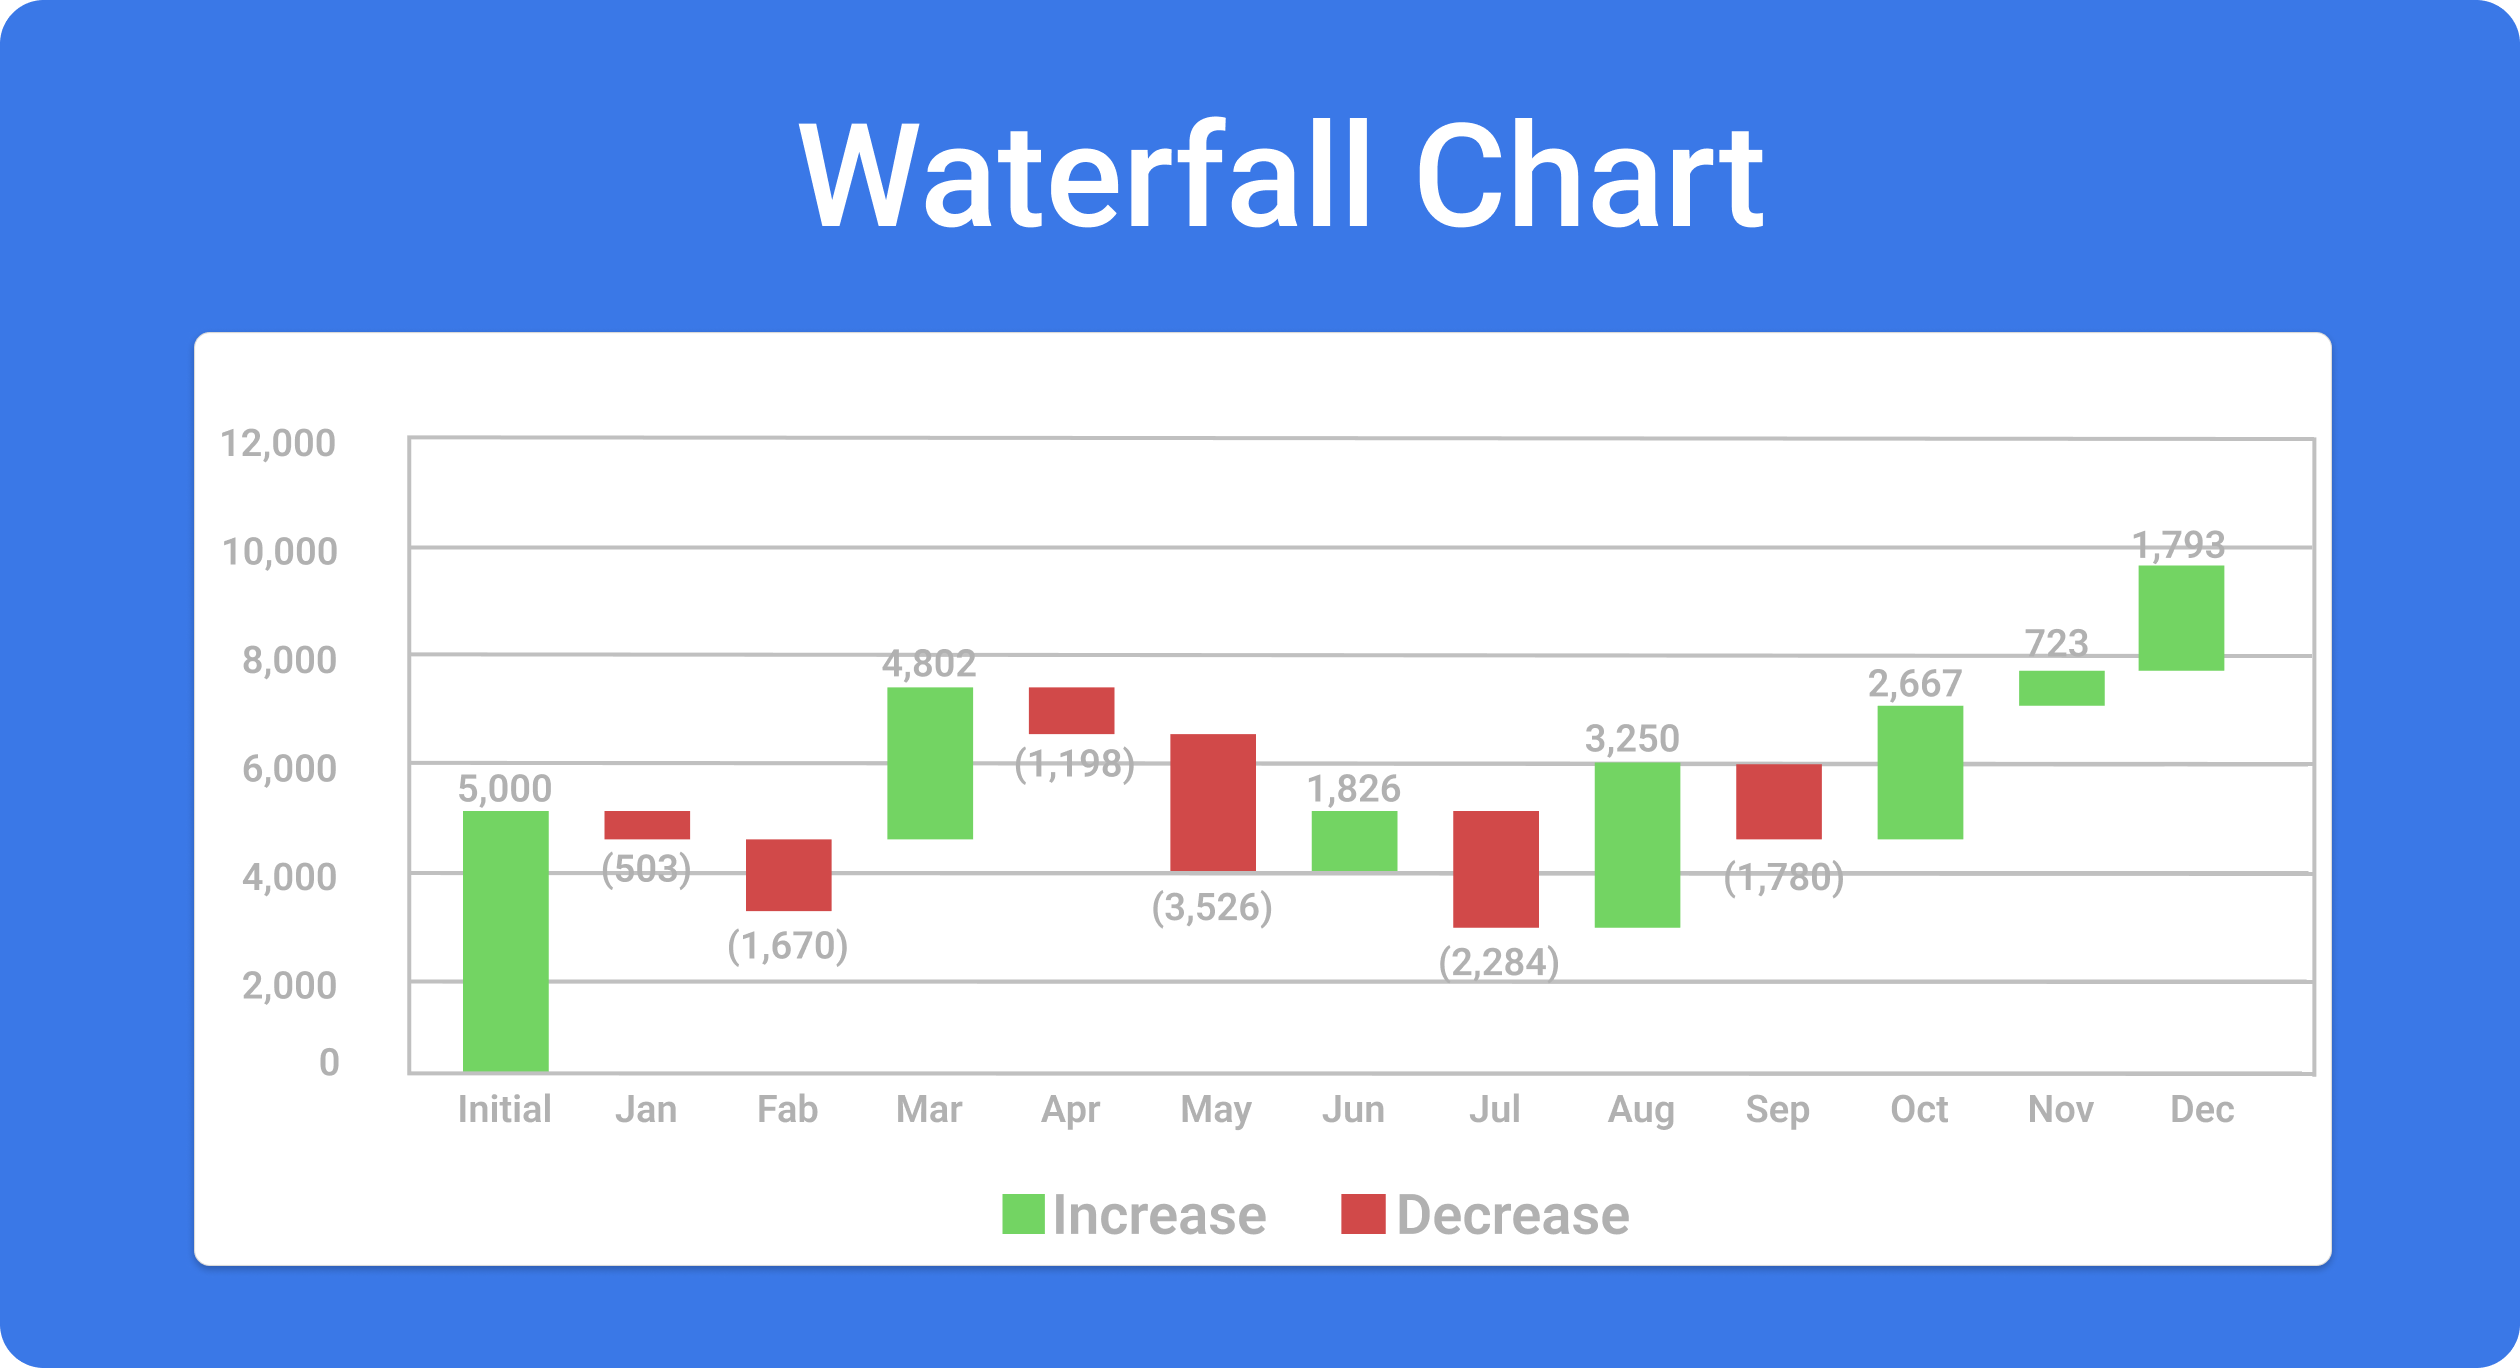
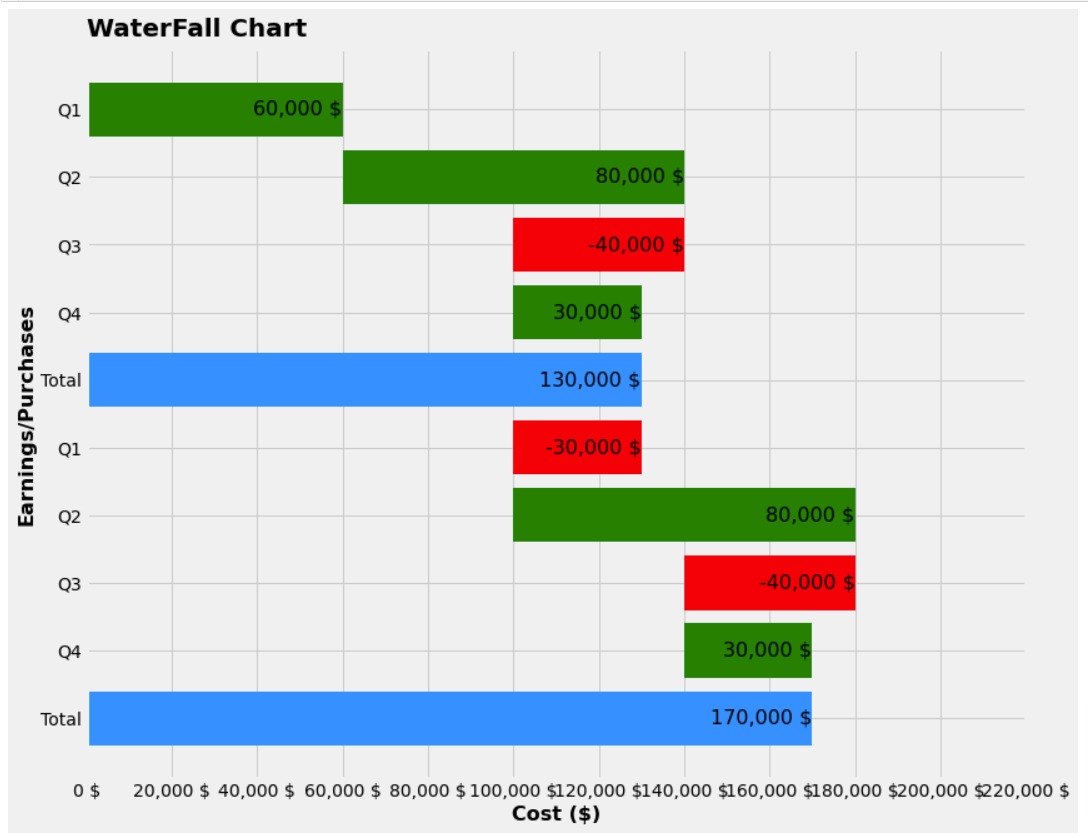
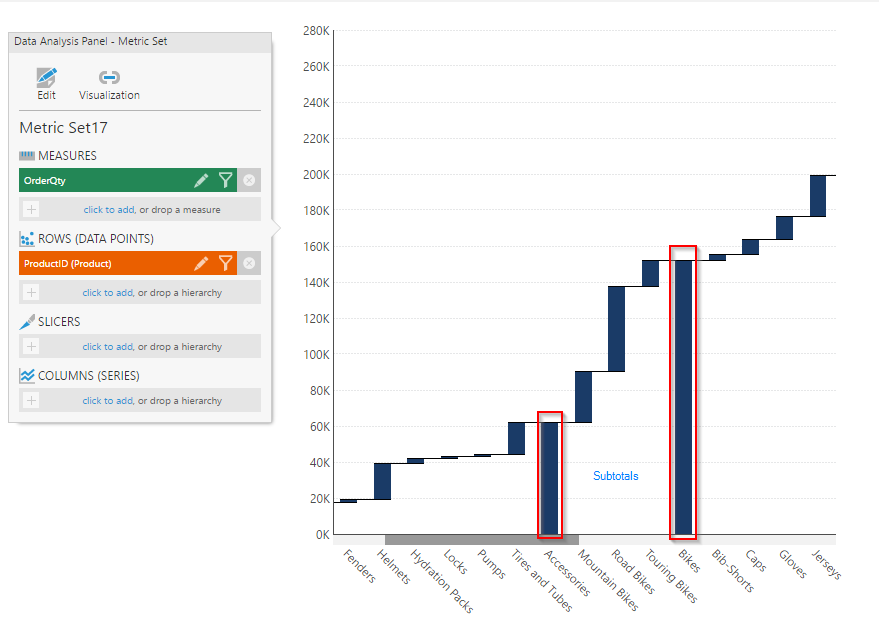
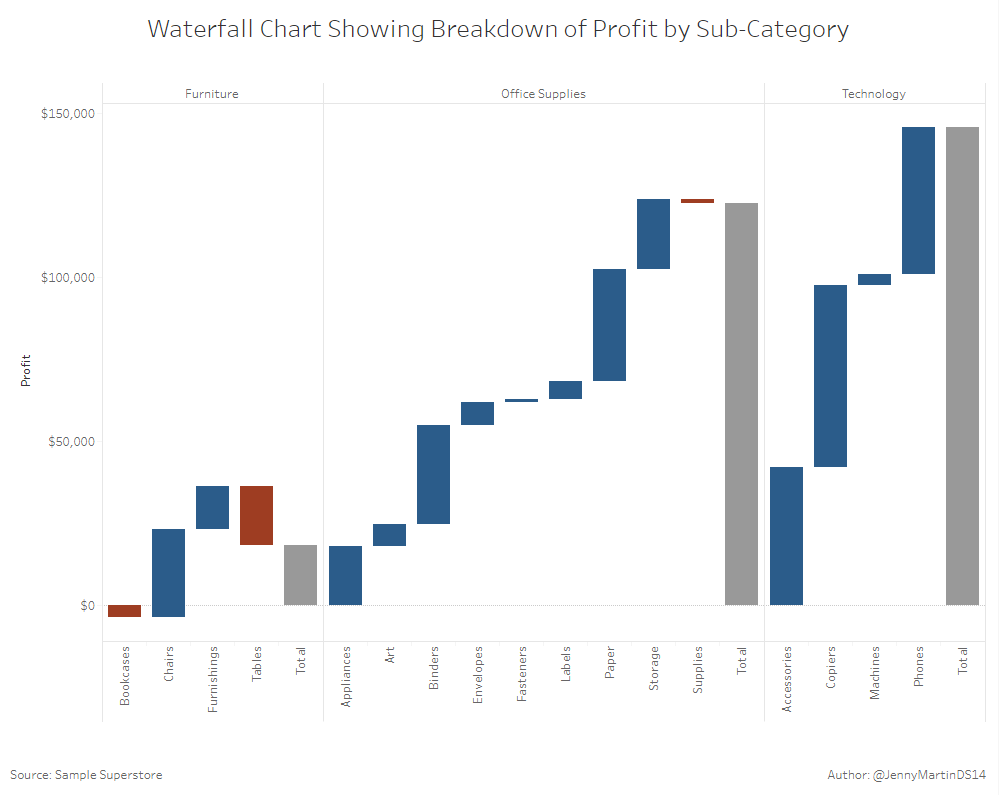
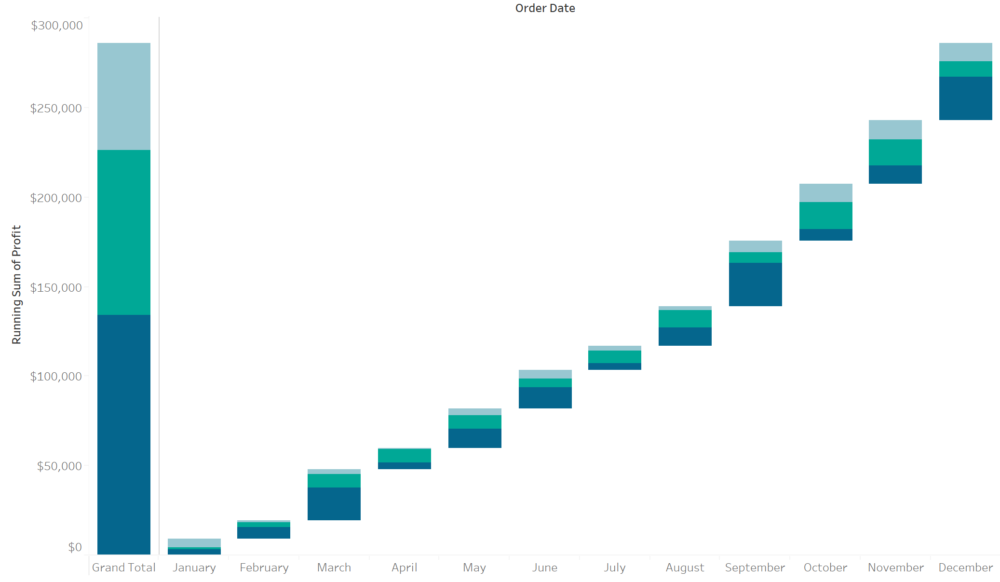
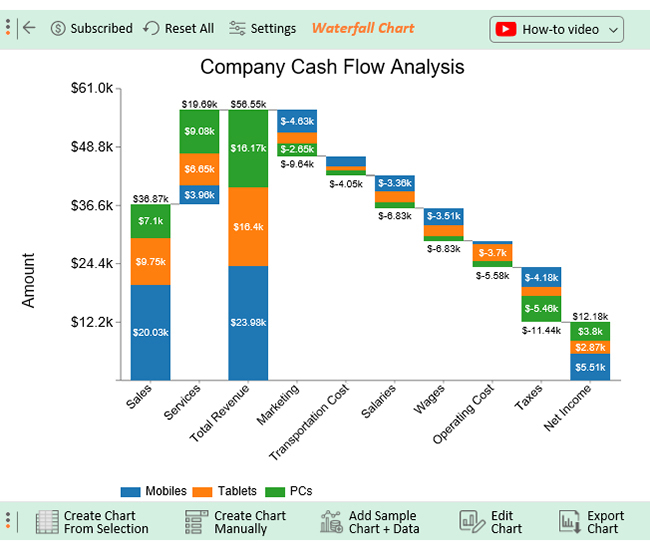
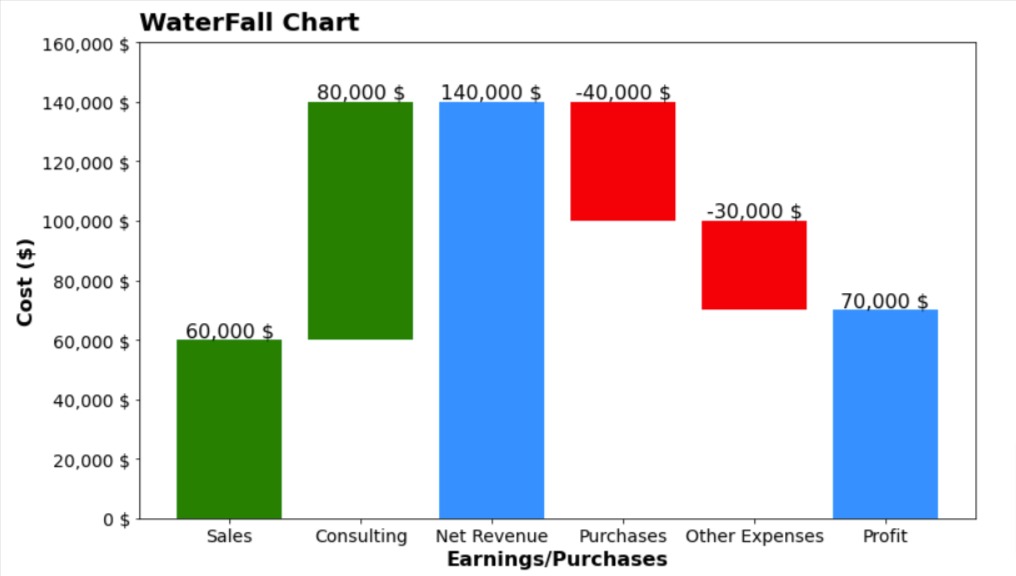
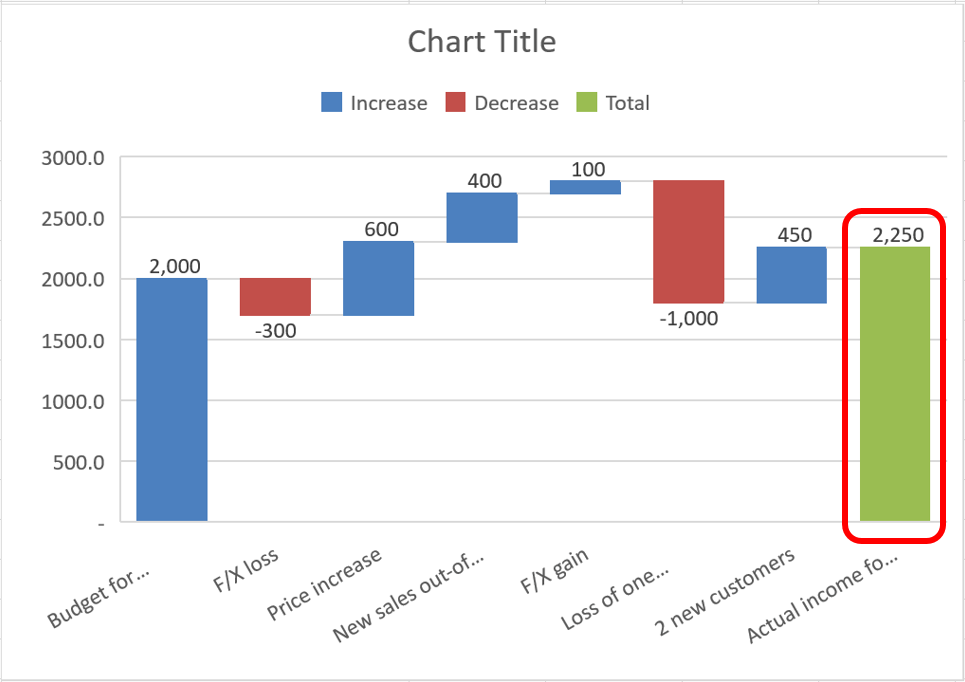
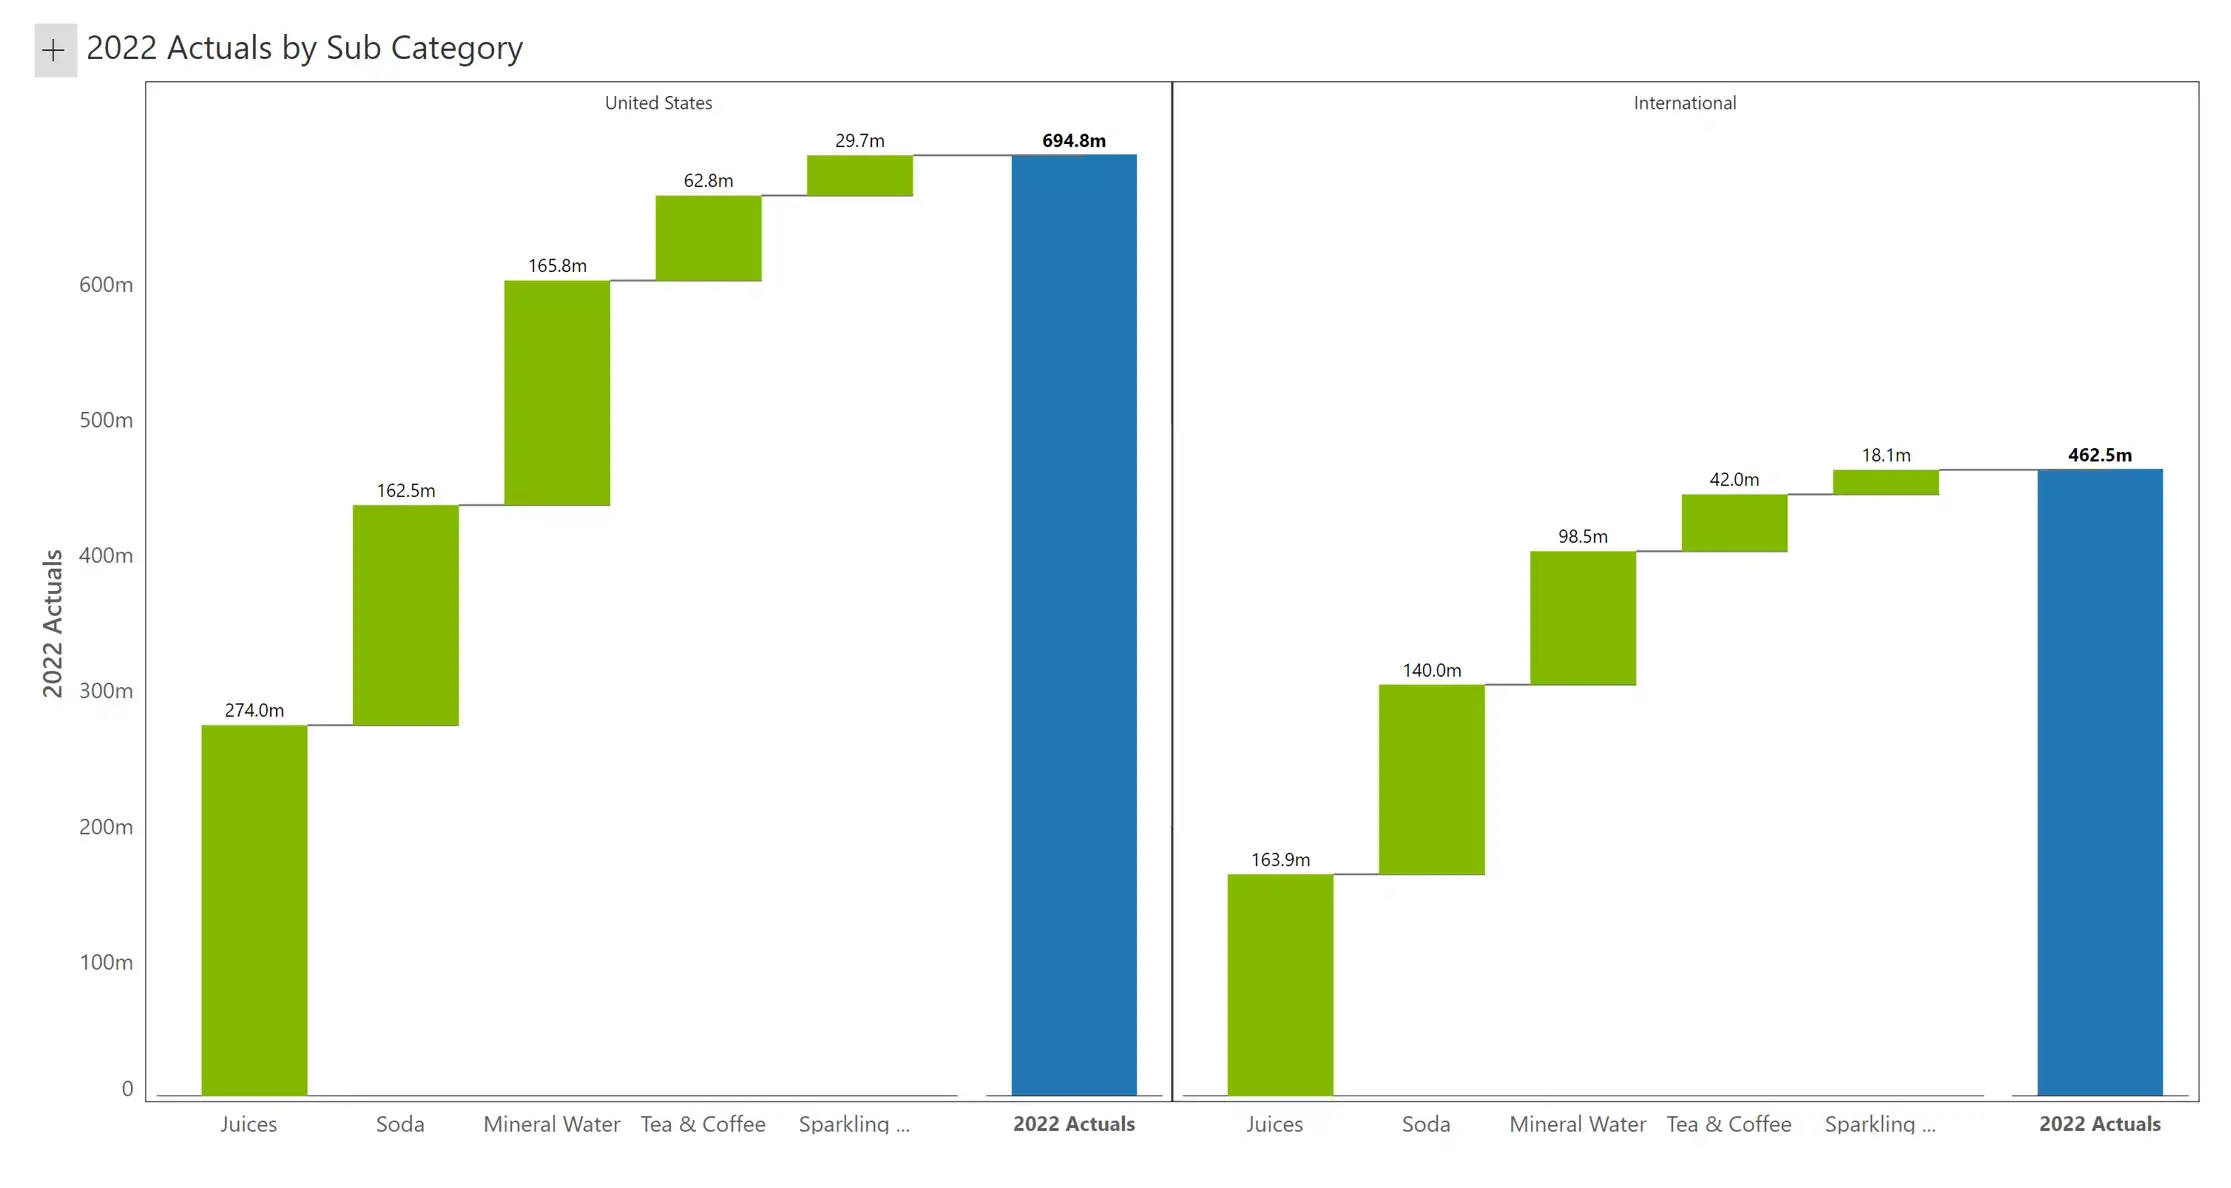
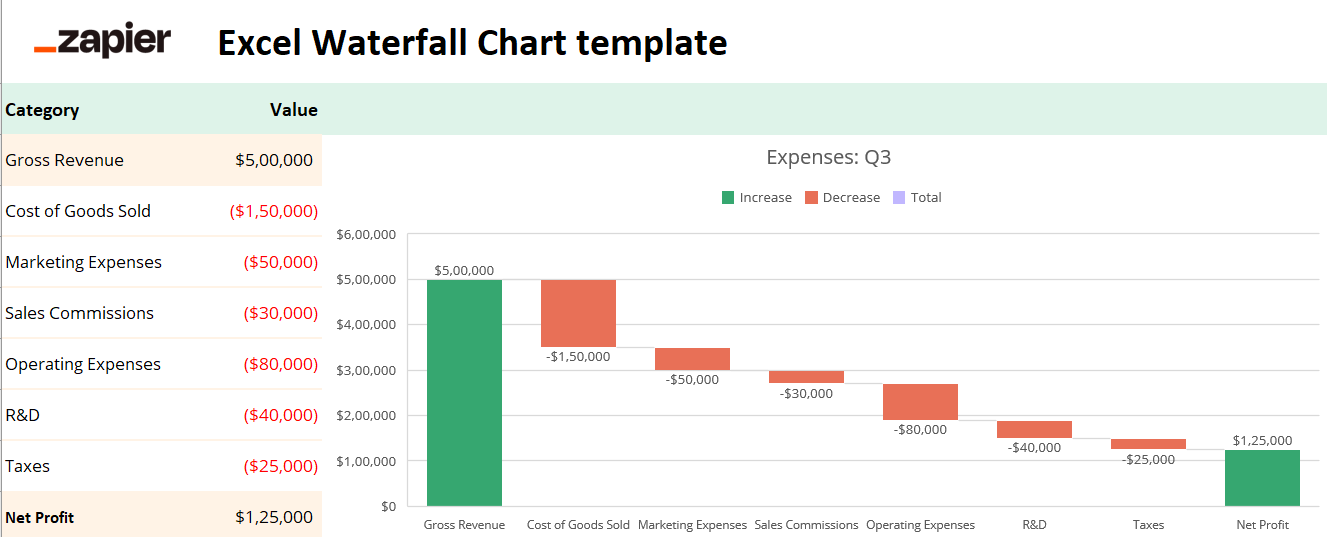
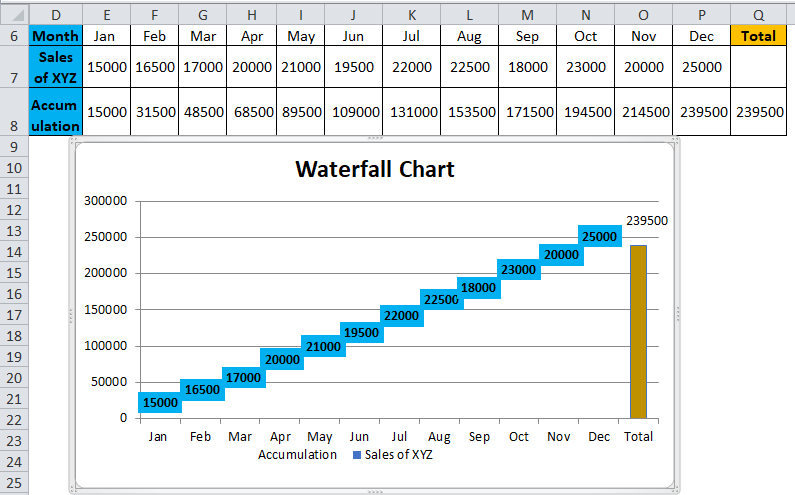
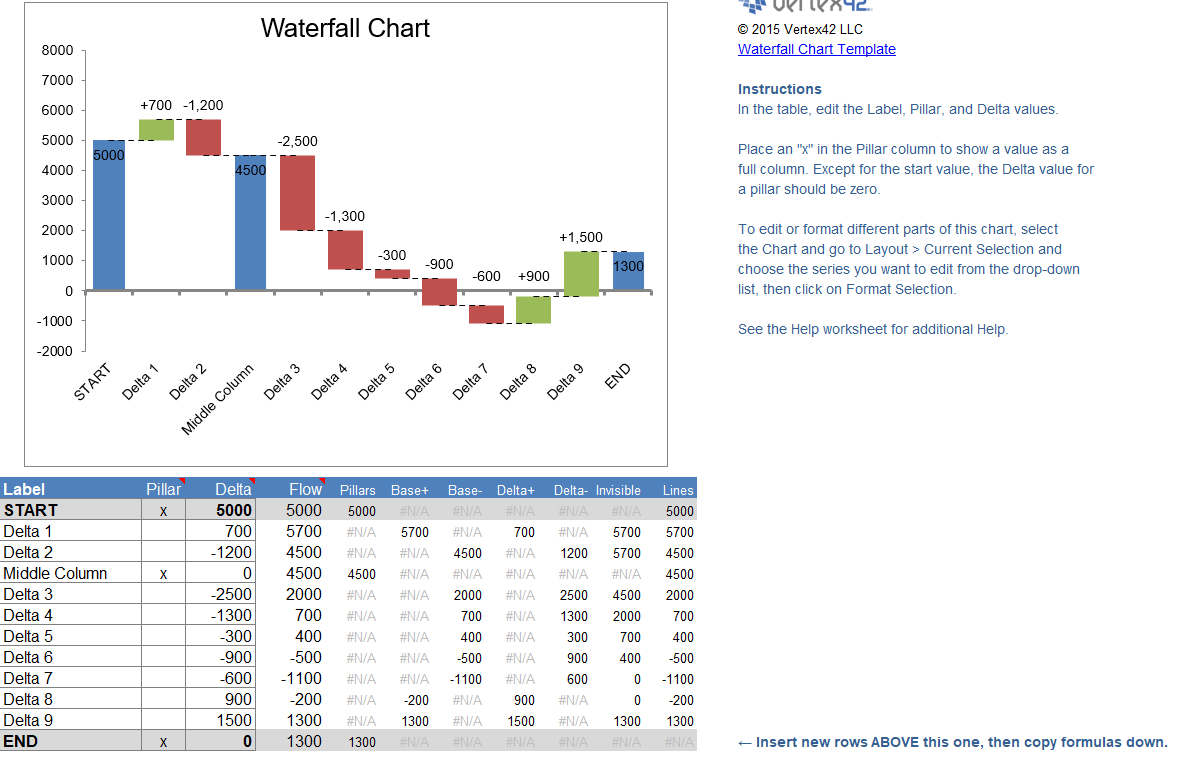
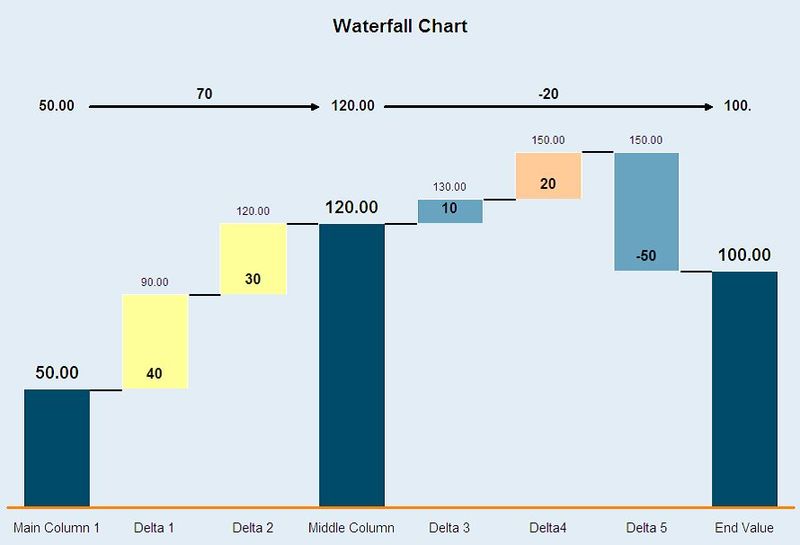
The visual representation of the data waterfall is perhaps the most effective way to understand its mechanics. Imagine a series of cascading blocks or levels, where data accumulates and transforms as it moves downward. This visual flow eliminates backtracking, emphasizing the importance of getting each phase right the first time. The progression is clear and linear, making it an excellent tool for communicating project status to stakeholders who need a high-level overview. This visual clarity helps bridge the gap between technical teams and decision-makers, ensuring that everyone shares a common understanding of the data's path and the project's current position within the lifecycle.

Ultimately, the data waterfall is more than just a technical process; it is a philosophy of data management that prioritizes order and discipline. It serves as a foundational concept that helps organizations structure their information strategies deliberately. By recognizing when this rigid structure is beneficial and when a more flexible approach is needed, data professionals can leverage this model to ensure reliability, compliance, and successful project execution in a complex data-driven world.