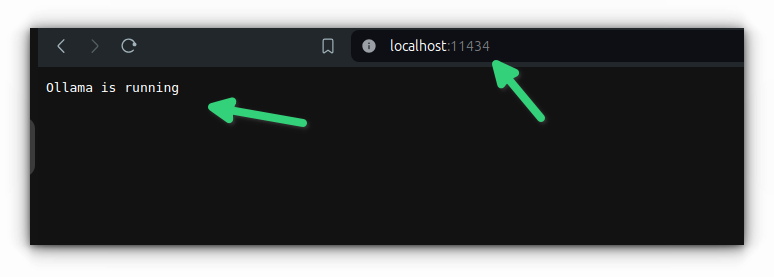
Learn how to check if Ollama is running with step.
If you see a message saying, "no compatible GPUs were discovered," then it's a good indication Ollama defaulted to using your CPU. Run ollama serve Running Ollama in server mode without entering chat mode can also give you clues. Make sure and quit Ollama if it's already running, then open a command prompt and type ollama serve.
Wouldn't it be useful to have a method to check if ollama is running (if the server is active) or not? IMO it would make more sense to call it before say ollama.chat, instead of directly calling ol.
Check If Ollama Server Is Running Or Not · Issue #405 · Ollama/ollama ...
Implementation guide: your 30‑minute quickstart Install Ollama for your OS and verify ollama --version. ollama pull llama3 and run a quick chat to confirm. Start ollama serve and hit /api/generate with cURL. Wrap a tiny Node/Go/Python app around the API and stream tokens. Add a simple RAG: chunk one PDF, embed, retrieve, and ground responses.
Learn to monitor GPU usage in Ollama with built.
Ollama is a tool used to run the open-weights large language models locally. It's quick to install, pull the LLM models and start prompting in your terminal / command prompt. This tutorial should serve as a good reference for anything you wish to do with Ollama, so bookmark it and let's get started. What is Ollama Tutorial: Your Guide to running LLMs Locally.
A guide to running LLMs locally using Ollama, including installation, model setup, server usage, API calls, Python integration, and real.
How To Run Ollama On Windows
Learn to monitor GPU usage in Ollama with built.
Implementation guide: your 30‑minute quickstart Install Ollama for your OS and verify ollama --version. ollama pull llama3 and run a quick chat to confirm. Start ollama serve and hit /api/generate with cURL. Wrap a tiny Node/Go/Python app around the API and stream tokens. Add a simple RAG: chunk one PDF, embed, retrieve, and ground responses.
If you see a message saying, "no compatible GPUs were discovered," then it's a good indication Ollama defaulted to using your CPU. Run ollama serve Running Ollama in server mode without entering chat mode can also give you clues. Make sure and quit Ollama if it's already running, then open a command prompt and type ollama serve.
Do you know for sure if Ollama is utilizing your GPU? Or is it using your CPU? In this video I show you four ways to check.0:00 Intro1:00 What is covered in.
Ollama Commands: How To Use Ollama In The Command Line
Implementation guide: your 30‑minute quickstart Install Ollama for your OS and verify ollama --version. ollama pull llama3 and run a quick chat to confirm. Start ollama serve and hit /api/generate with cURL. Wrap a tiny Node/Go/Python app around the API and stream tokens. Add a simple RAG: chunk one PDF, embed, retrieve, and ground responses.
Do you know for sure if Ollama is utilizing your GPU? Or is it using your CPU? In this video I show you four ways to check.0:00 Intro1:00 What is covered in.
Ollama is a tool used to run the open-weights large language models locally. It's quick to install, pull the LLM models and start prompting in your terminal / command prompt. This tutorial should serve as a good reference for anything you wish to do with Ollama, so bookmark it and let's get started. What is Ollama Tutorial: Your Guide to running LLMs Locally.
Wouldn't it be useful to have a method to check if ollama is running (if the server is active) or not? IMO it would make more sense to call it before say ollama.chat, instead of directly calling ol.
Running AI Locally Using Ollama On Ubuntu Linux
Implementation guide: your 30‑minute quickstart Install Ollama for your OS and verify ollama --version. ollama pull llama3 and run a quick chat to confirm. Start ollama serve and hit /api/generate with cURL. Wrap a tiny Node/Go/Python app around the API and stream tokens. Add a simple RAG: chunk one PDF, embed, retrieve, and ground responses.
If you see a message saying, "no compatible GPUs were discovered," then it's a good indication Ollama defaulted to using your CPU. Run ollama serve Running Ollama in server mode without entering chat mode can also give you clues. Make sure and quit Ollama if it's already running, then open a command prompt and type ollama serve.
The easiest way to check if Ollama is actually using your GPU is to run the ollama ps command while a model is loaded (e.g., immediately after starting ollama run in another terminal, or while an API request is being processed).
Learn to monitor GPU usage in Ollama with built.
Implement Check To Determine If Ollama Is Already Running Before ...
Do you know for sure if Ollama is utilizing your GPU? Or is it using your CPU? In this video I show you four ways to check.0:00 Intro1:00 What is covered in.
Learn how to check if Ollama is running with step.
If you see a message saying, "no compatible GPUs were discovered," then it's a good indication Ollama defaulted to using your CPU. Run ollama serve Running Ollama in server mode without entering chat mode can also give you clues. Make sure and quit Ollama if it's already running, then open a command prompt and type ollama serve.
Implementation guide: your 30‑minute quickstart Install Ollama for your OS and verify ollama --version. ollama pull llama3 and run a quick chat to confirm. Start ollama serve and hit /api/generate with cURL. Wrap a tiny Node/Go/Python app around the API and stream tokens. Add a simple RAG: chunk one PDF, embed, retrieve, and ground responses.
Learn to monitor GPU usage in Ollama with built.
Wouldn't it be useful to have a method to check if ollama is running (if the server is active) or not? IMO it would make more sense to call it before say ollama.chat, instead of directly calling ol.
Ollama is a tool used to run the open-weights large language models locally. It's quick to install, pull the LLM models and start prompting in your terminal / command prompt. This tutorial should serve as a good reference for anything you wish to do with Ollama, so bookmark it and let's get started. What is Ollama Tutorial: Your Guide to running LLMs Locally.
Do you know for sure if Ollama is utilizing your GPU? Or is it using your CPU? In this video I show you four ways to check.0:00 Intro1:00 What is covered in.
The easiest way to check if Ollama is actually using your GPU is to run the ollama ps command while a model is loaded (e.g., immediately after starting ollama run in another terminal, or while an API request is being processed).
Implementation guide: your 30‑minute quickstart Install Ollama for your OS and verify ollama --version. ollama pull llama3 and run a quick chat to confirm. Start ollama serve and hit /api/generate with cURL. Wrap a tiny Node/Go/Python app around the API and stream tokens. Add a simple RAG: chunk one PDF, embed, retrieve, and ground responses.
Running models with Ollama step-by-step Looking for a way to quickly test LLM without setting up the full infrastructure? That's great because that's exactly what we're about to do in this.
If you see a message saying, "no compatible GPUs were discovered," then it's a good indication Ollama defaulted to using your CPU. Run ollama serve Running Ollama in server mode without entering chat mode can also give you clues. Make sure and quit Ollama if it's already running, then open a command prompt and type ollama serve.
A guide to running LLMs locally using Ollama, including installation, model setup, server usage, API calls, Python integration, and real.
Learn how to check if Ollama is running with step.