Understanding the distinction between white space and non whitespace is fundamental for anyone working with text, code, or data. While often invisible to the casual observer, these characters play distinct roles in structuring information and influencing how systems interpret content. White space characters, such as spaces, tabs, and line breaks, are designed to create visual separation and improve readability. Conversely, non whitespace characters encompass every visible letter, number, symbol, and control character that carries specific semantic meaning. This difference is not merely academic; it directly impacts search engine optimization, code compilation, and data parsing accuracy.
The Technical Definition of White Space
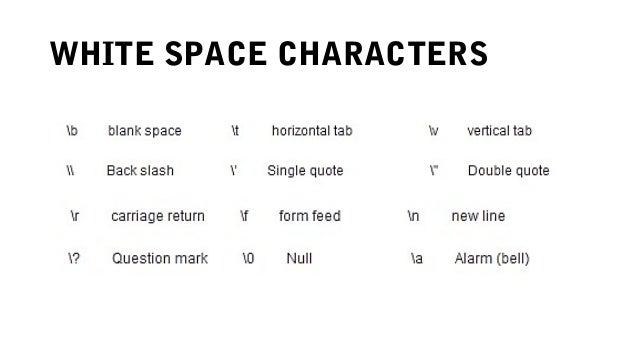
In computing, white space refers to a specific set of characters reserved for formatting rather than content. These characters occupy physical space on a screen or page but do not convey intrinsic information like a letter or number. The most common examples include the standard space (ASCII 32), tab characters, carriage returns, and newline feeds. Search engines, for instance, treat consecutive white space characters as a single space, meaning that keyword stuffing with extra spaces offers no ranking benefit and can even trigger spam filters. Recognizing what qualifies as white space is the first step in mastering text manipulation.
Common White Space Characters
- Space ( )
- Tab (↹)
- Newline (\n)
- Carriage Return (\r)
- Form Feed (\f)
The Role of Non Whitespace Characters
Non whitespace characters form the backbone of any meaningful communication in digital environments. These are the visible symbols that carry specific instructions or represent data. In a programming context, characters like "x", "4", "@", and "/" define variables, operators, and functions. In natural language processing, every letter and punctuation mark contributes to the semantic weight of a sentence. Unlike white space, which organizes, non whitespace characters fundamentally define the content itself, acting as the irreducible elements of information.

Impact on Web Development and SEO
The interplay between white space and non whitespace characters is critical in web development and search engine optimization. While search engines ignore excess white space in HTML, they rely entirely on the sequence and density of non whitespace characters to determine the relevance of a page. For example, the words "login" and "log in" differ because of a single space, a white space character that changes the grammatical structure and user intent. Furthermore, code minification—a process that strips unnecessary white space—demonstrates how white space is a convenience for humans, whereas non whitespace characters are the functional requirement for machines.
Optimizing Content Structure
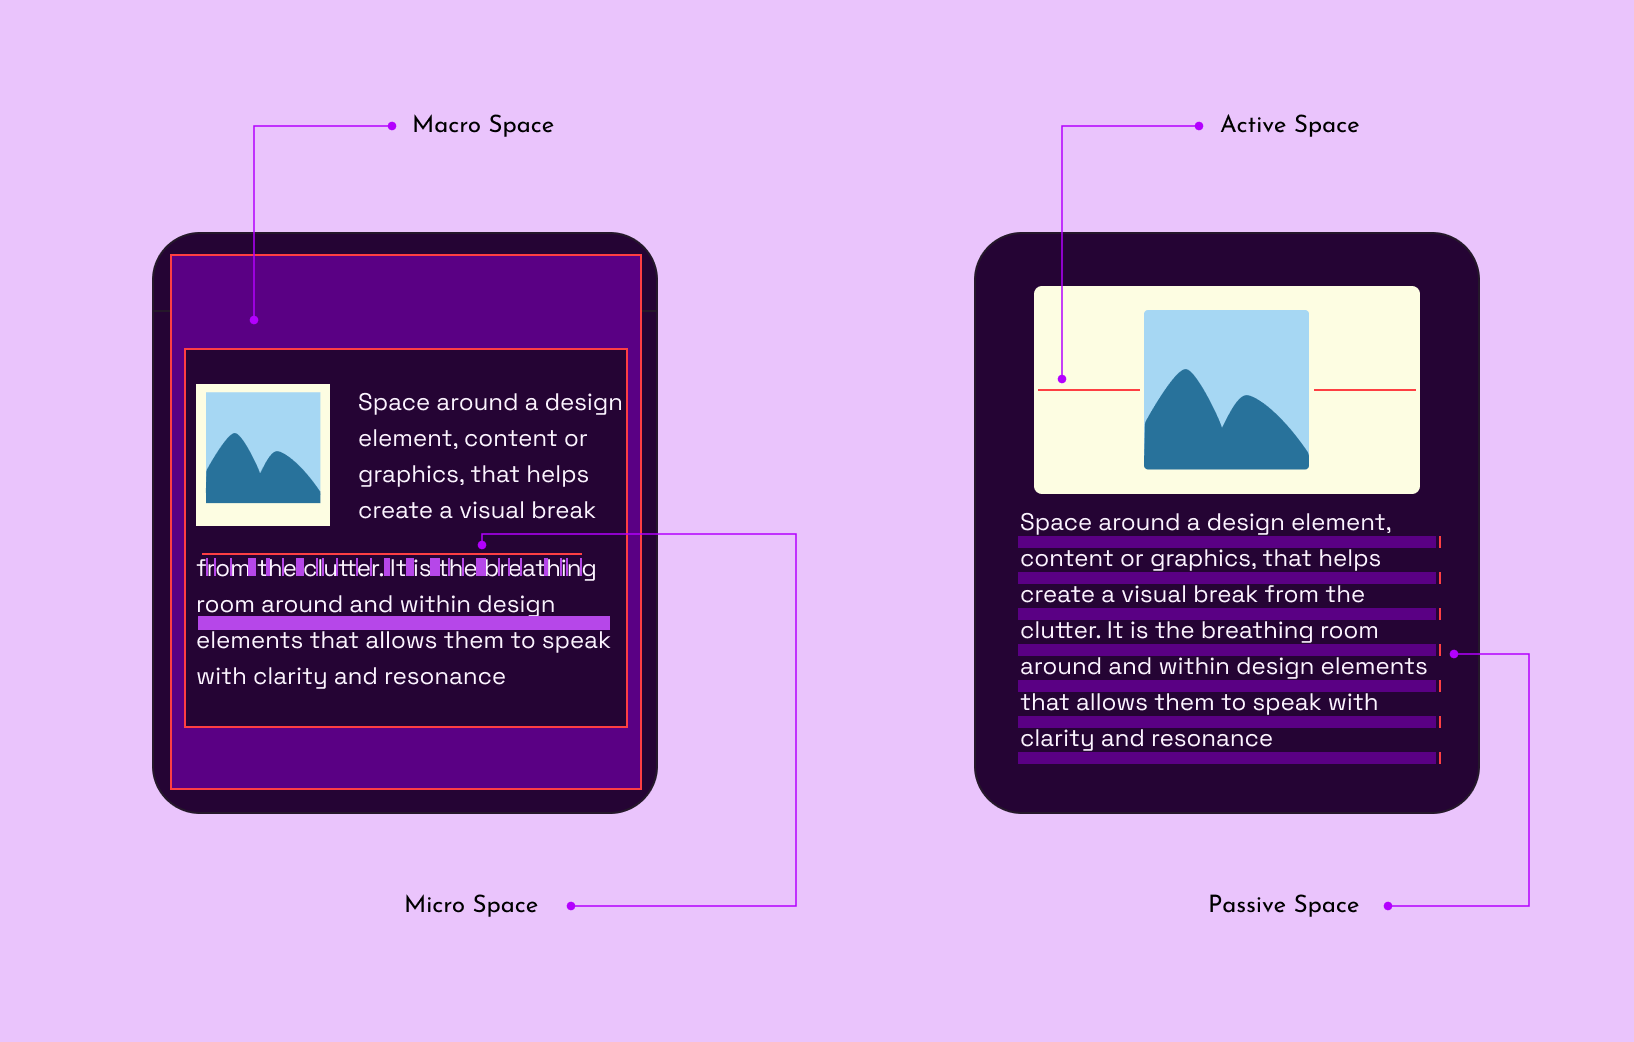
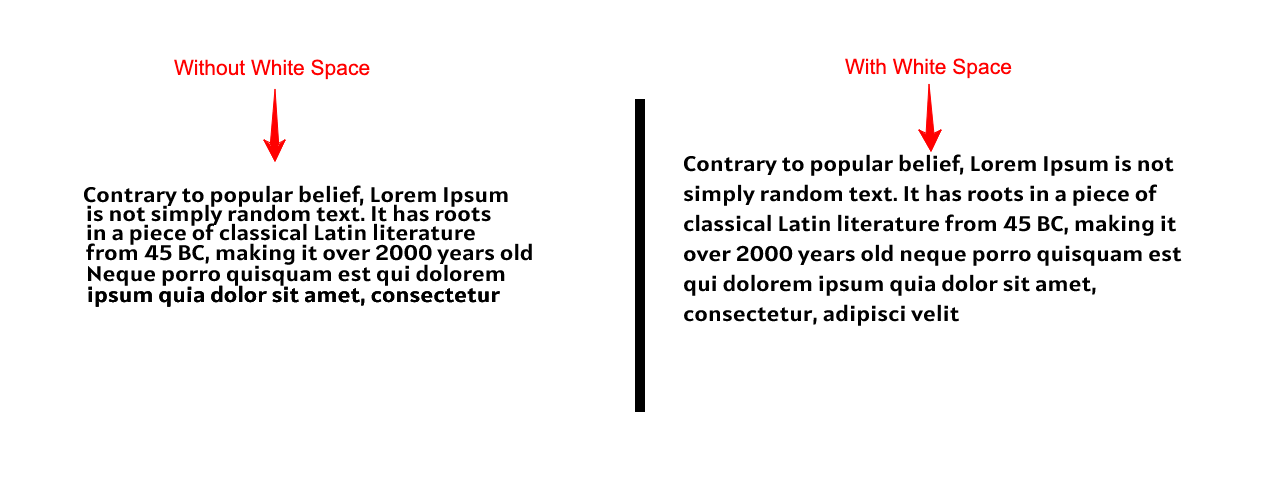
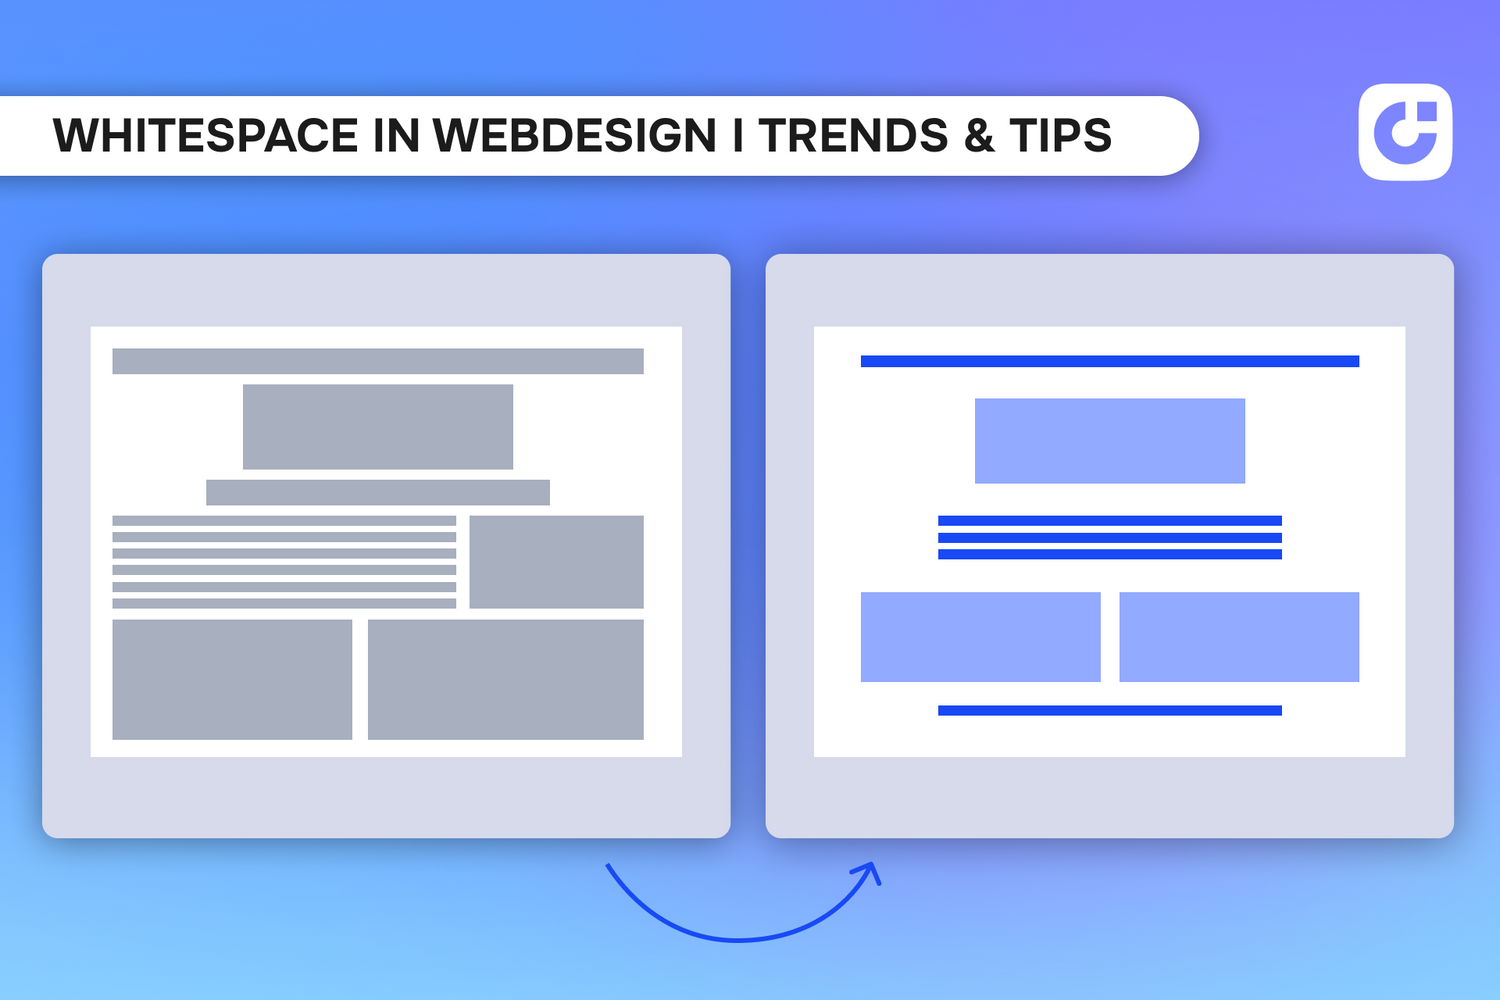
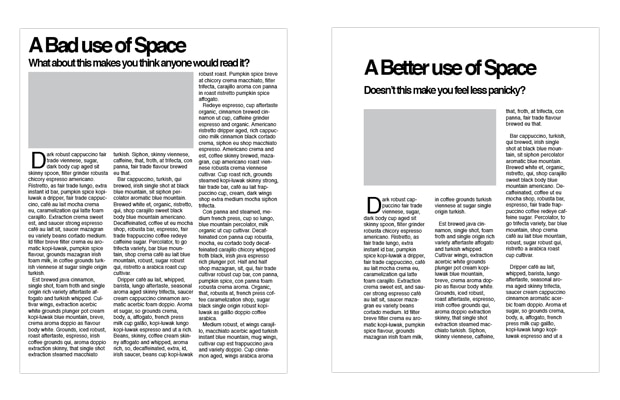
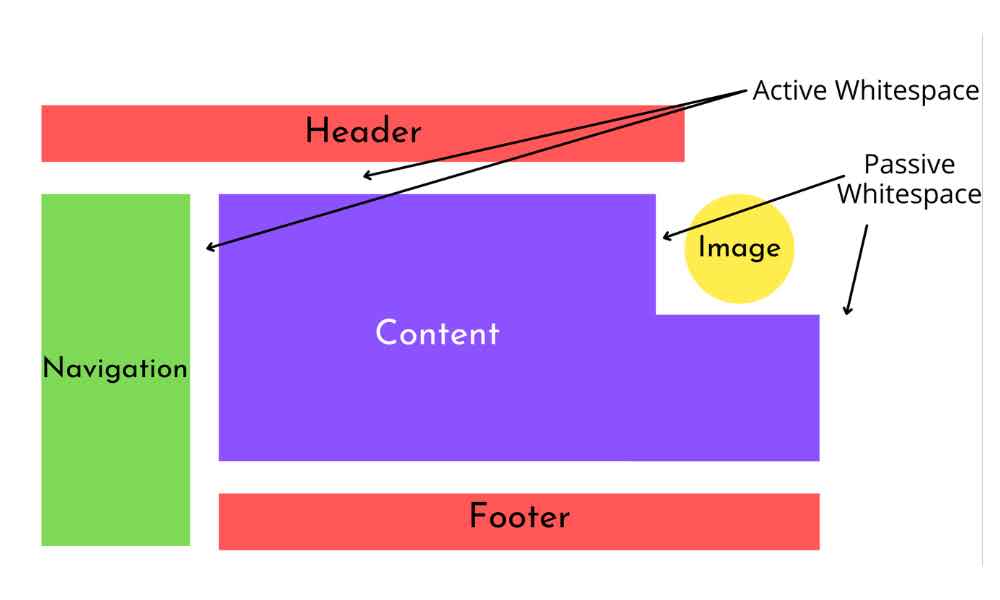
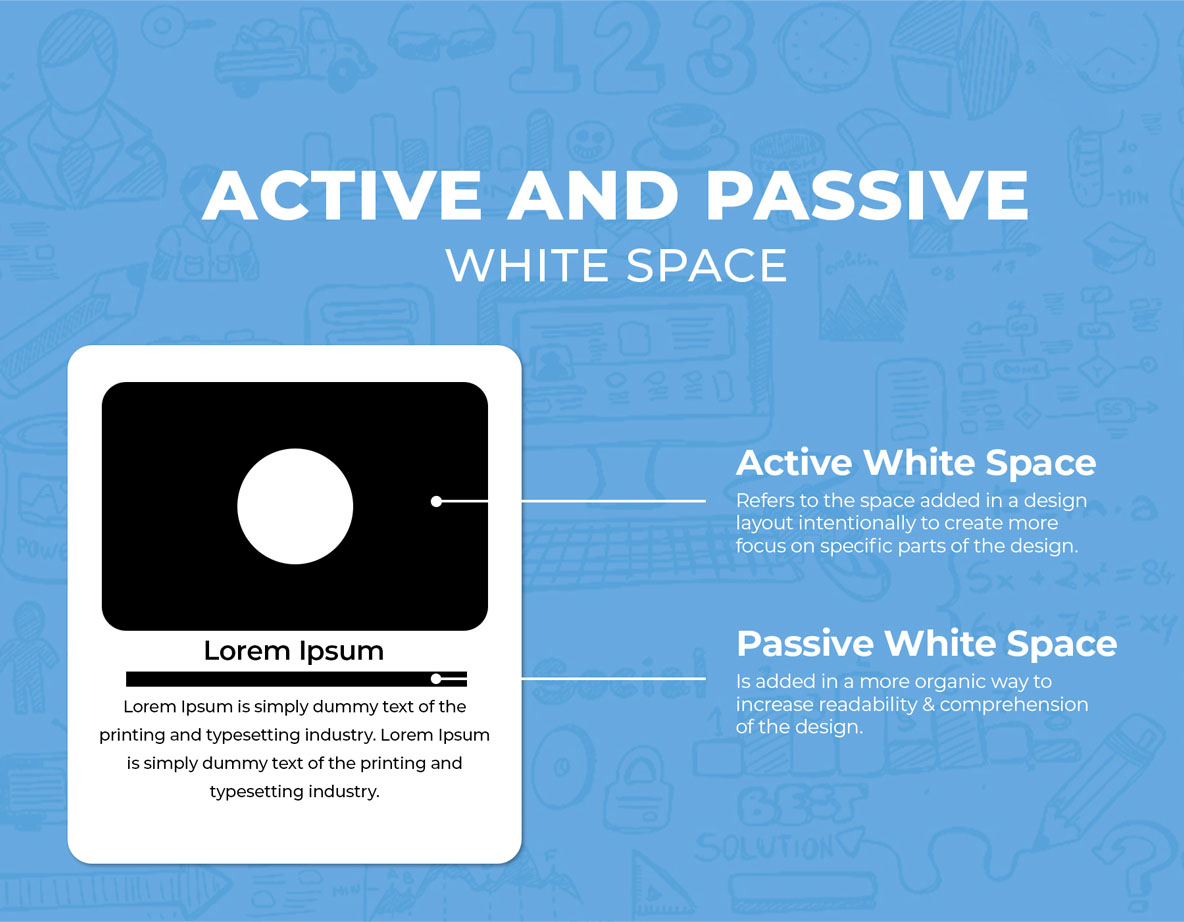
Effective content strategy requires balancing these two elements. Overuse of non whitespace characters without adequate white space creates visual noise, leading to high bounce rates as users struggle to scan content. Conversely, excessive white space without substantial non whitespace characters results in empty layouts that fail to convey value. The ideal approach leverages white space as a design tool to guide the eye through dense clusters of information composed of non whitespace characters, ensuring both aesthetic appeal and functional clarity.
Programming and Data Parsing
In the realm of programming, the distinction is often a matter of syntax and execution. Languages like Python use indentation—composed of white space characters—to define code blocks, making it a syntactic element rather than just formatting. In contrast, non whitespace characters determine the logic and flow of the program. Misplacing a white space, such as an unintended space in a file path or command, can cause scripts to fail, while altering a single non whitespace character can change a variable name and break a function. Data formats like JSON and CSV rely strictly on the exclusion of certain white space characters within non whitespace values to maintain structural integrity.
Security and Validation Considerations
Security protocols often scrutinize the boundary between white space and non whitespace characters to prevent injection attacks. For instance, SQL injections or command injection exploits may attempt to inject malicious commands that rely on specific white space characters to execute. Validating user input requires strict parsing rules to trim leading and trailing white space from non whitespace input, ensuring that data is clean and safe for processing. Understanding this boundary allows developers to sanitize inputs effectively, stripping out dangerous formatting while preserving the integrity of the essential non whitespace data.