A Modern Framework for Precision
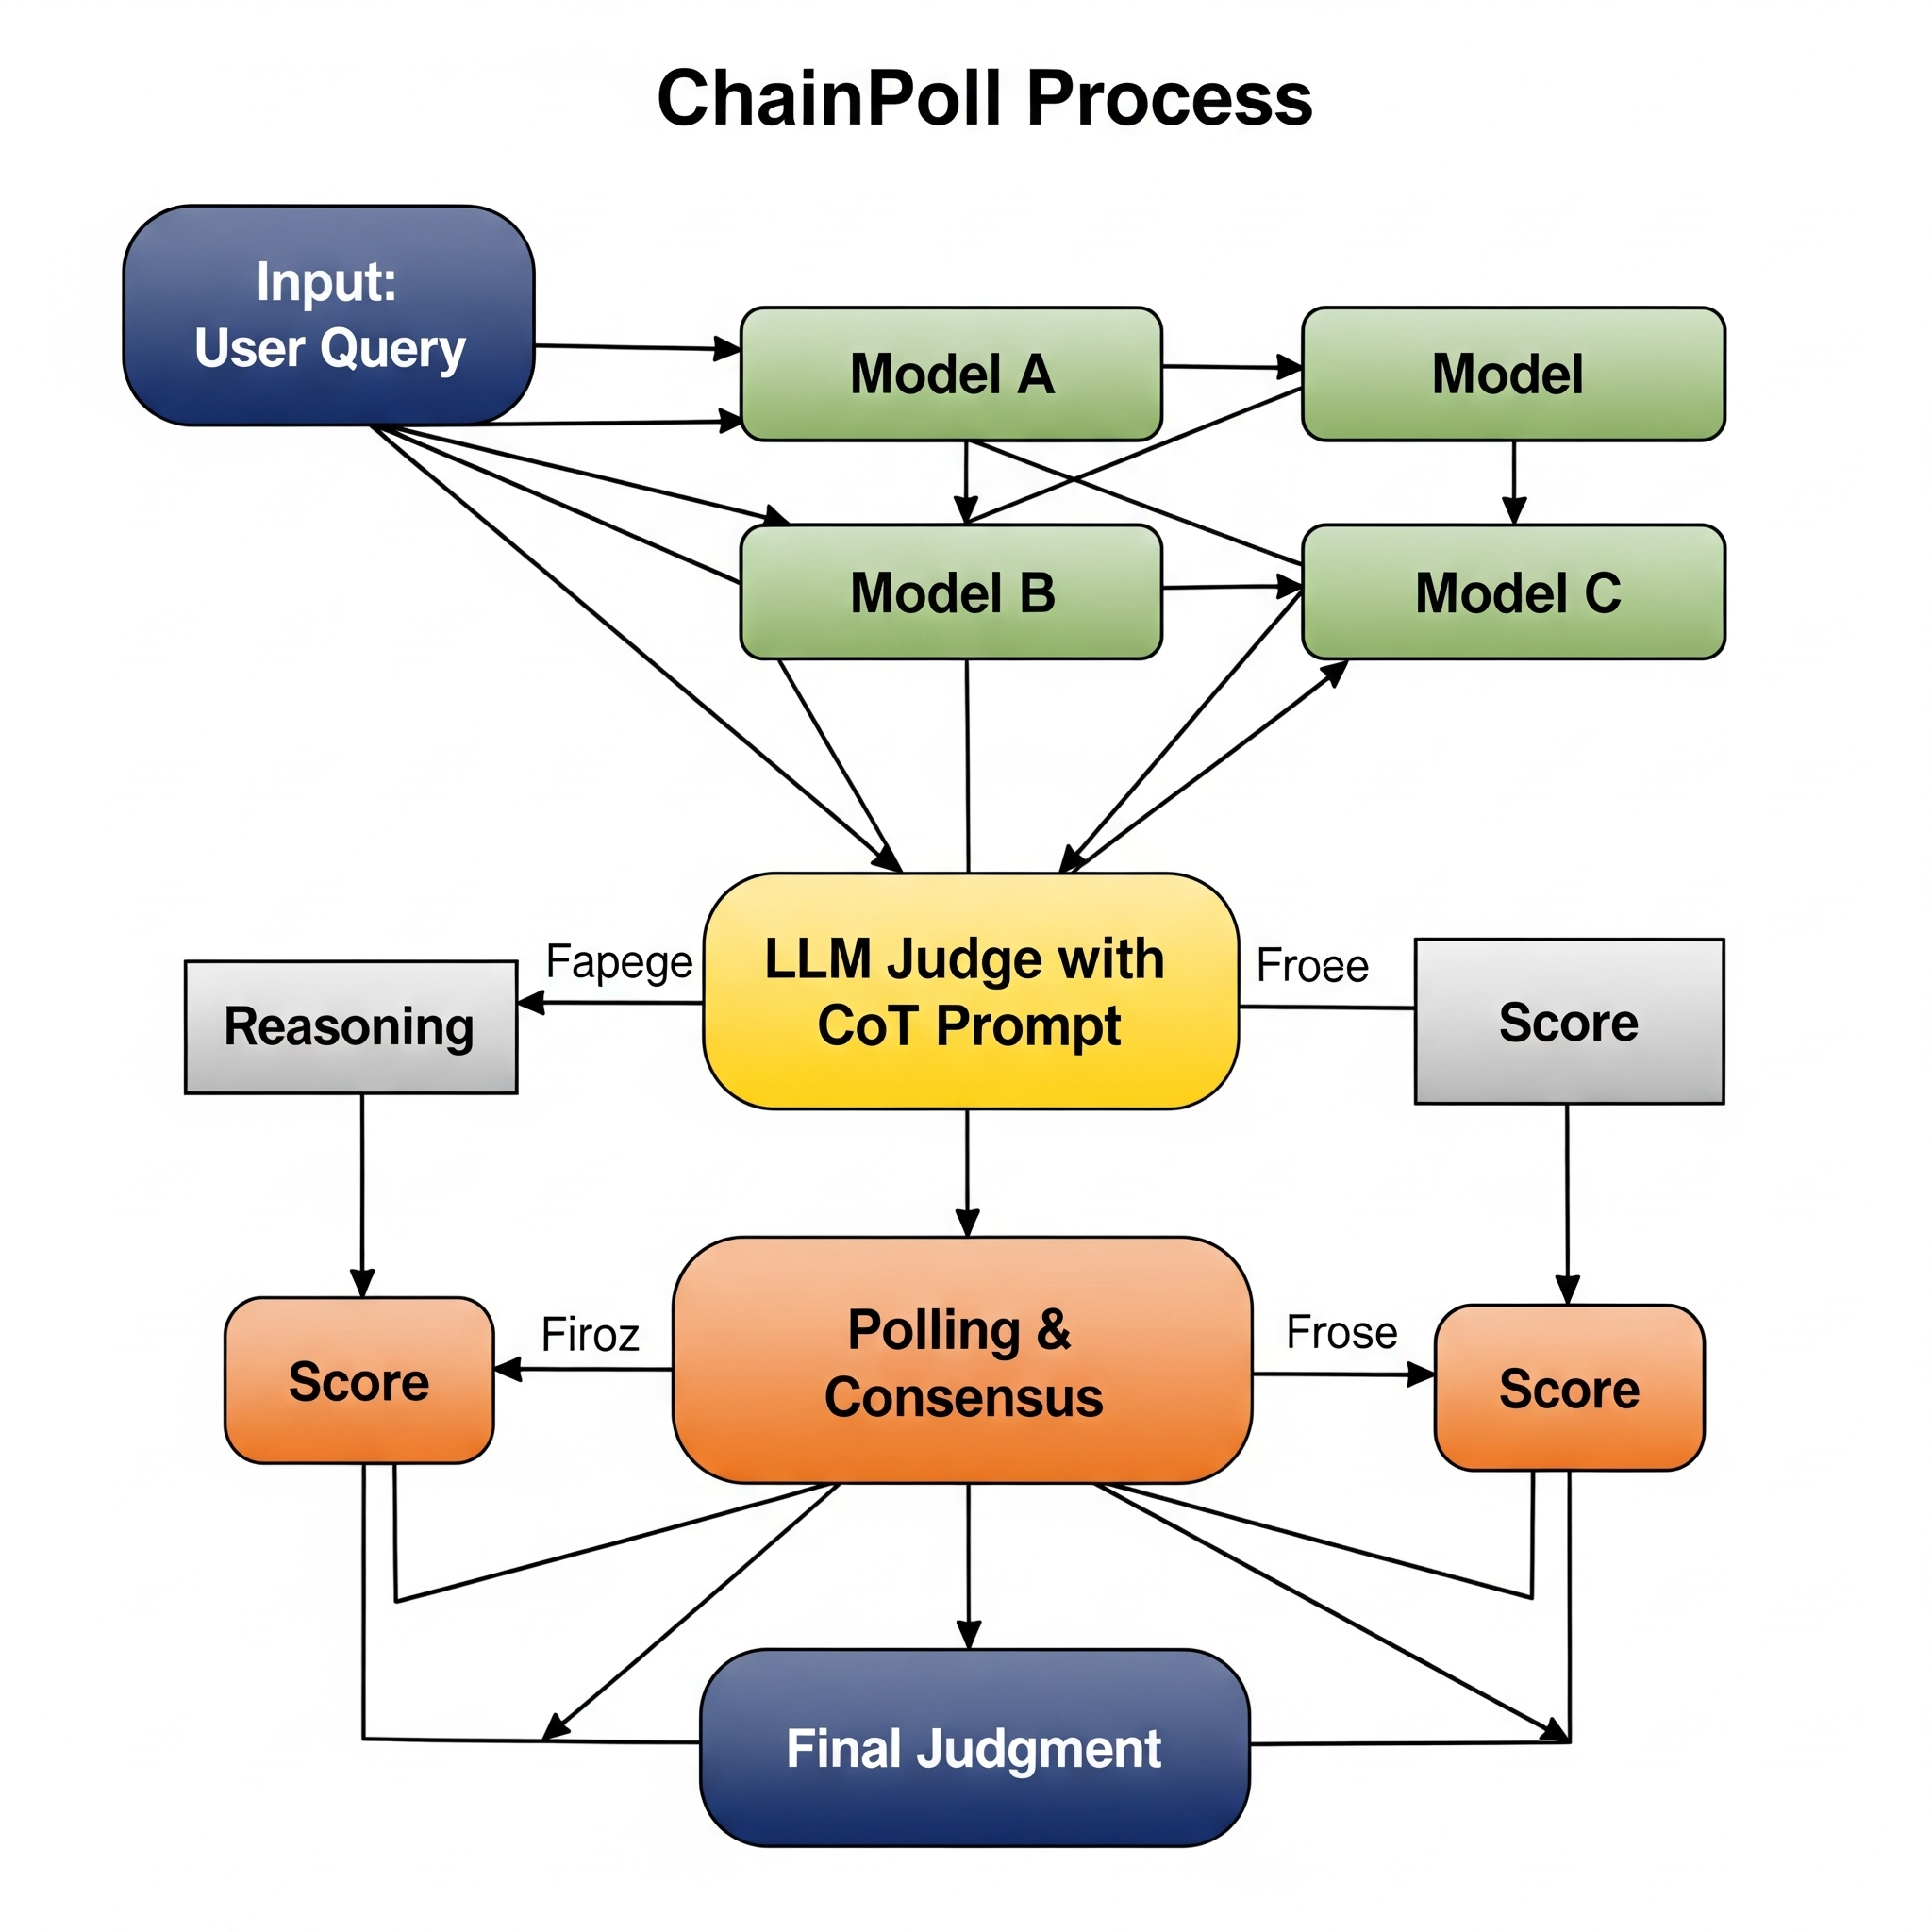
When is it appropriate to use LLM - as -a- Judge ? This approach is best suited for tasks requiring a high degree of qualitative assessment, such as summarization, creative writing, or conversational AI . It is an indispensable tool for a comprehensive evaluation framework , complementing rather than replacing traditional metrics.

LLM Response Evaluation with LLM - as -a- Judge The challenge of evaluating Large Language Model ( LLM ) outputs is critical for notoriously non-deterministic AI applications, especially as they move into production. Traditional metrics like ROUGE and BLEU fall short when assessing the nuanced, contextual responses that modern LLMs produce.
Key Details About A Modern Framework For Precision Llm As A Judge For Evaluating Ai

The LLM - as -a- Judge framework initially emerged as a promising approach for evaluating various natural language processing (NLP) tasks, providing an automated and scalable alternative to human assessments. Over time, its application has expanded to include the evaluation of structured outputs of various systems.
This article examines the theoretical foundations of LLM - as - judge evaluation, how the open-source library Gaussia operationalises judge models within a broader AI quality framework , and how Judge ...

Useful Notes on A Modern Framework For Precision Llm As A Judge For Evaluating Ai
OpenAI Evals: A framework for evaluating LLMs and LLM systems, and an open-source registry of benchmarks. DeepEval: A simple-to-use LLM evaluation framework for evaluating and testing large-language model systems (e.g., RAG pipelines, chatbots, AI agents, etc.).
Then we introduce a comprehensive taxonomy to explore LLM - as -a- judge from three dimensions: what to judge , how to judge and where to judge . Finally, we compile benchmarks for evaluating LLM - as -a- judge and highlight key challenges and promising directions, aiming to provide valuable insights and inspire future research in this promising research ...

From Generation to Judgment
Finally, we compile benchmarks for evaluating LLM - as -a- judge and highlight key challenges and promising directions, aiming to provide valuable insights and inspire future research in this promising research area 12.
This paper presents a comprehensive survey of the LLMs - as - judges paradigm from five key perspectives: Functionality, Methodology, Applications, Meta-evaluation, and Limitations. We begin by providing a systematic definition of LLMs - as - Judges and introduce their functionality (Why use LLM judges ?).

From Generation to Judgment
Abstract Assessment and evaluation have long been critical challenges in artificial intelligence ( AI ) and natural language processing (NLP). Traditional methods, usually matching-based or small model-based, often fall short in open-ended and dynamic scenarios. Recent advancements in Large Language Models ( LLMs ) inspire the " LLM - as -a- judge " paradigm, where LLMs are leveraged to perform ...



The rapid advancement of large language models ( LLMs ) has opened new possibilities for their adoption as evaluative judges . This paper introduces Themis, a fine-tuned LLM judge that delivers sophisticated context-aware evaluations. We provide a comprehensive overview of the development pipeline for Themis, highlighting its scenario-dependent evaluation prompts and two novel methods for ...