Getting to Know Spark and Its Role in Modern Enterprise Architecture
Spark has fundamentally reshaped how organizations approach large-scale data processing. More than just a distributed computing framework, it has become the backbone of modern data engineering pipelines, powering everything from real-time analytics to machine learning workloads. However, where Spark's distributed nature lies performance benefits, it introduces a level of architectural complexity that can make data recovery uniquely challenging. This is where the spark data recovery tool comes in—designed to handle the specific caveats of recovering data in Spark environments, ensuring that business continuity remains uncompromised even when hardware failures, node crashes, or software bugs threaten to shake the ledger of the distributed data state.
Why Standard Recovery Tools Fall Short in Spark Environments
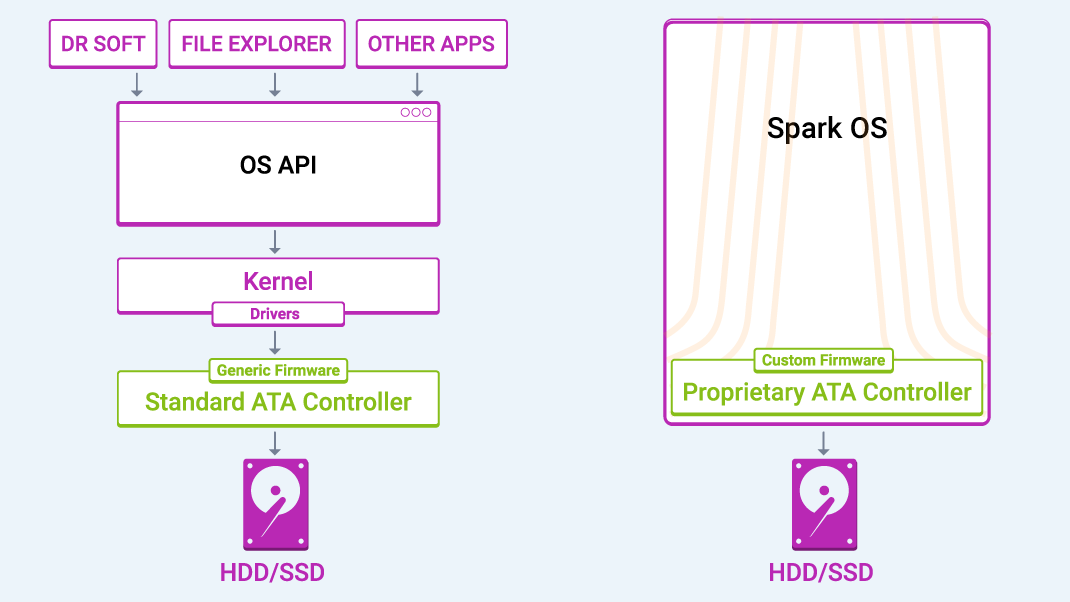
Traditional database recovery solutions were built with single-instance RDBMSs or conventional storage apps in mind, meaning they do not understand the dataset partitioning strategies, cluster state patterns, or distributed transaction model that Spark operates on. When an unplanned failure occurs in a running Spark cluster, standard tools lack the context needed to reassemble data across worker nodes, handle mid-execution write processes where blocks of data are spread across multiple locations, and finalize the missing ends.
The Spark Data Recovery Tool bridges this gap by speaking the same language as dedicated recovery frameworks. It manages recovery of specific Spark structures like Resilient Distributed Datasets (RDDs), DataFrames, and Spark SQL metadata. As a result, organizations are not only able to recover their datasets but maintain the transformations and schema tracking that make datasets valuable in the first place.

Core Recovery Capabilities to Look For
Depending on specific use cases, reliable Spark data recovery solutions address a range of critical tasks:
- Checkpoint and WAL Recovery: Reading and replaying surviving Write-Ahead Logs and checkpoint windows to restore consistency in failed streaming jobs.
- Partial Execution Reconstruction: Reprocessing only the failed stages of a pipeline rather than rerunning from scratch, saving compute costs and wall-clock time.
- Metadata and Catalog Restoration: Restoring Hive Metastore references, DataFrame schemas, and table partitions catalog so that queries remain functional post-recovery.
- Worker Node State Clearing: Tracking the memory and disk state of each executor to facilitate even recovery without data corruption or duplication.
How the Recovery Workflow Actually Operates
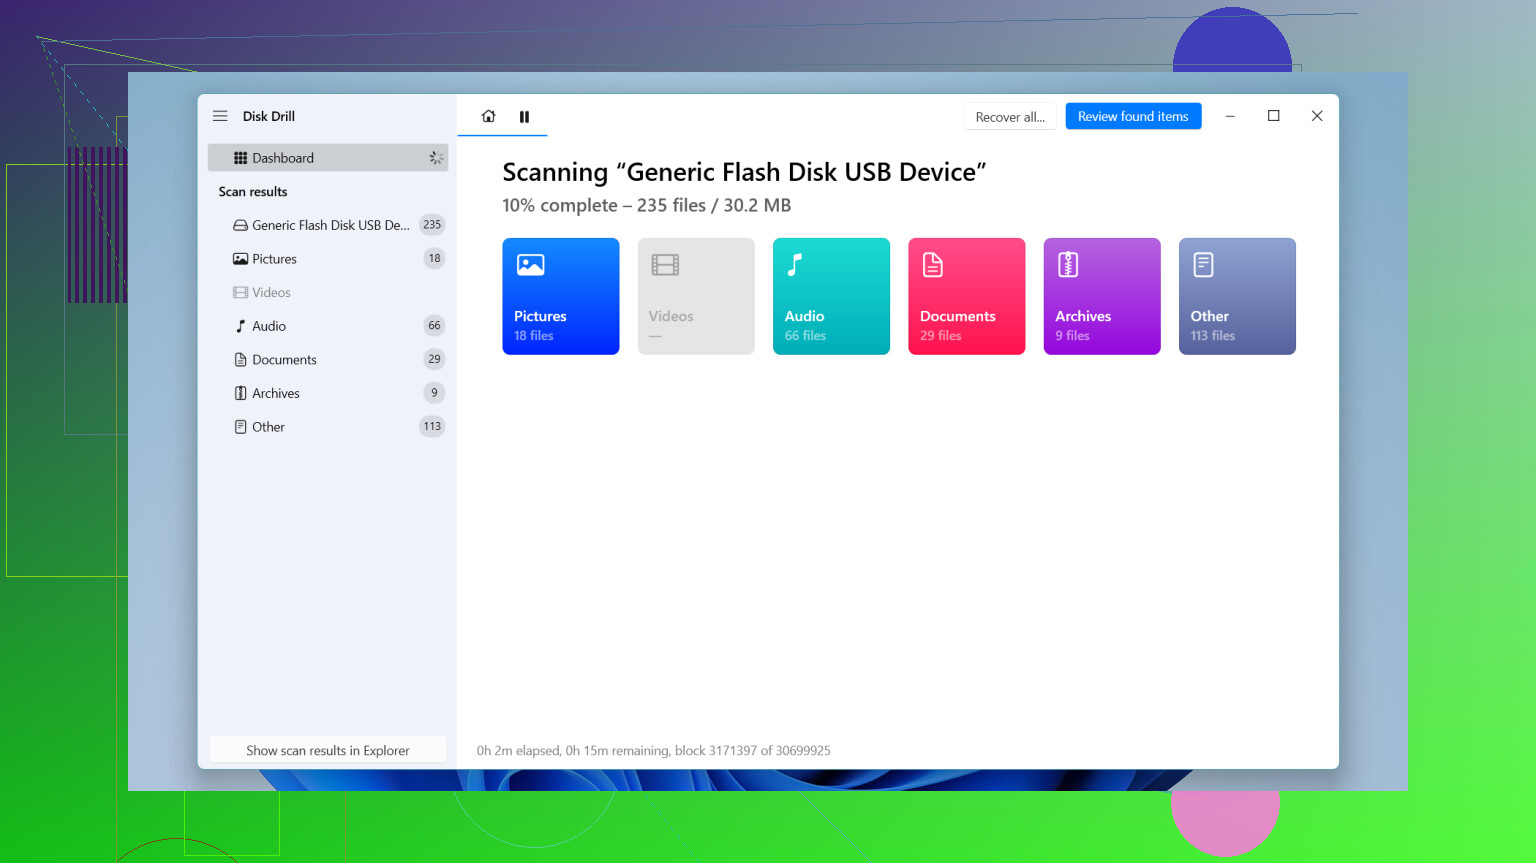
The flow begins with early detection—the tool monitors cluster health and listens for node disconnections or OOM exceptions before they cancel running jobs. Upon detecting an actionable failure, the recovery engine initiates a safety staging protocol. Data already written to HDFS, S3, or ADLS is identified, checksummed, and snapshotted.
Real-World Scenarios Where Spark Recovery Proves Its Value
Consider a retail company processing terabytes of transactional data nightly using Spark queries. Without a dedicated recovery tool, a single mid-job failure could mean restarting a six-hour batch from square one, delaying financial reports to the following business day. With a proper Spark Data Recovery Tool, the pipeline automatically resumes from the micro-batch boundaries that were safely saved, reducing recovery to minutes instead of hours.

Maximizing Your Investment with Proper Configuration
Recovery capability depends on proactive configuration. Best practices include setting appropriate checkpoint intervals, ensuring WAL monitoring and streaming aggregations for robust streaming jobs, and keeping the Hive Metastore or Unity Catalog backups synchronized with Spark materialization timestamps. Testing recovery scenarios regularly ensures that when real failures strike, recovery playbooks proceed smoothly without last-minute scramble.
Conclusion Focused on Recommending the Spark Data Recovery Tool
For organizations serious about data reliability in Spark deployments, the Spark Data Recovery Tool is not an afterthought—it is a core element of a resilient data platform. It reduces downtime, protects SLAs, prevents unnecessary recomputation costs, and preserves workload continuity as intended. For enterprises adopting a data-driven mindset and facing mounting complexity, the Spark Data Recovery Tool provides the safety net that unlocks full strategic potential.