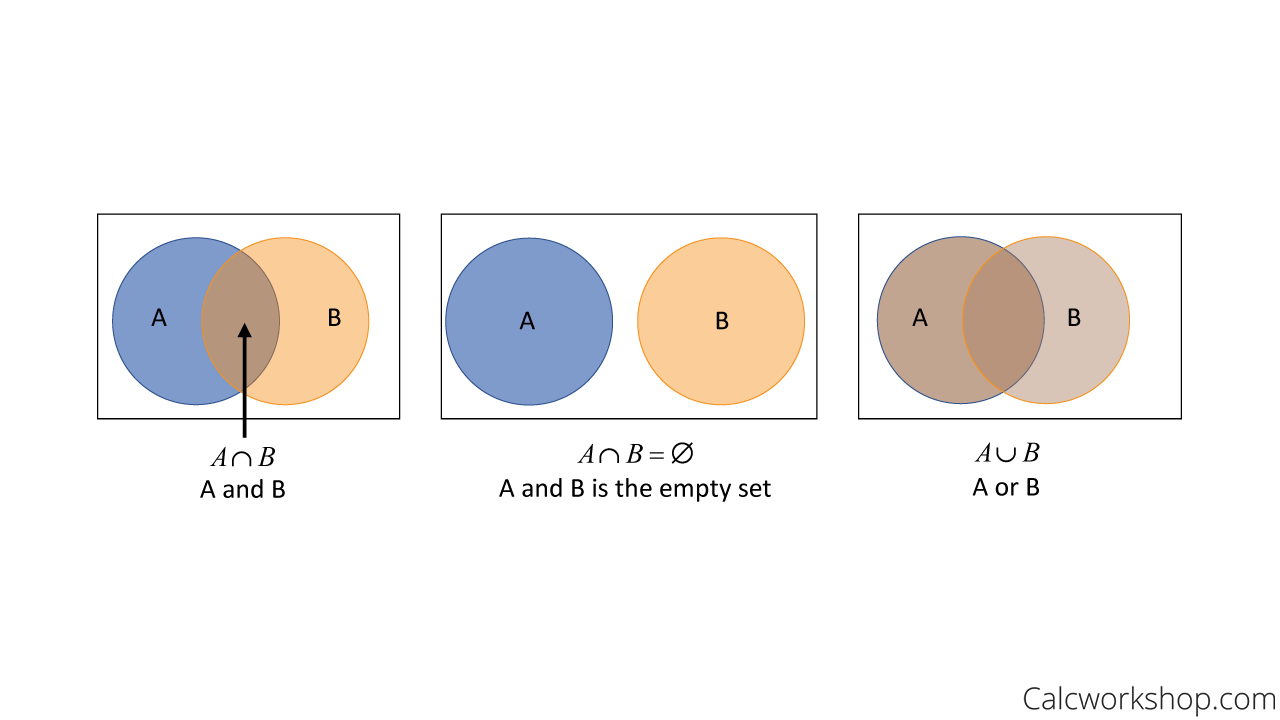At its core, the graph data structure is about modeling relationships. Whether you are mapping flight routes, computer networks, or friend circles, complex queries often require you to combine or compare these sets of relationships. This is where the concepts of graph union and intersection become essential. These set-theoretic operations allow you to merge different graph datasets or identify the common causal links within a larger system, providing a powerful toolkit for network analysis.
Understanding Graph Set Operations
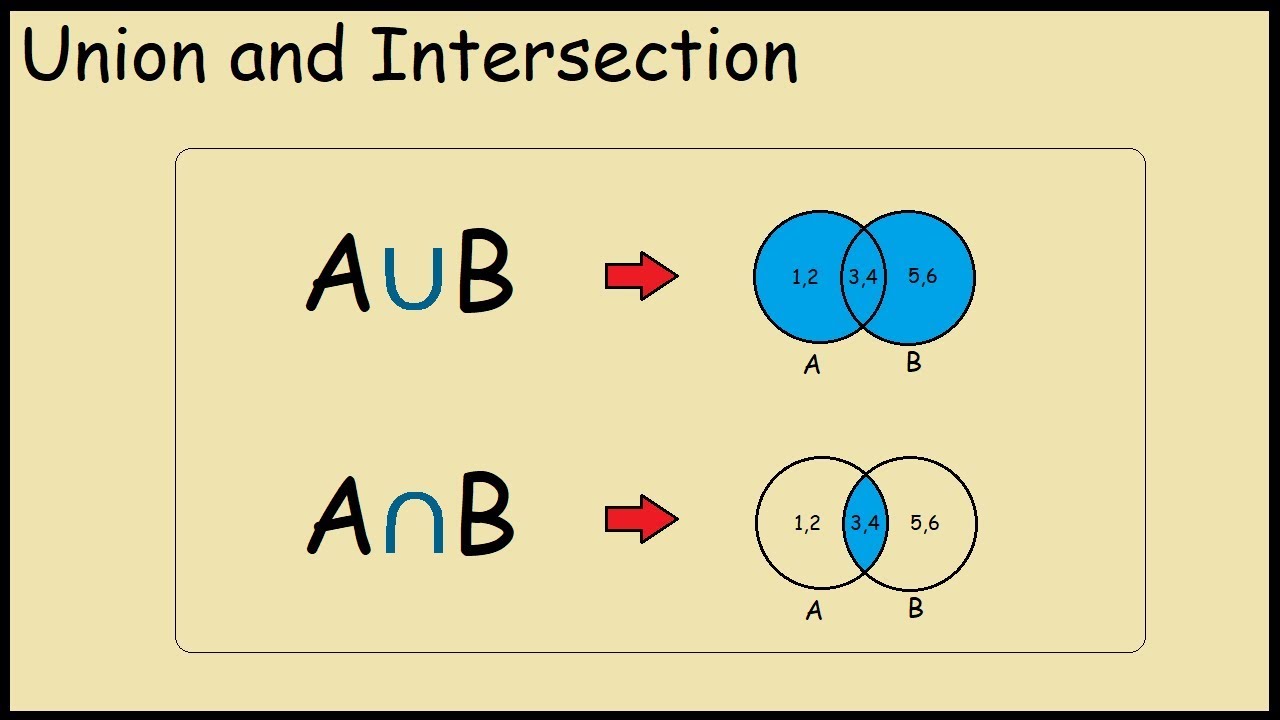
To grasp how these operations work, it helps to remember that a graph is fundamentally a set of vertices and edges. When we treat graphs as sets, we can apply standard mathematical set operations to them. These operations are structurally similar to their SQL counterparts but are applied directly to the topology of the network.
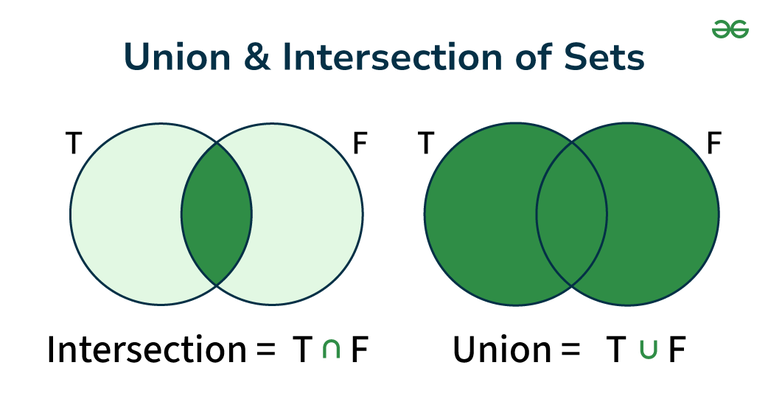
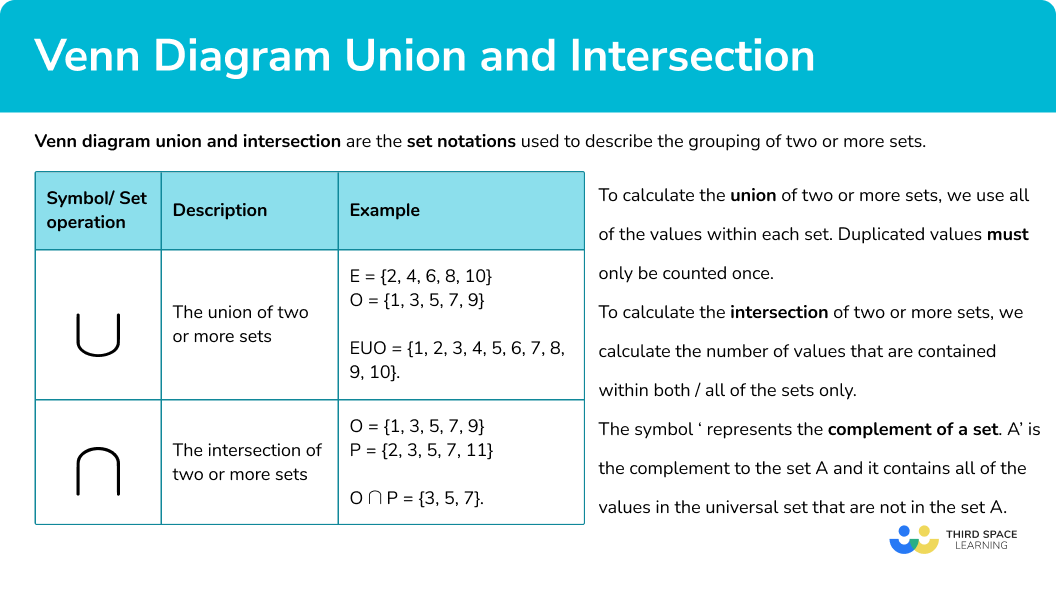
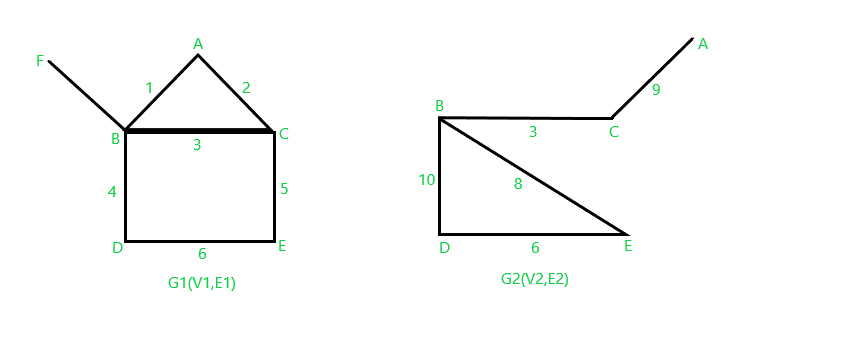
The logic behind these operations relies on how nodes and edges are matched. In a simple graph, if a node or an edge exists in either of the contributing graphs, it will factor into the union. For the intersection, a node or edge must exist in both input graphs to be included in the final output.

Graph Union
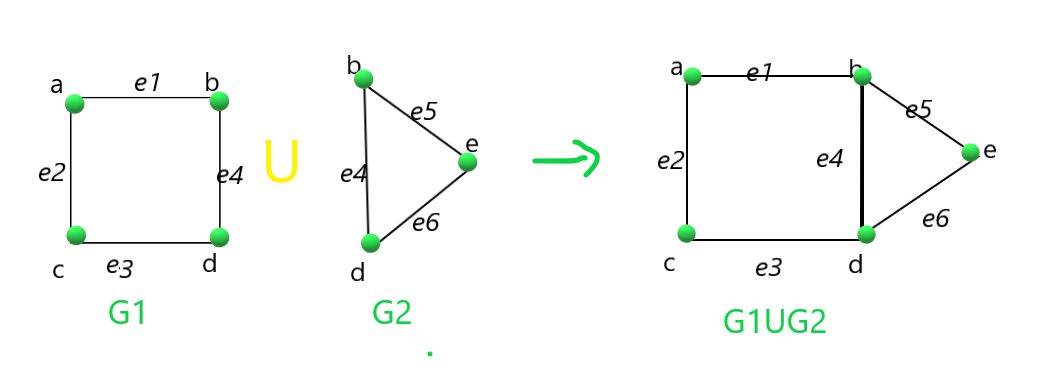
The graph union represents the most inclusive combination of two or more graph structures. When executing a union operation, the resulting graph contains every unique node and edge found across all merged inputs. If edge weights are present, simply combining them can cause duplicates. To solve this, database operations usually aggregate the weights—often by summing them up—or select the most recent timestamp.
Unions are incredibly useful in data engineering.
- Merging Disparate Datasets: Combining several knowledge graphs into a single master network.
- Time-Series Expansion: Adding a week's worth of daily network logs into a single historical graph for long-term trend analysis.
Graph Intersection
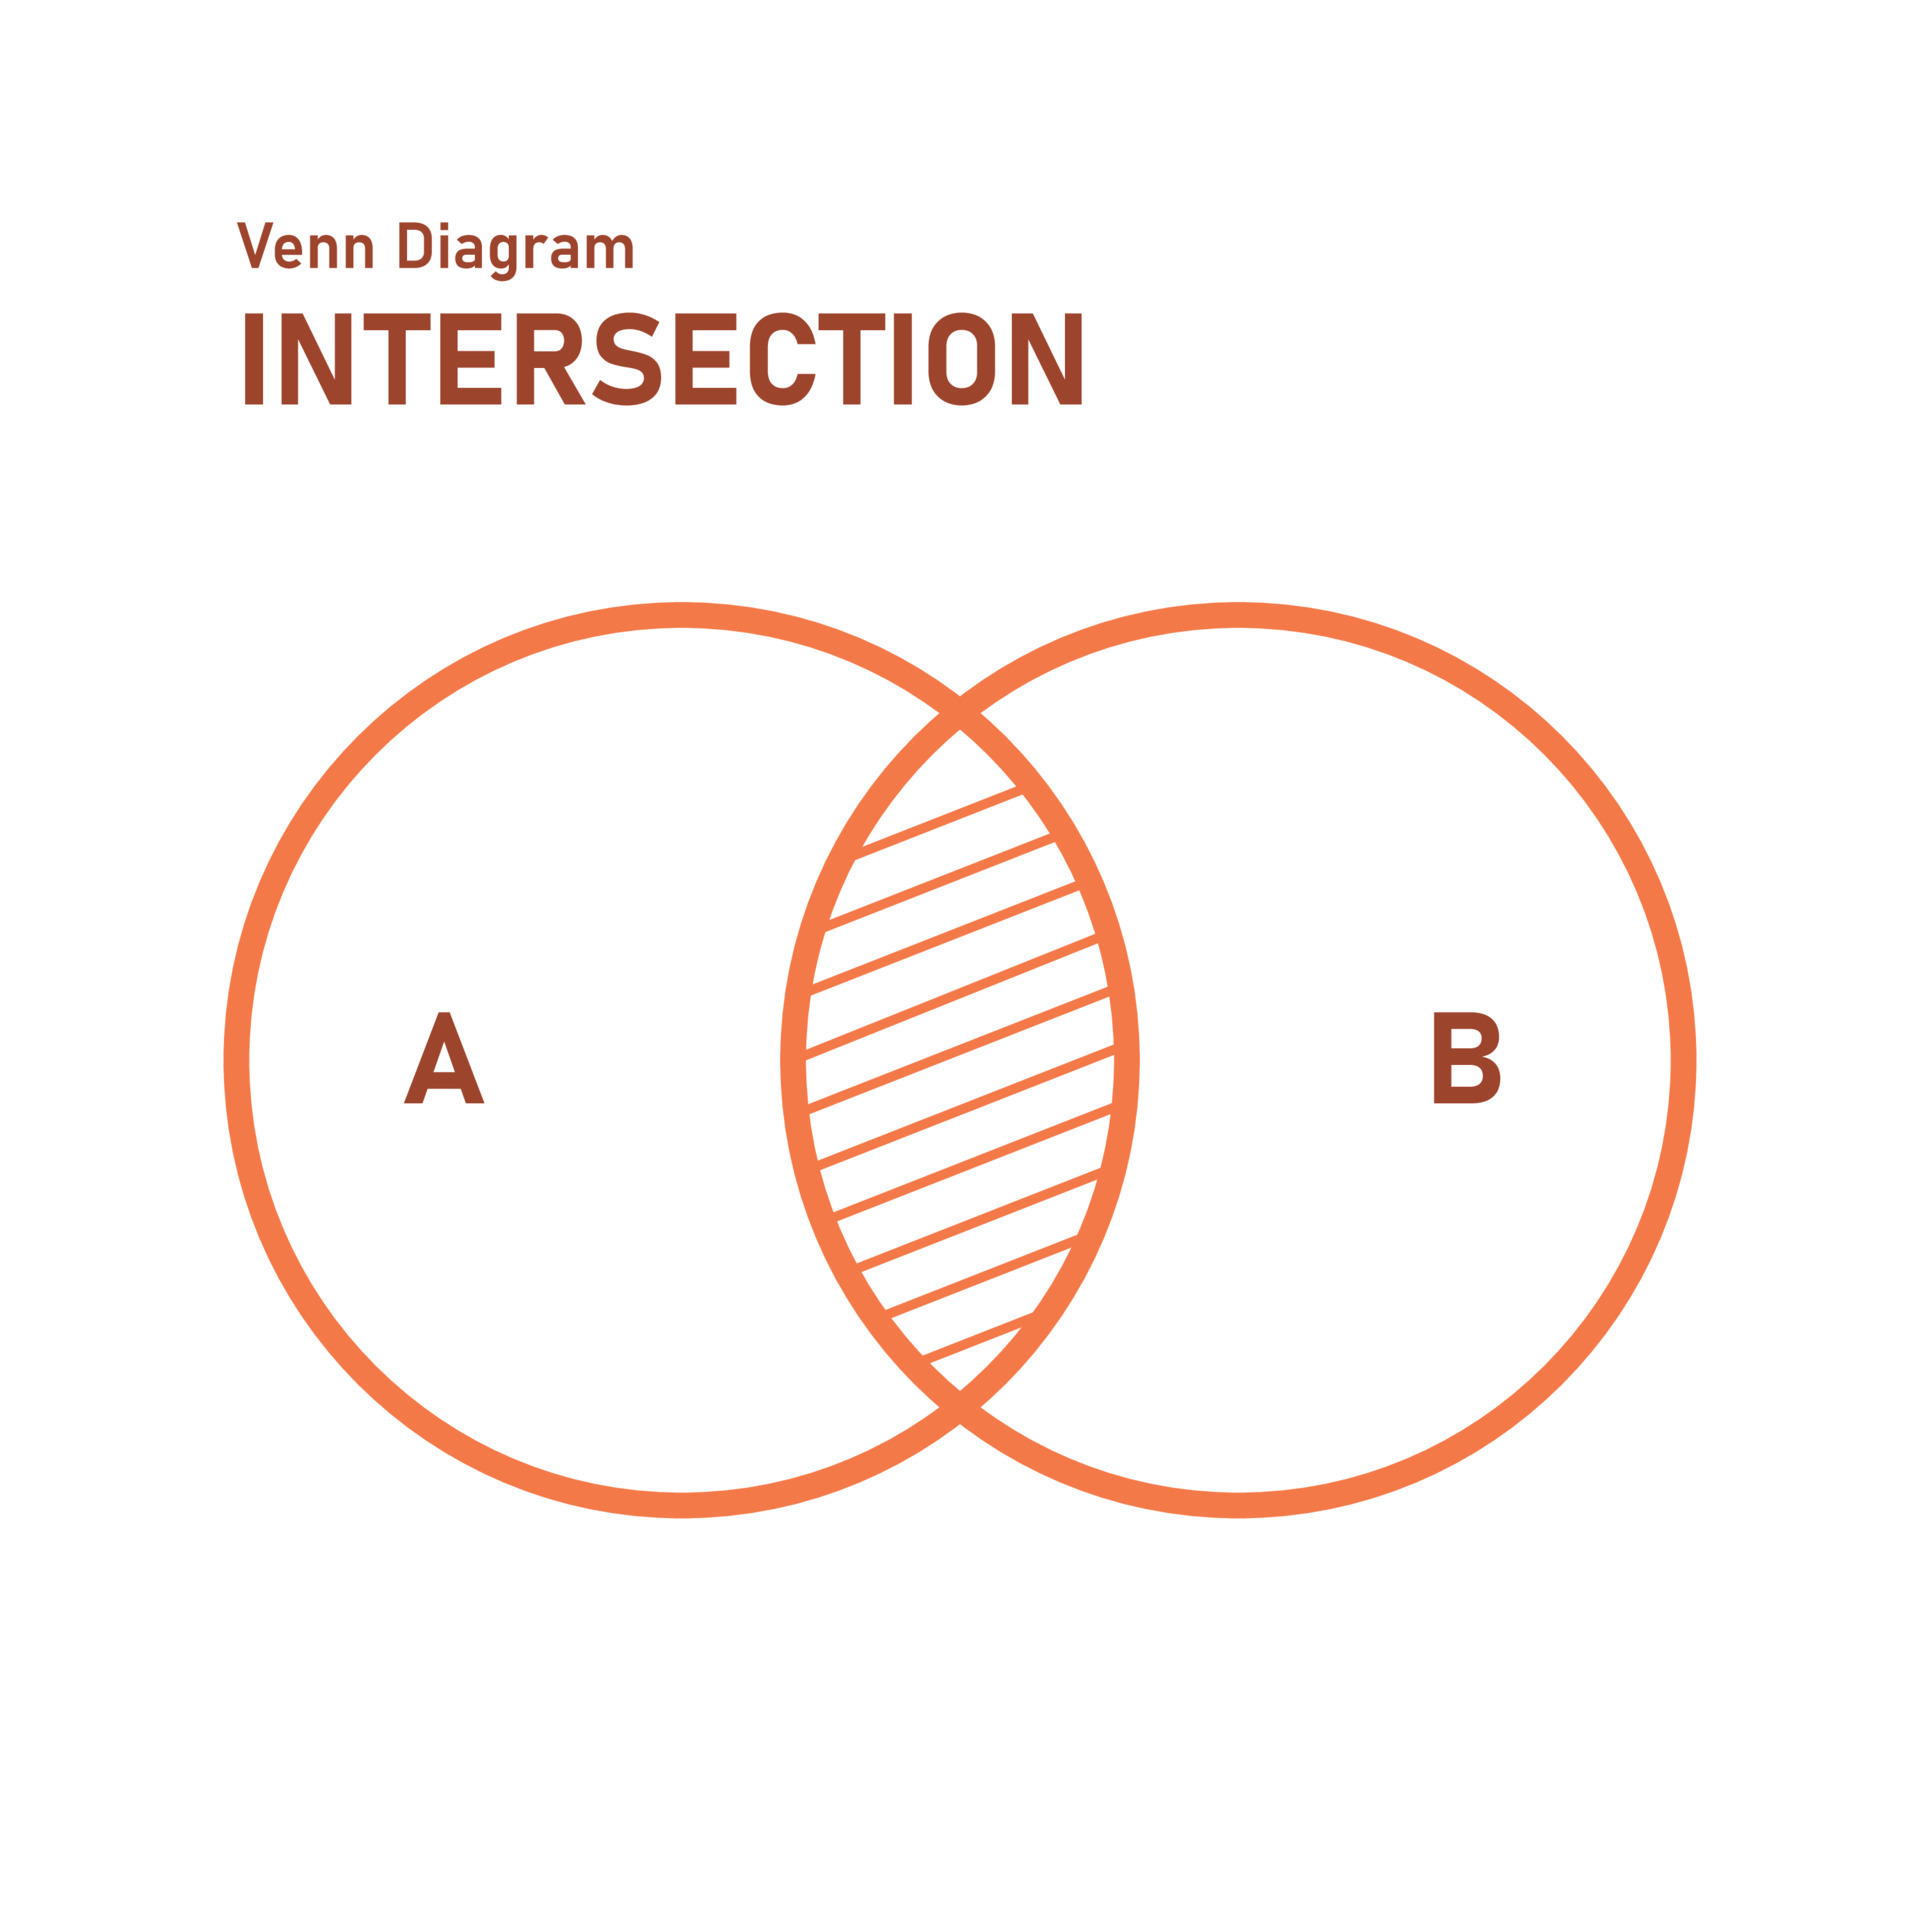
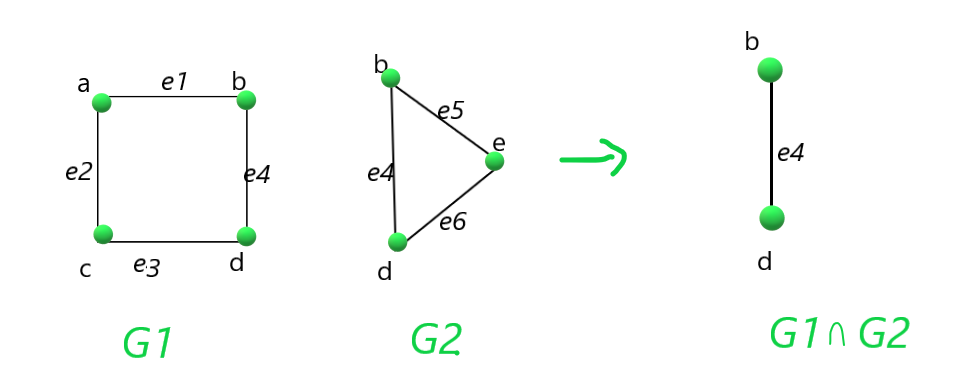
Graph intersection is significantly more restrictive. It outputs only the nodes and edges that are shared by the input graphs. If a node exists in Graph A but not Graph B, it is entirely removed from the result.
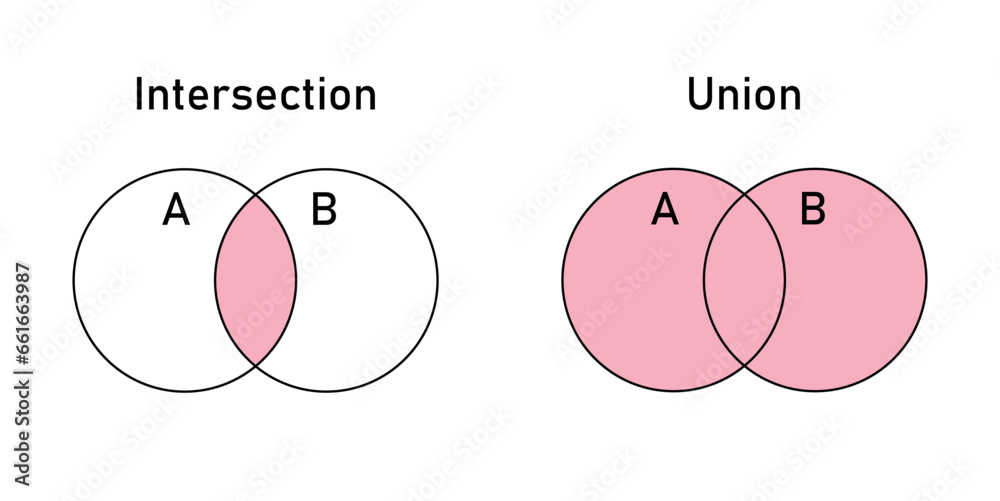
This is the primary operation used to find common ground within topologies.
- Causality is Key: In diagnostic AIOps or social network analysis, finding overlapping paths helps isolate the root cause of an issue that might span multiple microservices or communities.
- Kernel Efficiency: Intersecting a graph with a known pattern or subgraph can drastically narrow down the search space for complex pattern matching algorithms.
Practical Implementation and Optimization
Implementing these operations efficiently requires attention to how the data is stored and indexed. Graph databases like ZOO optimize these operations natively. Instead of pulling two massive sets of data into memory and comparing them line by line, the query engine navigates the index directly.
For example, in a highly connected graph, an intersection query might involve scanning the adjacent edges of a specific node set to verify the existence of matching relationships in a second graph. Proper indexing of node attributes ensures that the matching step happens in constant time or logarithmic time relative to the dataset size, rather than linearly scanning the entire database.
Comparing Outcomes: Union vs Intersection
| Feature | Graph Union | Graph Intersection |
|---|---|---|
| Definition | Combines all unique nodes and edges. | Retains only shared nodes and edges. |
| Result Size | Equal to or larger than the largest input. | Equal to or smaller than the smallest input. |
| Primary Use Case | Data integration and expansion. | Pattern isolation and shared link analysis. |
Conclusion
Mastering graph union and intersection elevates data analysis from simple traversals to complex, multi-layered reasoning. By leveraging ZOO's native graph computation capabilities, you can execute these set operations on massive datasets efficiently. As networks grow in complexity, the ability to merge and isolate specific relationships quickly becomes non-negotiable for deriving actionable insights.