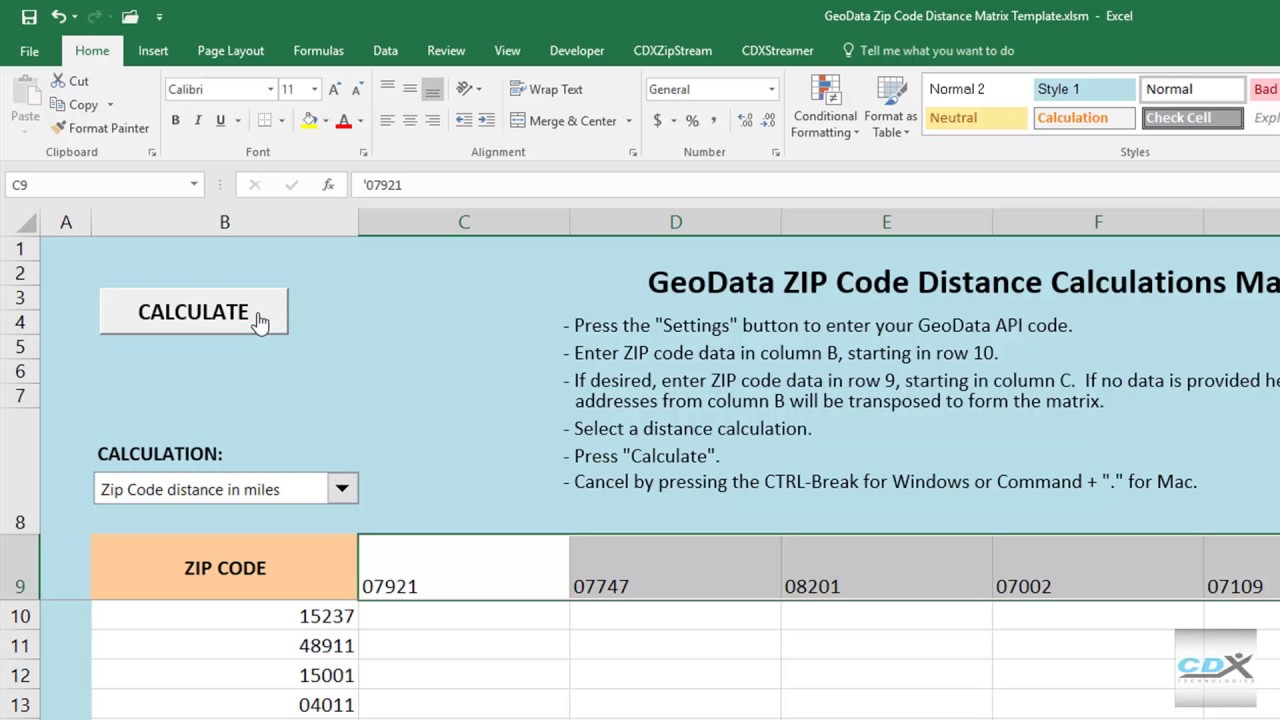
A zip‑to‑zip distance table is a precalculated set of driving or straight‑line distances between pairs of ZIP codes. For many businesses, it solves a simple but costly problem: looking up the same distances over and over again by calling a geocoding or routing API. With a well‑crafted distance table, you can replace live lookups with fast joins in a database or spreadsheet, saving time, cost, and complexity.
What a zip‑to‑zip distance table is (and isn’t)
At its core, the table is just rows of data: origin ZIP, destination ZIP, and one or more distance or travel metrics (miles, kilometers, travel time, or even cost). It typically includes both straight‑line distance (“as the crow flies”) and, when available, planned road distance or time based on routing engines.
Common misconceptions lead people to expect shipping costs or delivery guarantees directly from such a table. In practice, these distances are inputs to your pricing, routing, or eligibility logic. The table itself doesn’t define service levels or fees; it provides the raw shortest‑path estimate that you then enrich with business rules.

Straight‑line vs road distance
- Straight‑line distance (geodesic): Fast to compute, good for rough filtering or binning (e.g., “all customers within 50 miles”). It ignores roads, terrain, and borders.
- Road distance / time: Required for route planning, accurate ETAs, and fuel or toll cost considerations, but more expensive to build and keep current.
Main use cases across industries
Several sectors rely heavily on origin–destination distance tables to operate efficiently. While the underlying idea is similar, the exact metrics and thresholds can vary significantly by use case.
Logistics and carriers use zip‑to‑zip tables for zone‑based pricing and hub selection. Fleet managers use them to estimate fuel consumption and driver hours without overloading dispatch systems with live ETA requests. Retail and ecommerce brands build “delivery promise” experiences based on rough distance bands (“ships within 2 days if within 200 miles”).
Brick‑and‑mortar chains and service providers use these tables for territory planning and store‑assignment logic. Healthcare and insurance companies often define “in‑network” or “accessible care” thresholds, where a patient must be within a certain distance from a facility to be eligible for coverage or services. Real estate and marketing teams might segment outreach campaigns by proximity to flagship locations or distribution centers.

Typical schema and example structure
Most implementations store distance data in a flat table. A simple, performant design uses:
| origin_zip | dest_zip | distance_mi | drive_time_min |
|---|---|---|---|
| 10001 | 90001 | 2,795 | 2,640 |
| 30301 | 73301 | 940 | 560 |
| 60601 | 80201 | 996 | 870 |
There is some debate about whether to store mirrored pairs (A→B and B→A) or only one direction. Storing doubles the rows but keeps queries simpler and avoids extra logic to normalize directionality on every join. For country‑wide U.S. ZIP codes, that starts to matter: with over 40,000 ZCTA values, a full pairwise table can easily exceed 1.6 billion rows. Most teams avoid this by filtering.
Filtering and reducing table size
- Keep only pairs within a reasonable radius (e.g., 300–500 miles for ground transportation).
- Limit to ZIPs you actually serve or have demand in, instead of all ZCTAs.
- Use symmetric rows and enforce ordering in the ETL (always store the pair where origin_zip < dest_zip).
How to build a zip‑to‑zip distance table
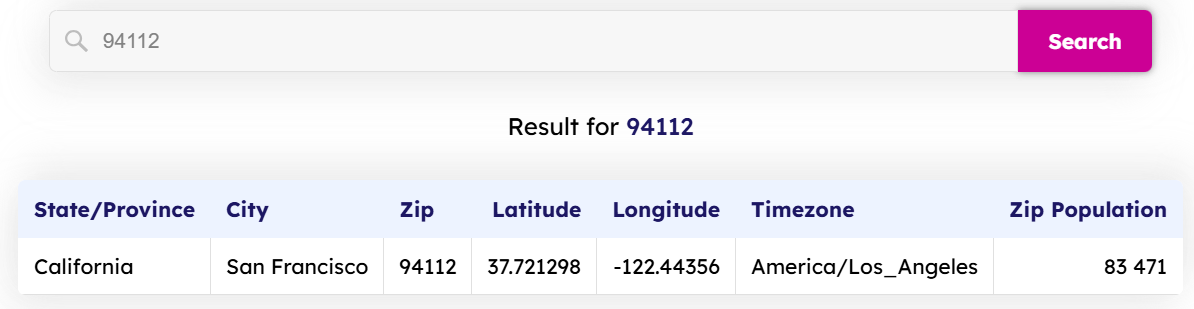
You typically assemble and maintain such a table using geospatial tools and geographic data, not manual entry. It’s common to start with the latitude and longitude of each ZIP code centroid, then compute straight‑line distances with the Haversine formula or similar geodesic methods.
For road distances, routing engines or commercial datasets are used. You feed origin–destination pairs and extract the best route. Many teams batch this work by distance buckets: you might only route pairs under 400 miles, assuming anything farther will be handled by different modes (air, intermodal, etc.) or ignored.
Because road networks and ZIP boundaries change, you need a refresh strategy. Aging data leads to biased cost estimates and misleading ETAs. Most operations teams pair a quarterly update for road distances with a more frequent update for any business rule changes (pricing, hubs, cut‑off times).
Implementation tips and best practices
When interpreting and using a distance table, pay attention to several technical and business nuances that can quietly derail its value if overlooked:
- Clarify whether “distance” means straight‑line or road, and make that visible in column naming.
- Document the vintage of the data and the source (Census ZCTA, commercial ZIP boundary, carrier data, etc.).
- Use ZIPs consistently as strings (zero‑padded), not integers, to preserve leading zeros.
- Index the table carefully on (origin_zip, dest_zip) or use materialized views for your most common filters.
Before relying on the table in production, validate it against a sample of known routes. Spot‑check distances using reference addresses or trusted APIs, and examine outliers where road distances are implausibly short or long. You might also align the table’s distances with actual shipment or telematics data over time to see whether your “average speed” assumptions are valid.
If you use these distances for pricing or customer‑facing offers, add a margin of error. A distance of 48 miles doesn’t always mean “under 60 minutes.” Incorporate speed‑time bands, congestion factors, or carrier scorecards rather than treating road minutes as exact durations.
Operational impact and limitations
Once you have a reliable zip‑to‑zip distance table, you can optimize many workflows that previously depended on live calls, manual lookup, or ad hoc spreadsheets. Service eligibility checks, territory assignments, and inbound/outbound routing decisions become simple, offline data joins.
Still, distance tables are never a complete substitute for live routing. Hourly traffic, weather, roadworks, construction, and temporary closures change actual conditions dramatically. For critical last‑mile time estimates or real‑time dispatch, pair the table with live data and treat historical distances as baselines.
With a clear definition of what your table represents and a plan to keep it updated, a zip‑to‑zip distance table becomes a practical backbone for logistics, pricing, and customer experience decisions. It turns exponential API costs and latency into predictable, join‑friendly analytics that scale with your business.