PDF Model Predictive Control and Reinforcement Learning
Offpolicy modelbased endtoend safe reinforcement learning
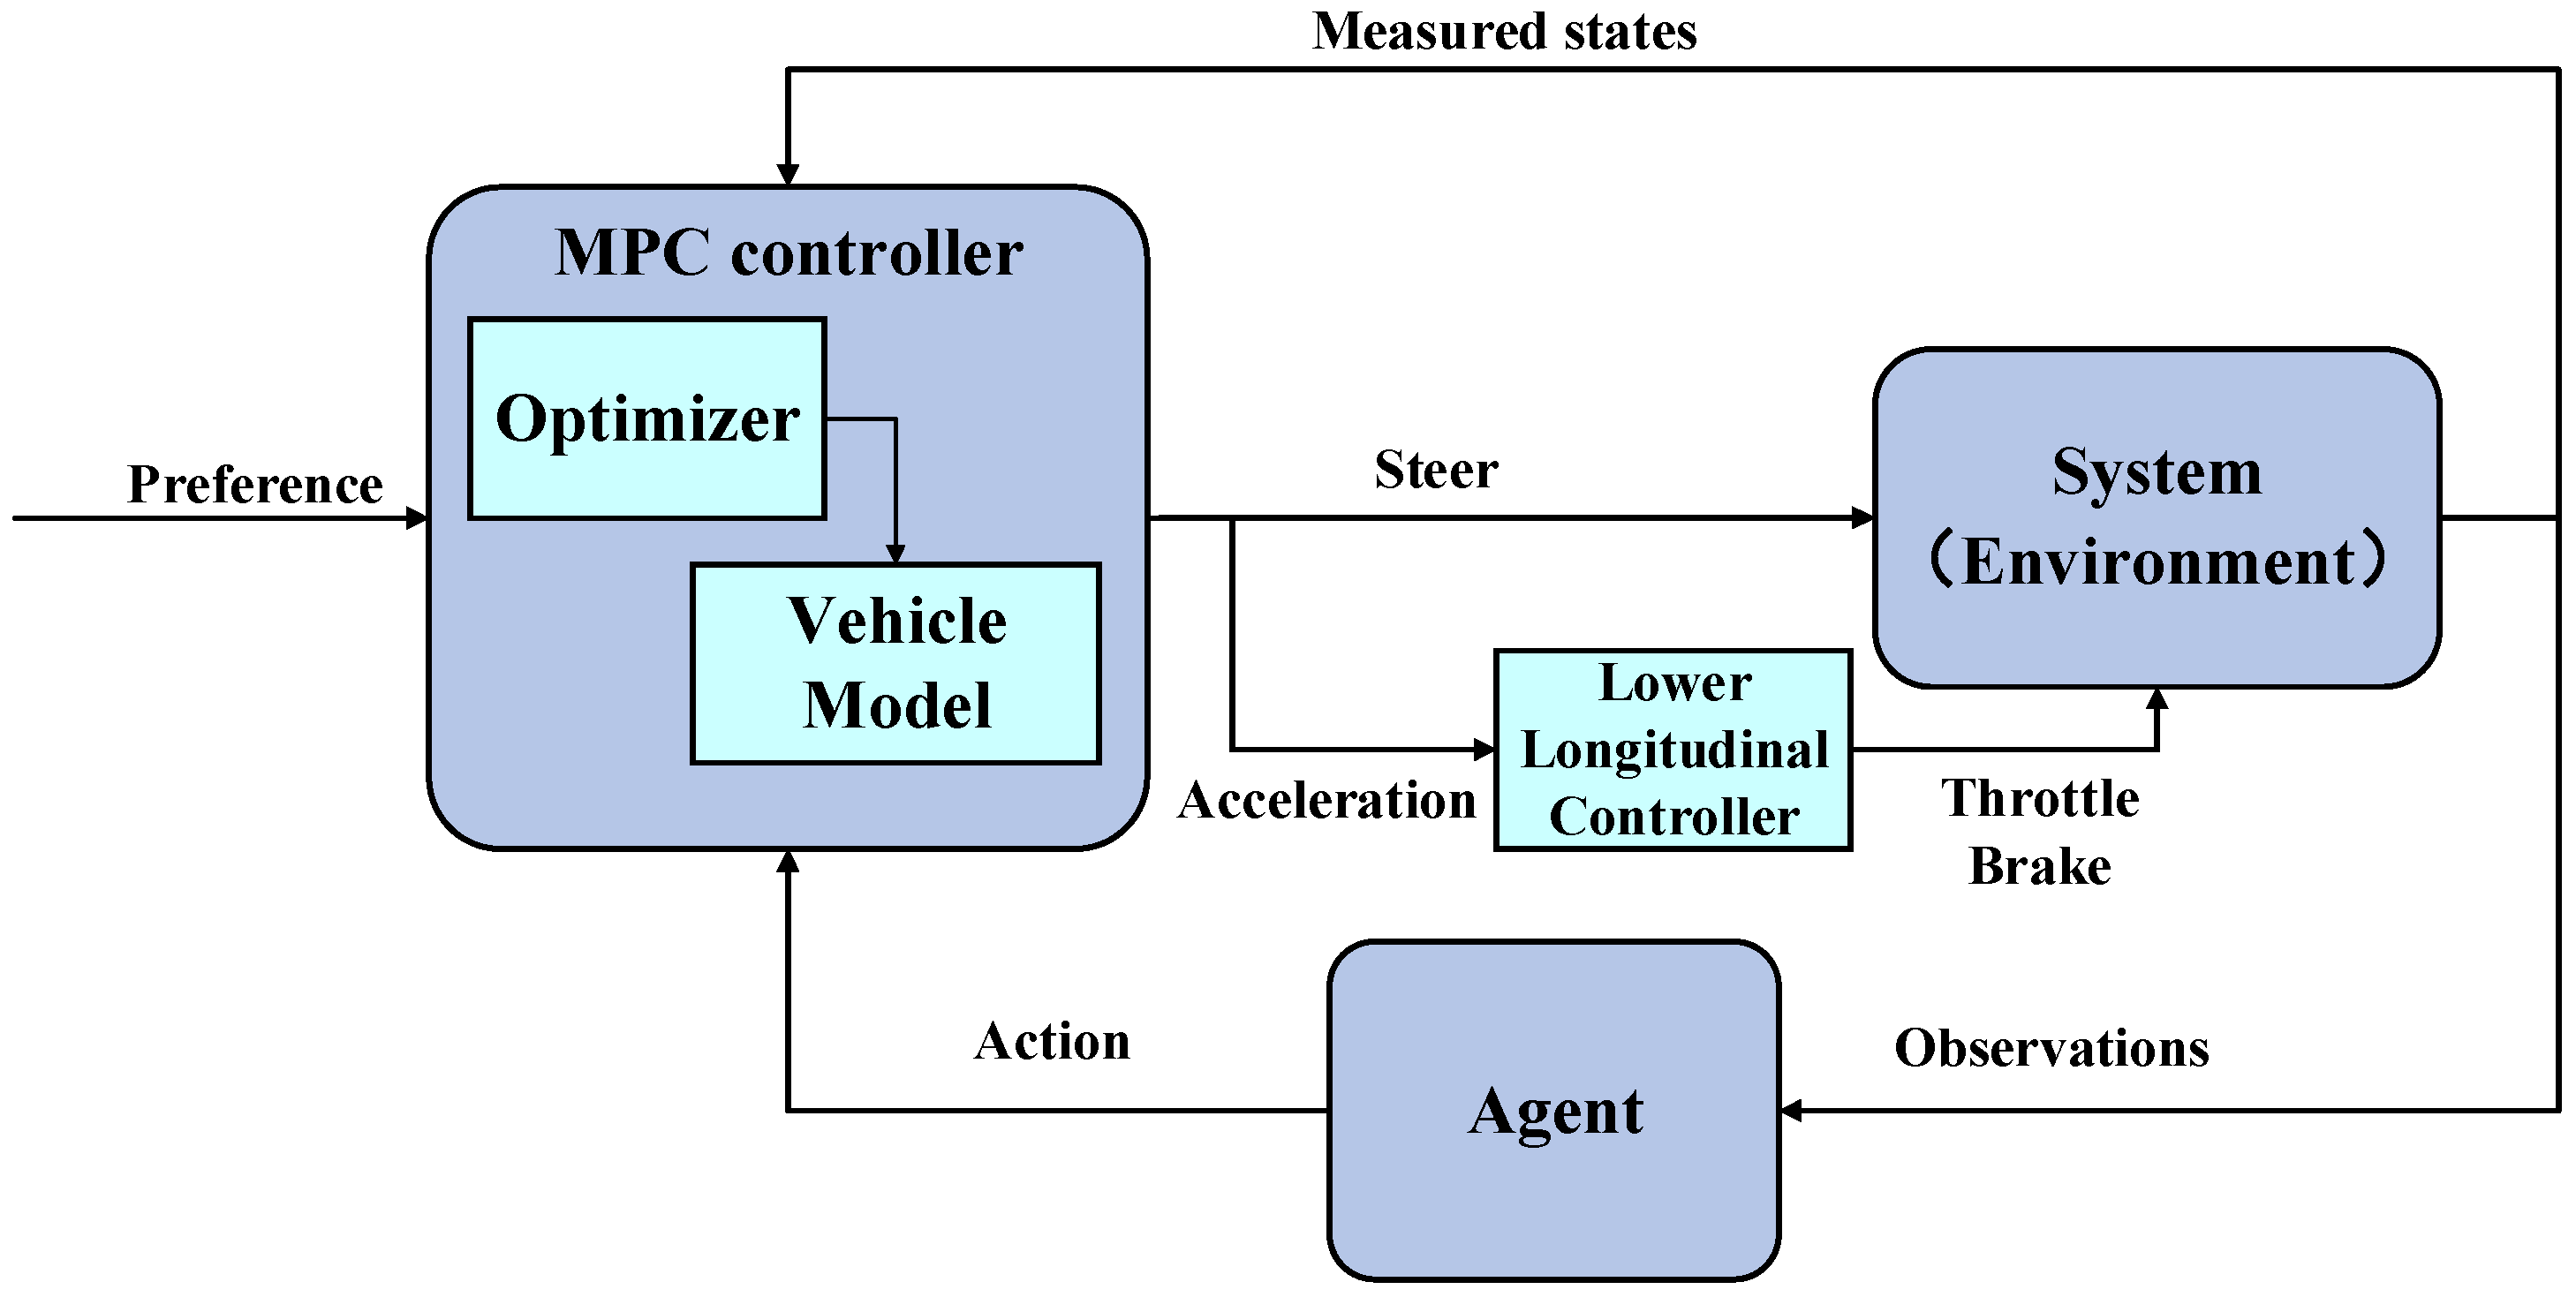
Safe reinforcement learning ( RL ) based approaches traditionally seek learning of the control laws that are optimal with respect to system performance whilst ensuring system stability and safety. In this article, an off-policy safe RL based approach is proposed for nonlinear systems affine in control in continuous time.

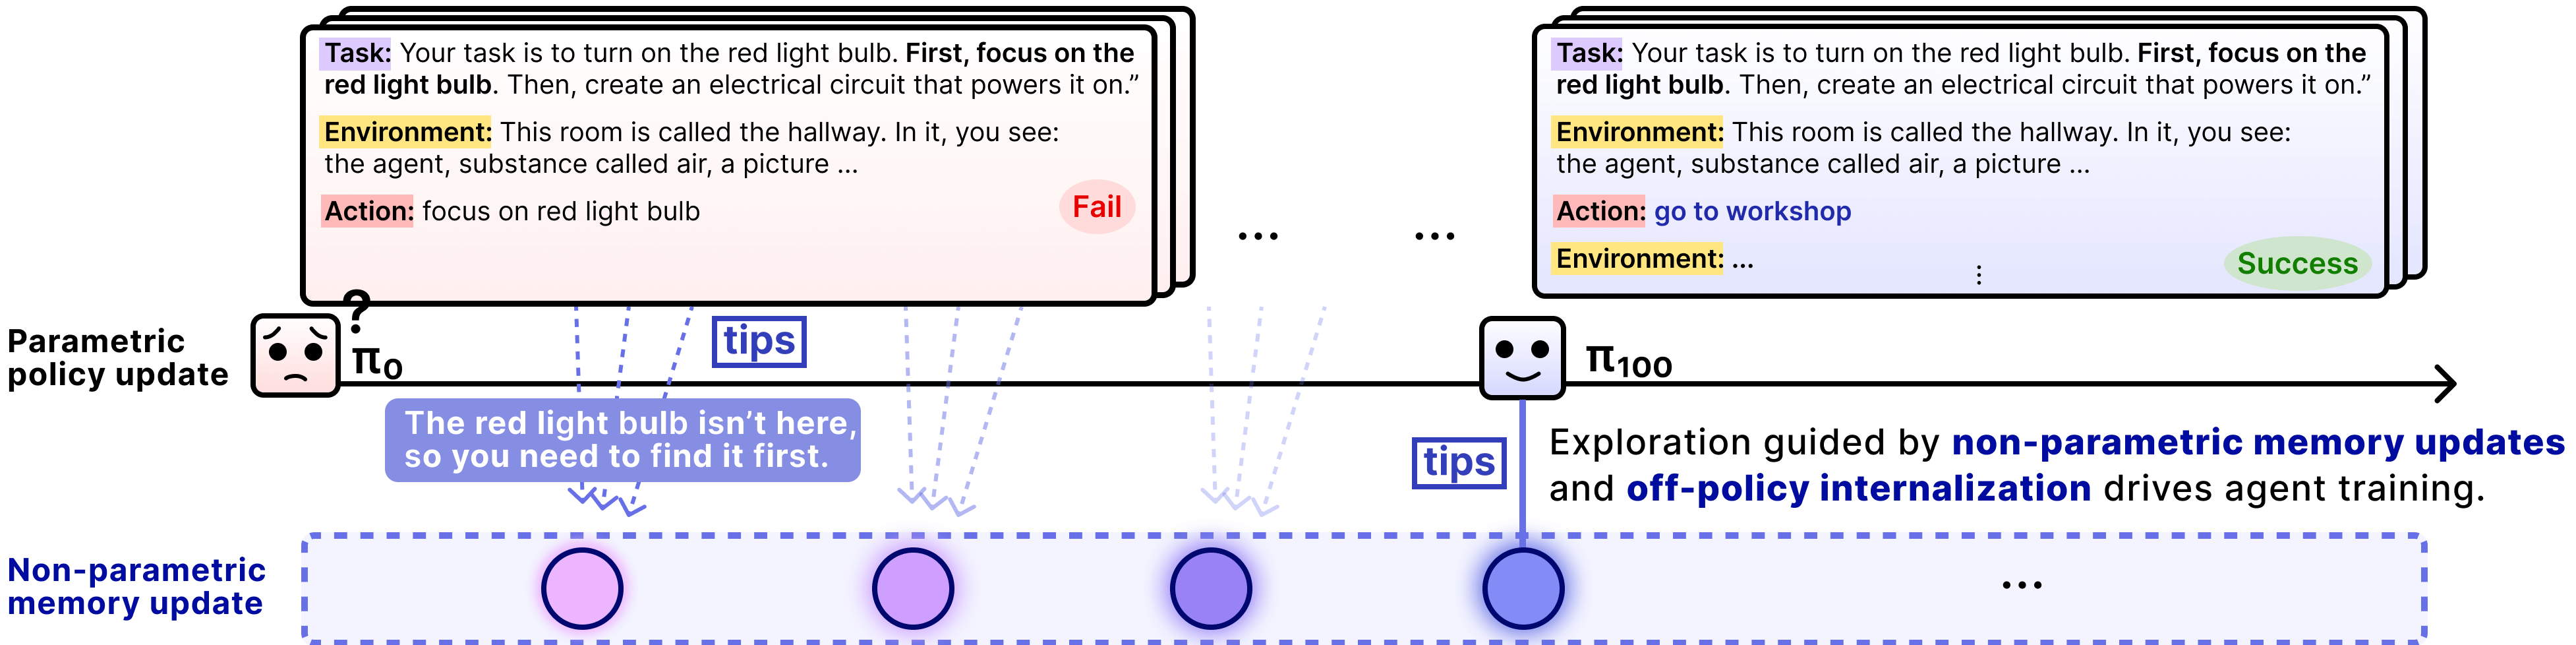
Training large language models with reinforcement learning runs into a fundamental issue: off -policiness. As the policy updates, the rollouts still arriving from earlier checkpoints become stale—their distribution drifts away from the current model . In latency-heavy, agentic/tool-calling settings (web calls, DB queries, GUI actions), rollouts can take minutes, so
Residual Off
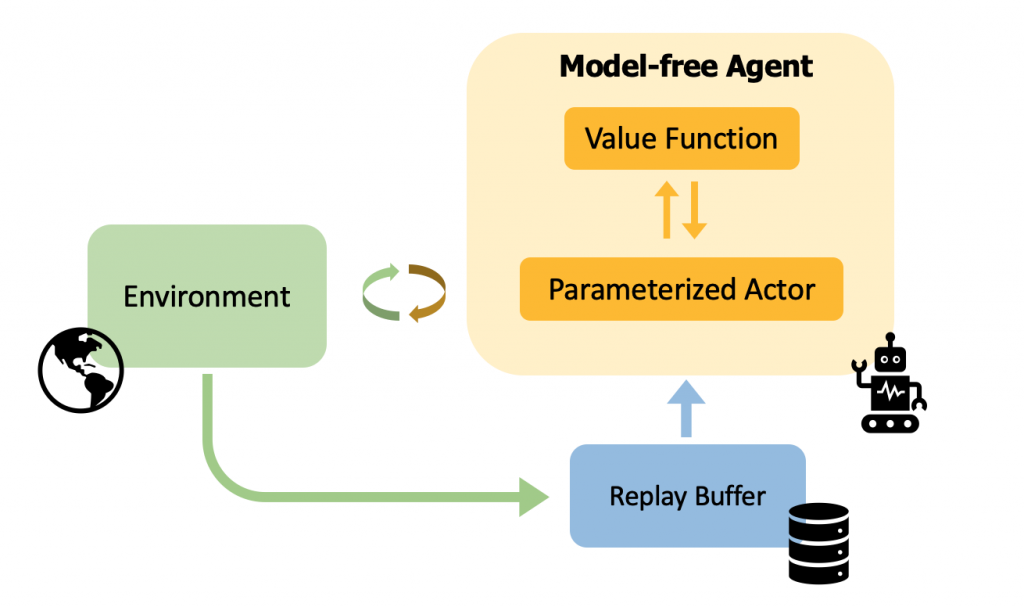
This particular example perfectly highlights why Model Predictive Off Policy Rl is so captivating.
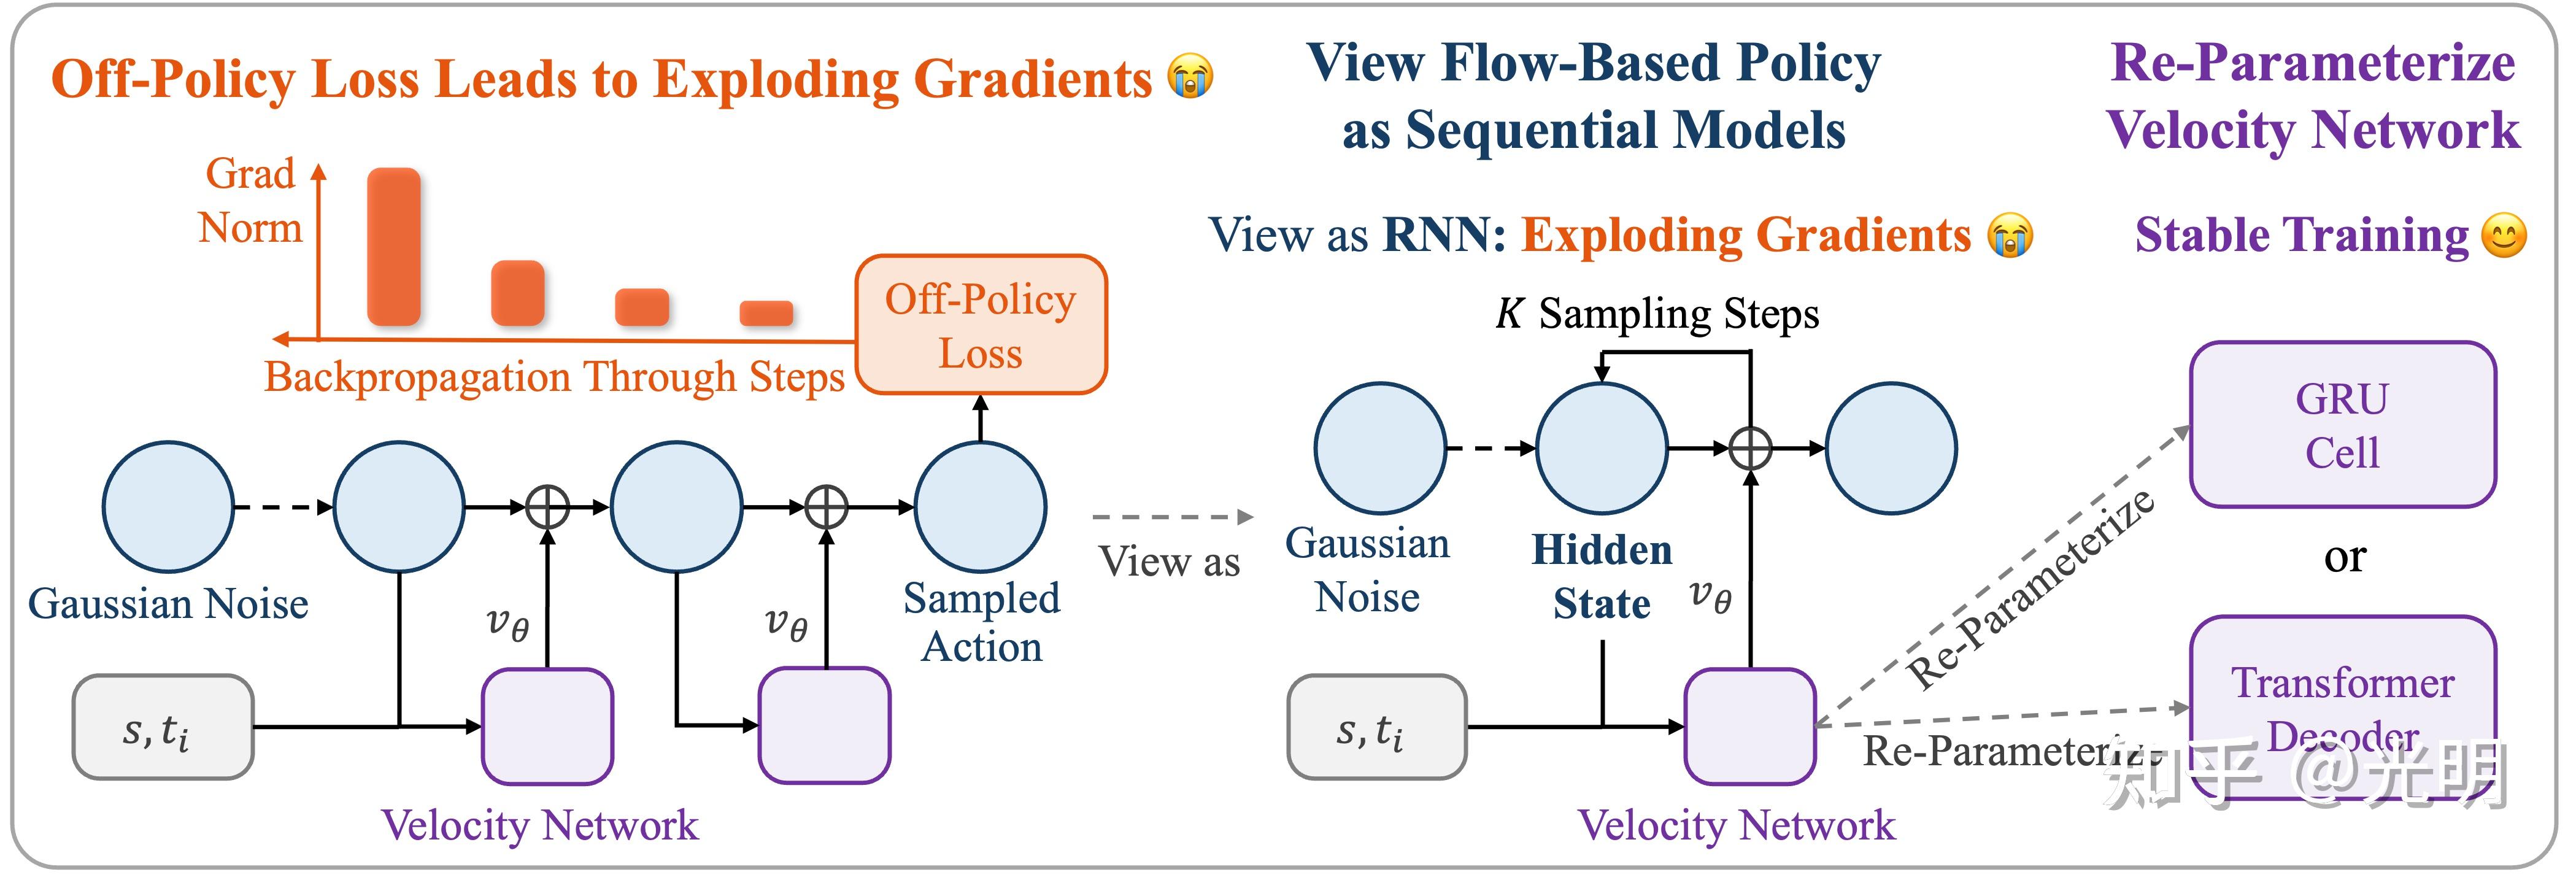
Modern BC architectures are typically deep models with tens of millions of parameters that use action chunking or diffusion-based approaches, which can make it challenging to apply RL methods to directly optimize the policy . Our ResFiT approach leverages BC policies as black-box bases and learns lightweight per-step residual corrections via efficient off-policy RL , requiring only sparse binary ...
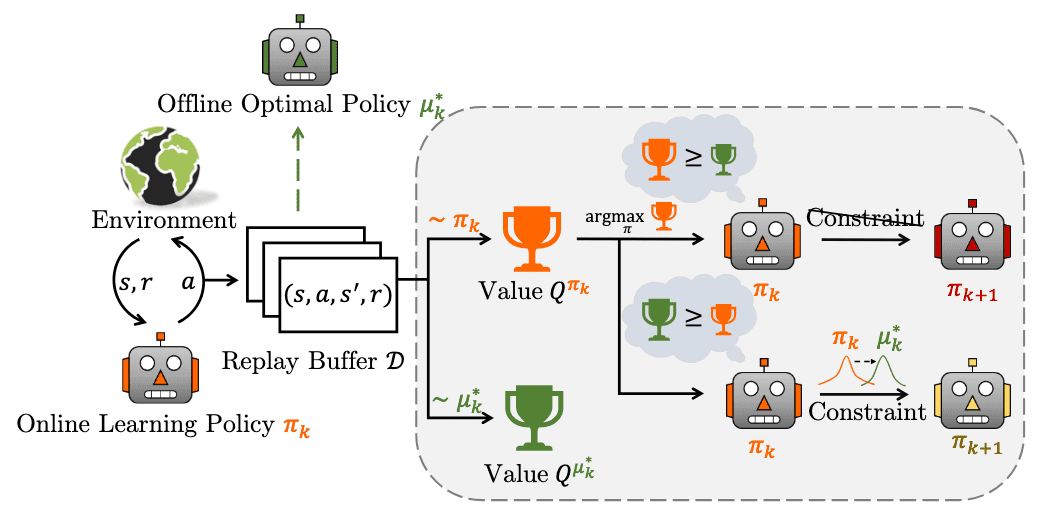
We propose Learning Off-Policy with Online Planning (LOOP) as a framework of using H-step lookahead policies that combines online trajectory optimization with model -free off-policy RL (Figure1).
Additional Notes on Model Predictive Off Policy Rl
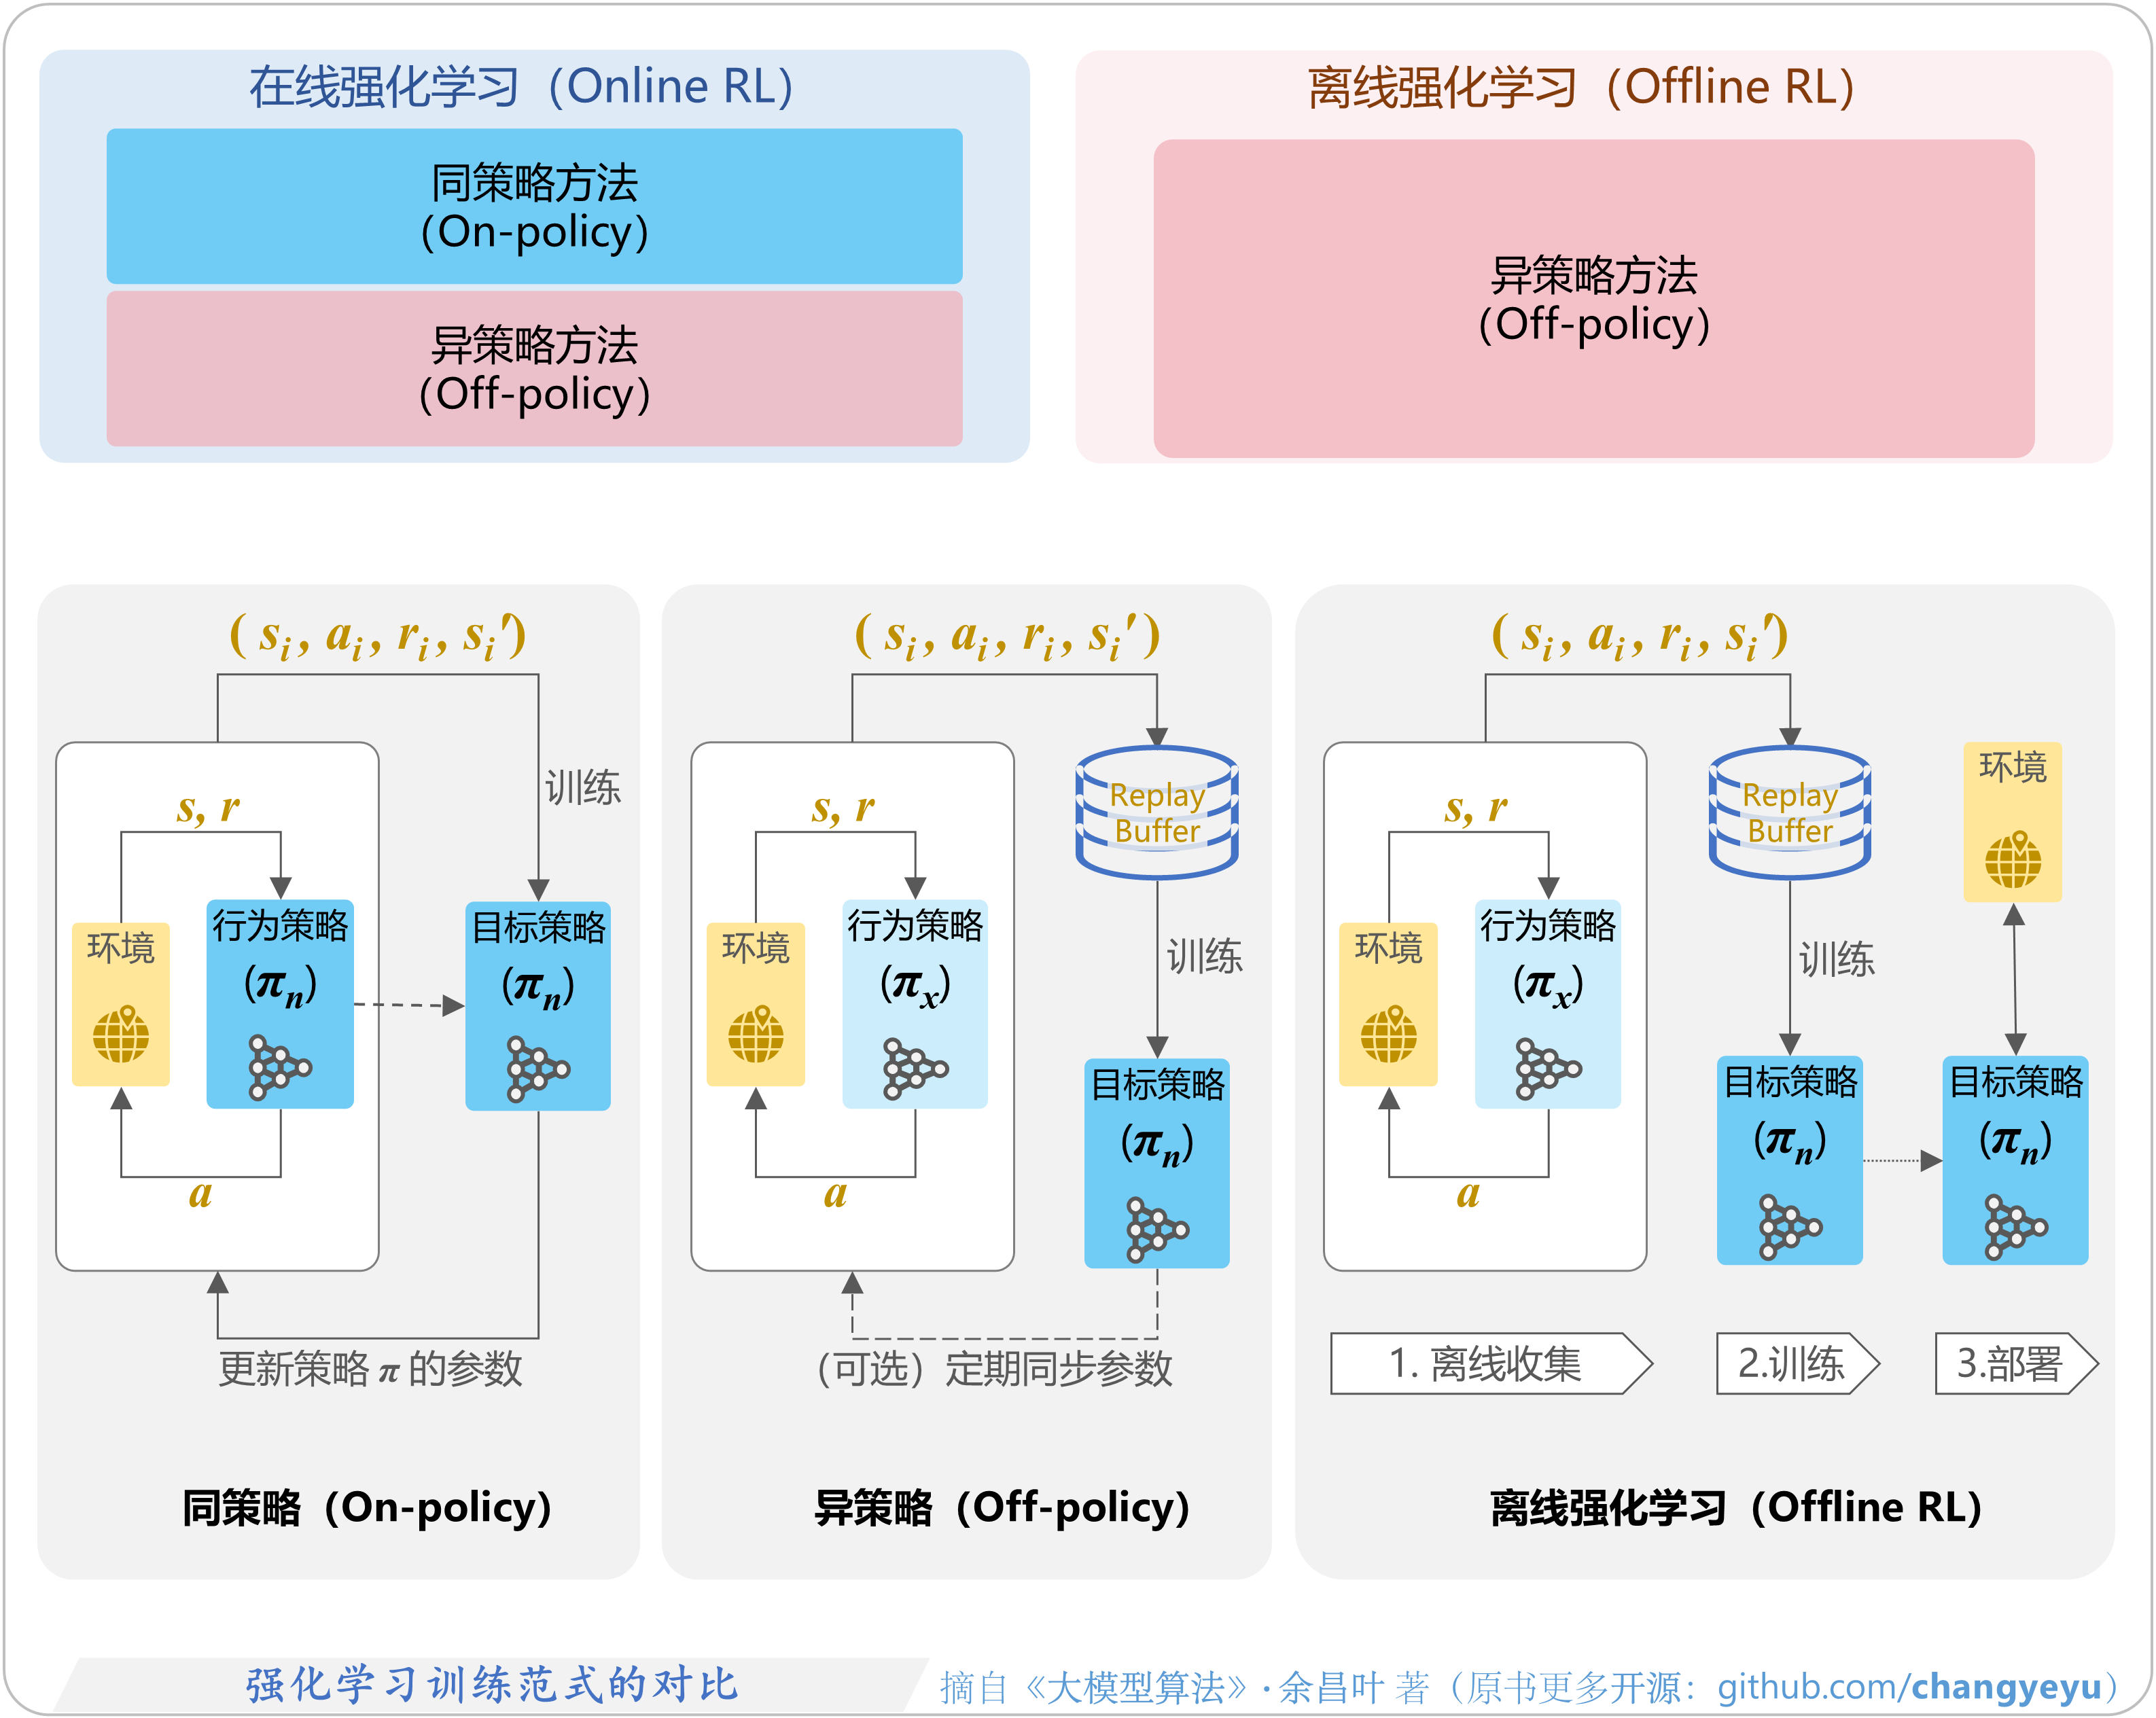
Illustration of classic on-policy RL (a), classic off-policy RL (b. For Model Predictive Off Policy Rl, this point helps readers notice the most relevant visual details before moving into the gallery.
Improving RL with Lookahead: Learning Off-Policy with Online Planning. It works as a short bridge between the article summary and the gallery section.
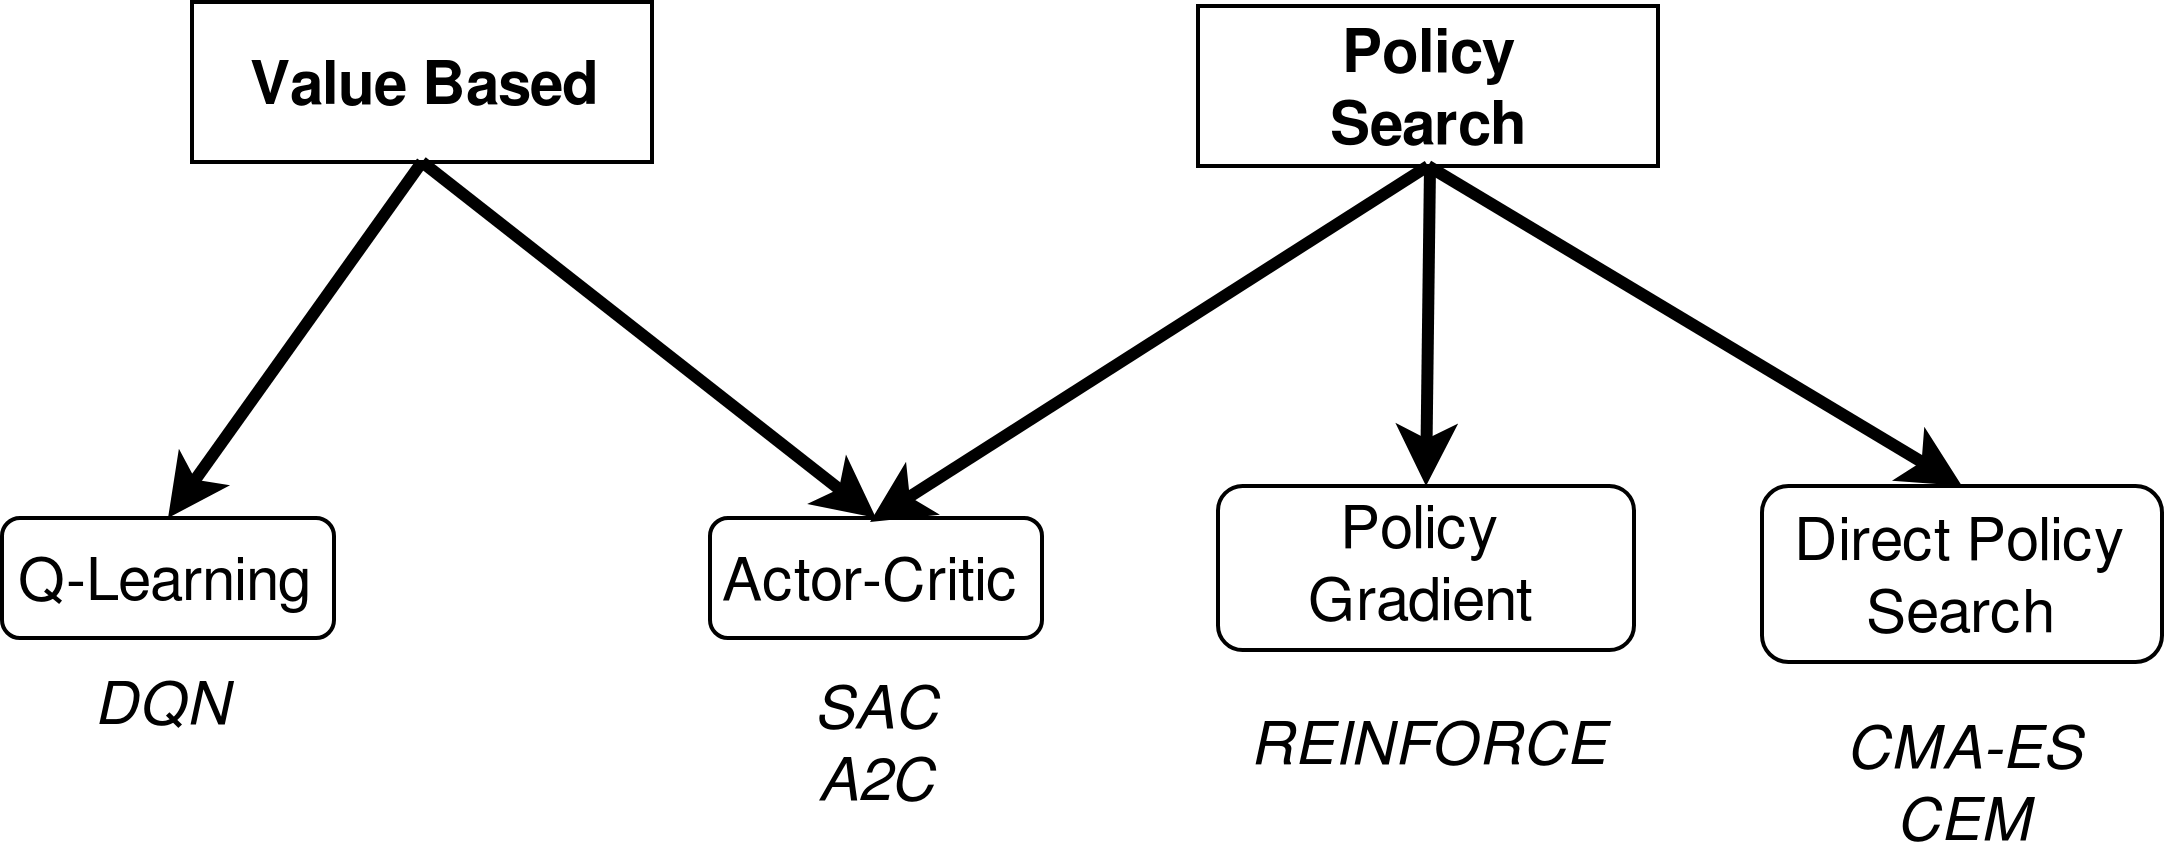
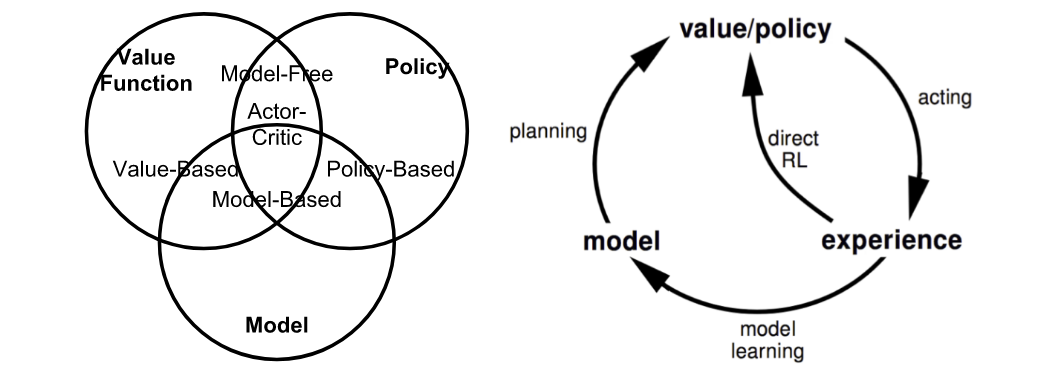
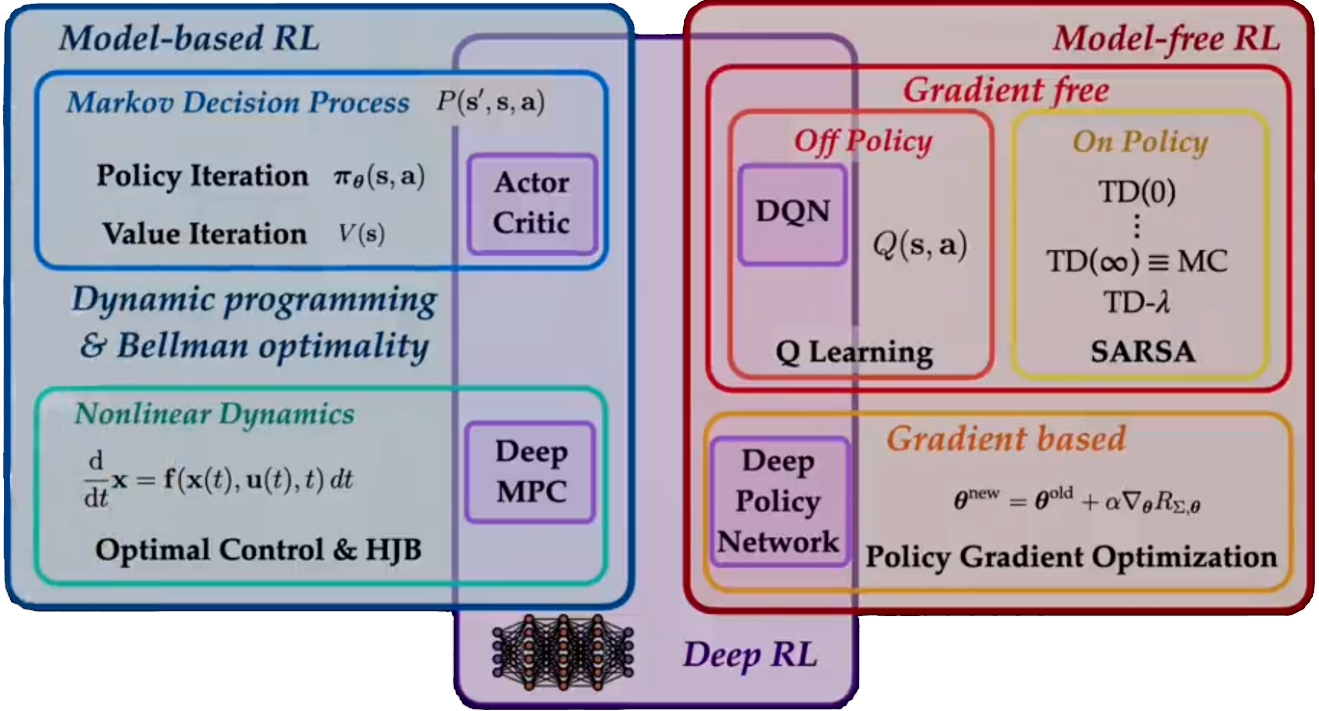
Model-based RL中有哪些经典的算法? - 知乎. This note connects the source idea with the visuals in a simple, reader-friendly way.
Looking at multiple sources also helps separate the main idea from small decorative details.
These notes are added so the page offers more than images and gives each visitor a clearer reason to keep reading.