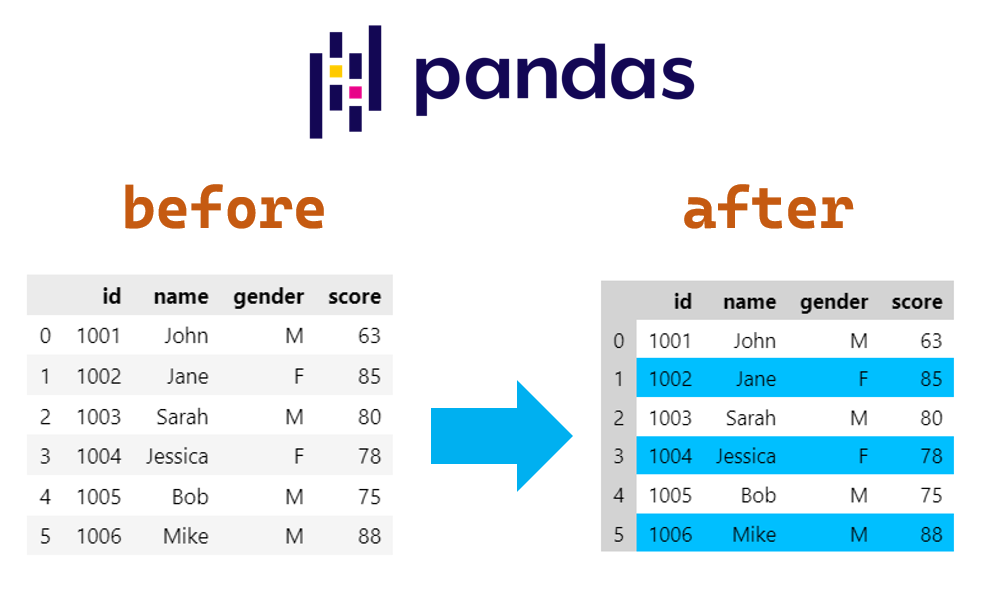
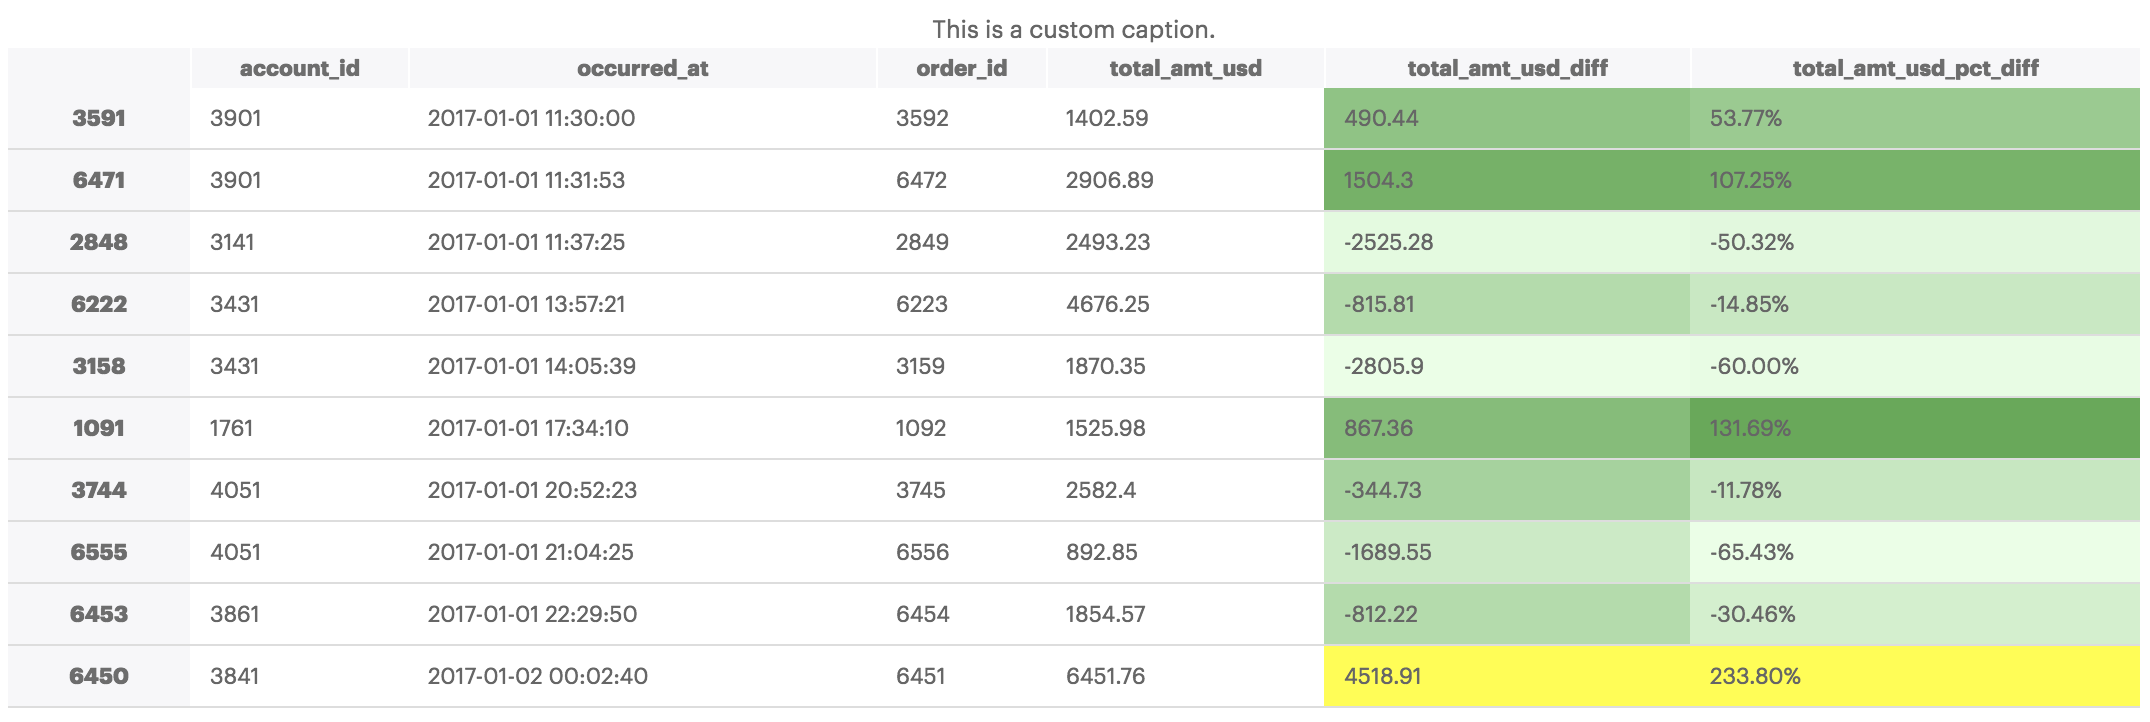
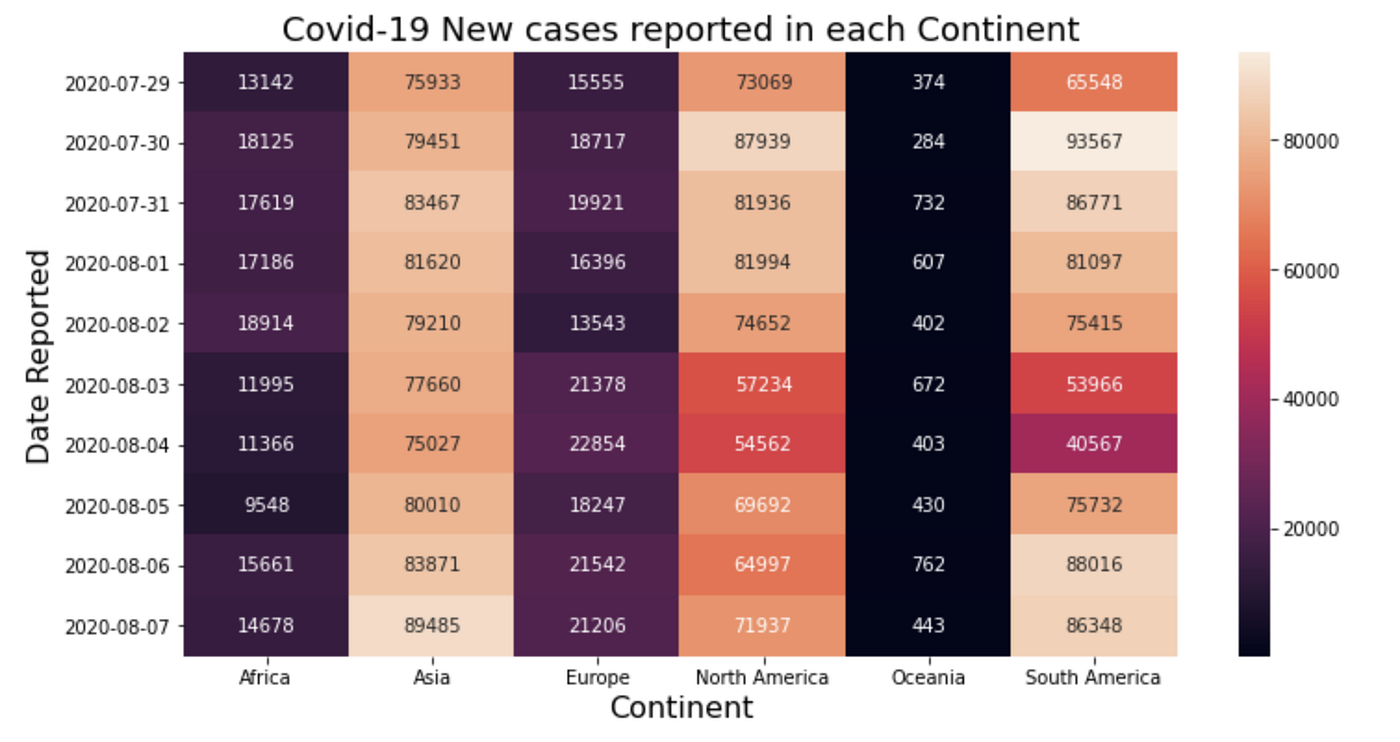
Mastering data presentation in Python often hinges on the ability to highlight specific insights within a DataFrame. The pandas style color row functionality is a powerful feature that allows developers and analysts to transform raw data tables into visually intuitive narratives. By leveraging conditional formatting, users can apply specific background colors to entire rows based on the values they contain, making critical trends and outliers immediately apparent to the eye.
Understanding the Mechanics of Styling
The pandas library achieves this through the built-in Styler object, which acts as a renderer for CSS properties. When you apply a style color row command, you are not modifying the original data itself, but rather generating an HTML representation of the DataFrame. This separation of data and presentation ensures that your analysis remains robust while your visualization is flexible and dynamic.
Applying Conditional Logic
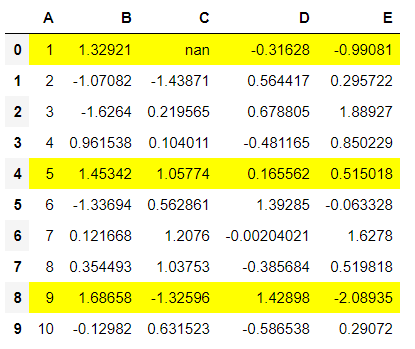
To effectively style an entire row, you must define a function that returns a list of CSS property strings for each row. This function iterates through the values of the row and determines the appropriate color based on specific logic. For instance, you might flag a row in red if a sales figure drops below a threshold, or highlight a row in green if a performance metric exceeds expectations. This logic is applied uniformly across all columns in the targeted row, creating a cohesive visual signal.
Practical Implementation Strategies
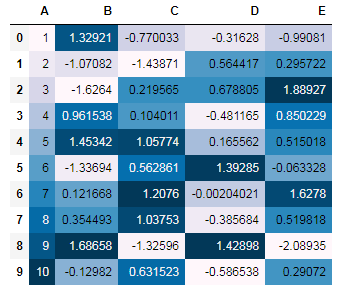
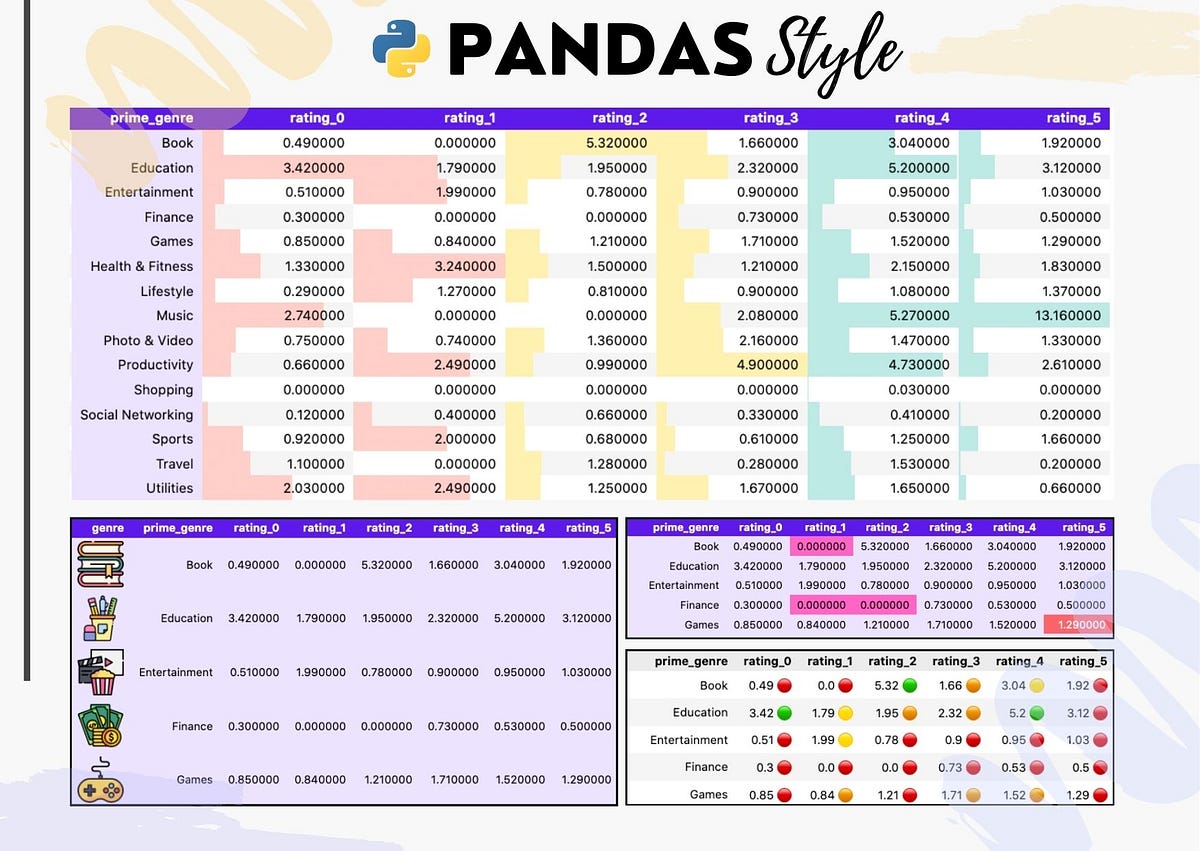
When implementing a style color row, efficiency is key. Using the `axis=1` parameter in the `apply` method allows your function to operate on rows rather than columns. You should aim to keep your styling function lightweight to prevent slowdowns with large datasets. Furthermore, combining multiple conditions within your logic allows for complex visualizations, such as zebra striping for readability or gradient coloring based on magnitude.
Handling Specific Data Types
It is important to account for data type variations when writing your styling function. Numeric values are straightforward for comparisons, but string data requires careful handling to avoid errors. Converting or validating data types within your function ensures that the styling engine runs smoothly. For example, checking if a value is numeric before attempting a mathematical comparison prevents runtime exceptions and ensures the style is applied correctly only where intended.
Optimizing for Readability and Accessibility
While vibrant colors can draw attention, accessibility should never be an afterthought. When choosing your style color row palette, ensure there is sufficient contrast between the text and the background colors. Relying solely on color to convey information can exclude users with visual impairments; therefore, it is best practice to incorporate distinct symbols or text annotations alongside the color coding. This dual-coding method creates a more inclusive data experience.
Exporting and Persistence
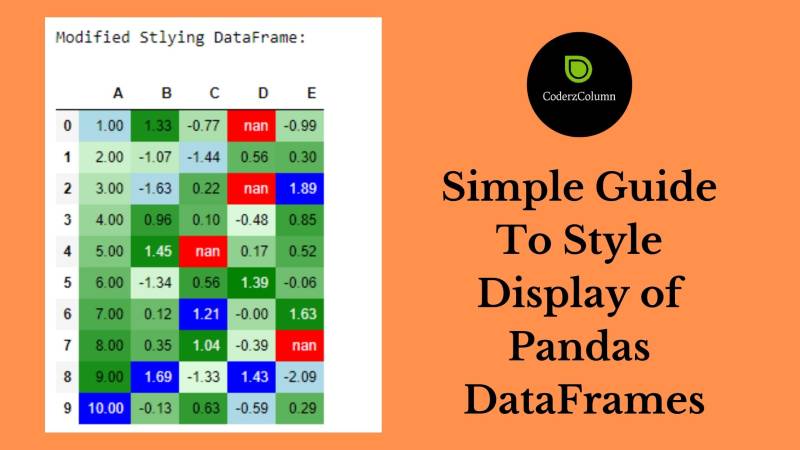
It is vital to understand that the styling applied via pandas is ephemeral unless explicitly exported. When you save a styled DataFrame to an Excel file using `Styler.to_excel`, the CSS styles are converted into static formatting. However, saving to a standard CSV file will discard the styling entirely, retaining only the raw data. Users must plan their export strategy accordingly to preserve the visual context they have meticulously designed.
Advanced Customization Techniques
For those looking to push the boundaries of standard highlighting, pandas allows for the integration of custom CSS classes. Instead of inline styles, you can define classes in a stylesheet and apply them to rows. This approach is beneficial when managing multiple complex styles, as it keeps the code clean and maintainable. It also allows for easier theming, enabling you to switch between light and dark mode visualizations with minimal adjustments to your core logic.