Discovering the Beauty of Parsing Csv Data With Pandas Performance in Pictures
How to Spot (and Fix) 5 Common Performance Bottlenecks in pandas ...
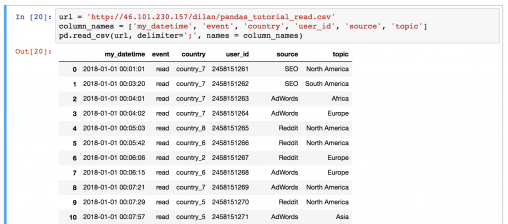
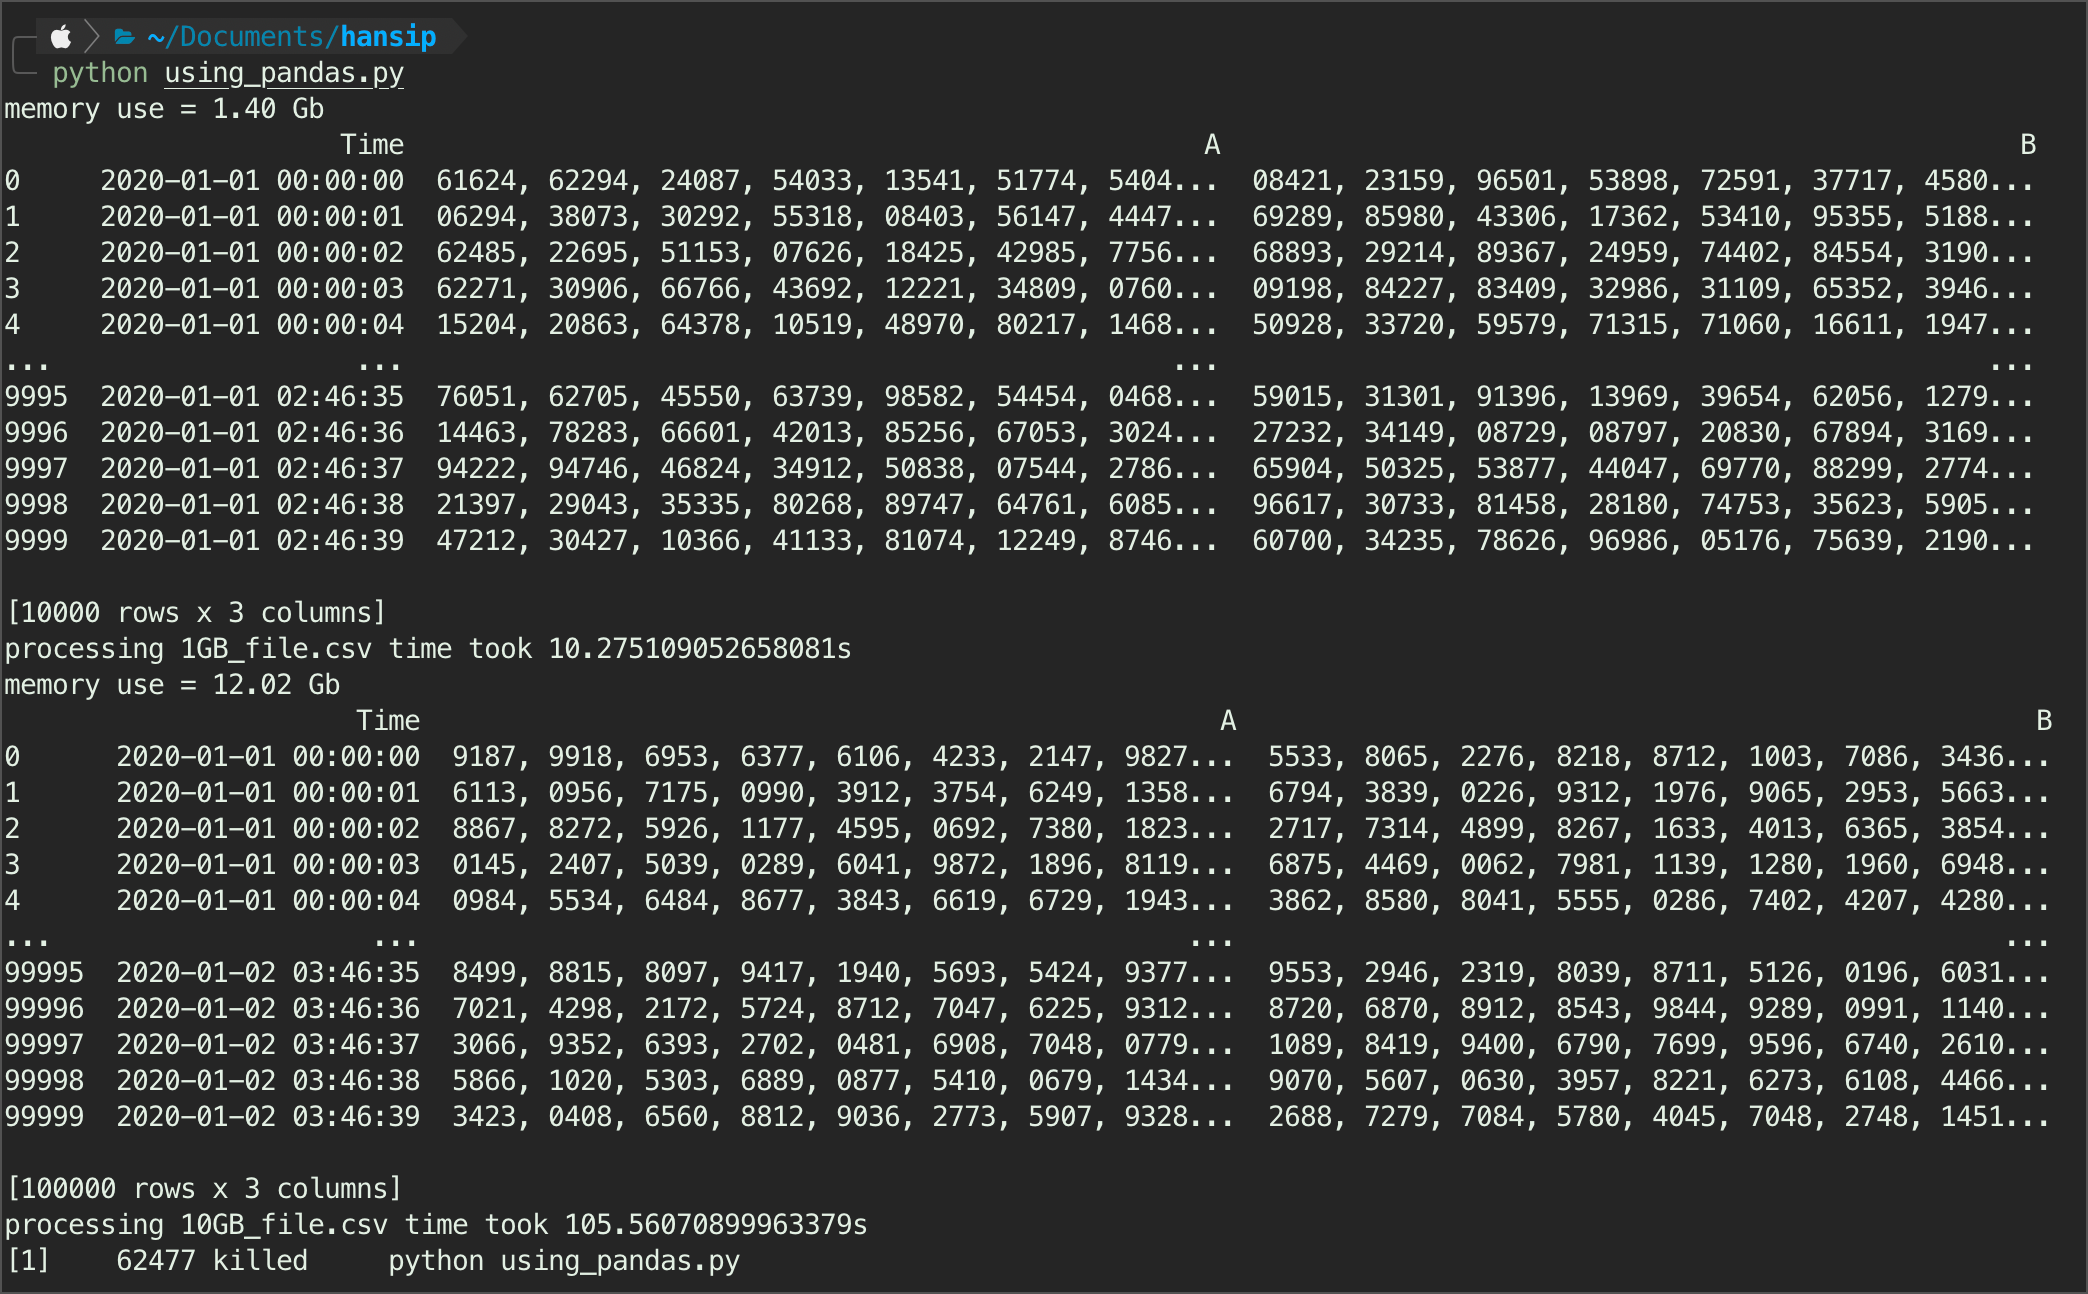
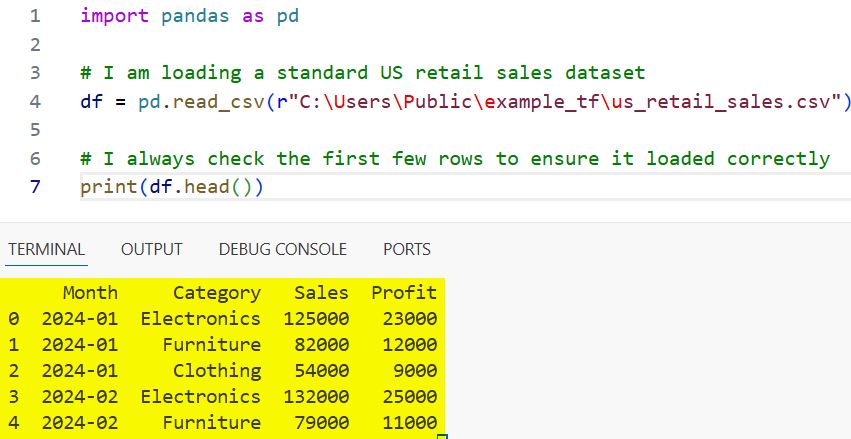
Many of the arguments to read_csv have important performance considerations. pd.read_csv is optimized to smooth over a large amount of variation in what can be considered a csv , and the more magic pandas has to be ready to perform (determine types, interpret nans, convert dates (maybe), skip headers/footers, infer indices/columns, handle bad ...
Parsing Csv Data With Pandas Performance
pandas.readcsv pandas 3.0.3 documentation
Parsing Csv Data With Pandas Performance
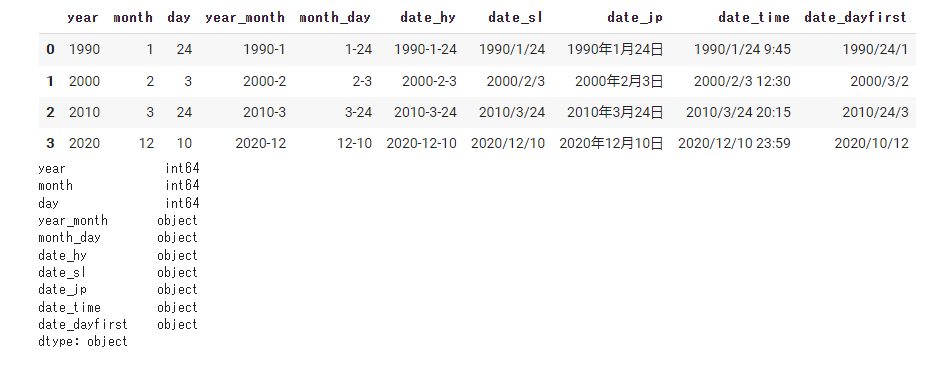
If [1, 2, 3] -> try parsing columns 1, 2, 3 each as a separate date column. If a column or index cannot be represented as an array of datetime, say because of an unparsable value or a mixture of timezones, the column or index will be returned unaltered as an object data type. For non-standard datetime parsing , use to_datetime() after read_csv().
Parsing Csv Data With Pandas Performance
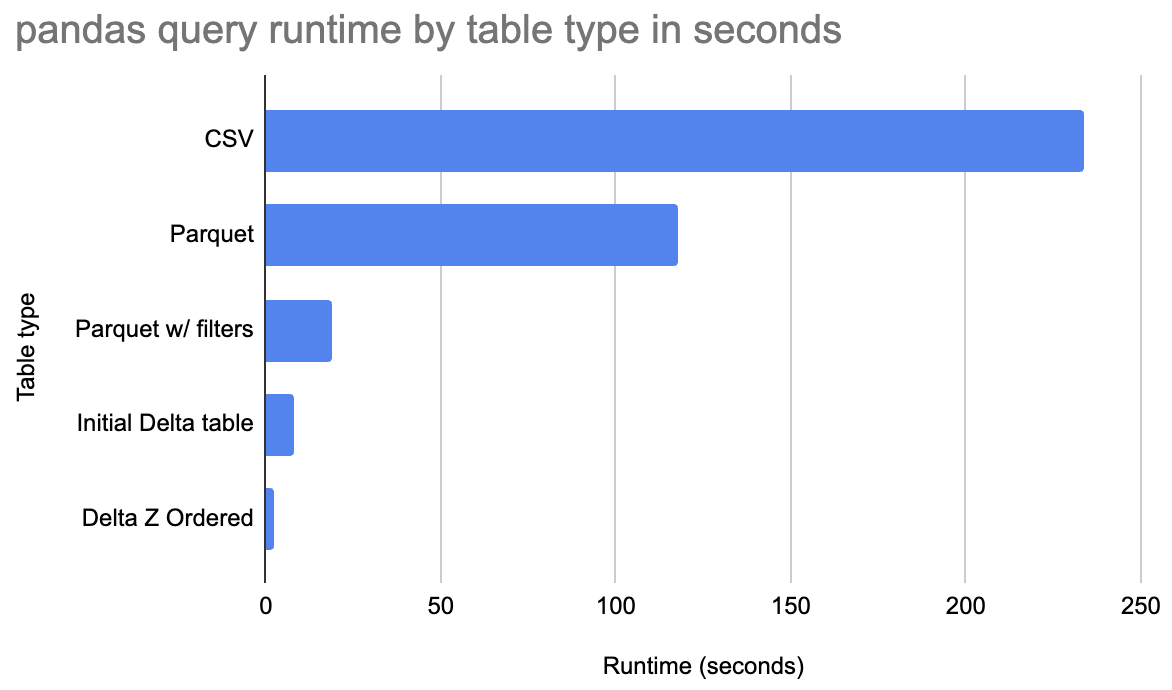
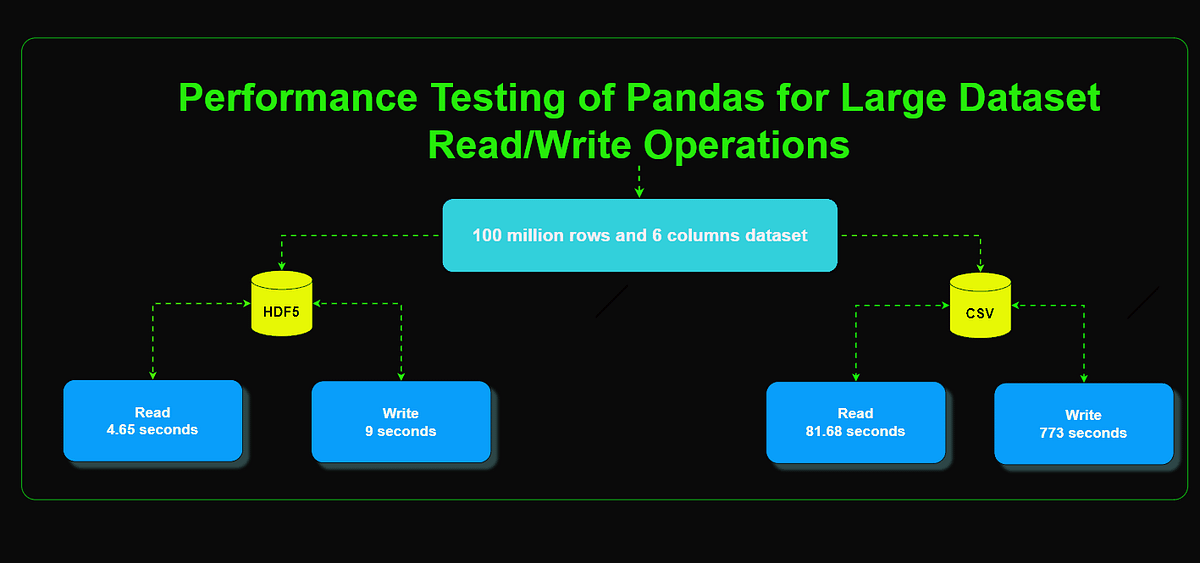
Instead of reading in a CSV , you could read in some other file format that is faster to process. Let's see an example, using the Parquet data format. Parquet files are designed to be read quickly: you don't have to do as much parsing as you would with CSV .