Print All Pandas DataFrame Rows: Easy Step-by-Step Guide
Read about Print All Pandas DataFrame Rows: Easy Step-by-Step Guide on Rhuok Ideas.
Working with data in Python often requires a complete view of your dataset, especially during the initial exploration phase. When you load a new DataFrame, it is common to want to inspect every single entry to understand its structure, identify anomalies, or verify the results of a cleaning operation. By default, however, pandas utilizes a truncation mechanism to display only a portion of the data, which can be frustrating when you need to see the full list.
Understanding the Default Display Truncation
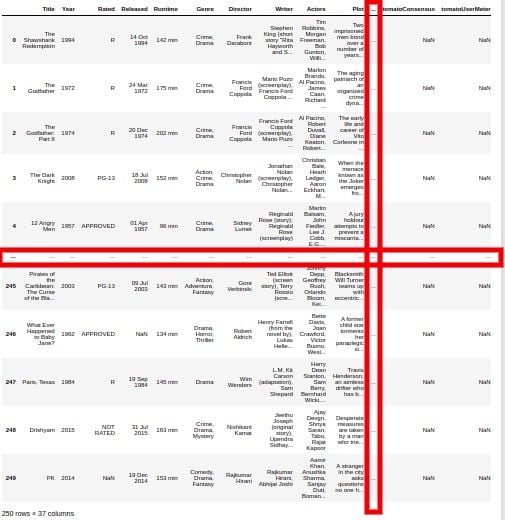
Pandas is designed to provide a concise overview rather than overwhelming the user with massive datasets. When you execute a command like print(df) or simply df in a Jupyter notebook, the library checks the current settings for max_rows. If your DataFrame exceeds this threshold—which is set to 60 rows by standard configurations—pandas will automatically apply slicing. This results in the display of the first few rows and the last few rows, with a省略 (ellipsis) in the middle to indicate omitted content.
The Role of Pandas Options
The behavior of row display is governed by a set of global options that act as configuration settings for the library. These options allow developers to balance readability against completeness. To print out all rows, you do not need to iterate through the data manually or convert it to a different structure; instead, you adjust these options temporarily or permanently to remove the upper limit on displayed rows.
Method 1: Adjusting the Max Rows Parameter
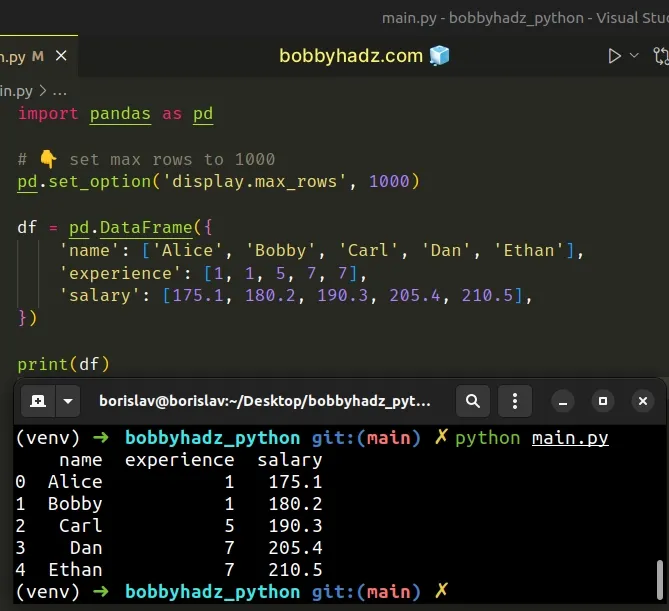
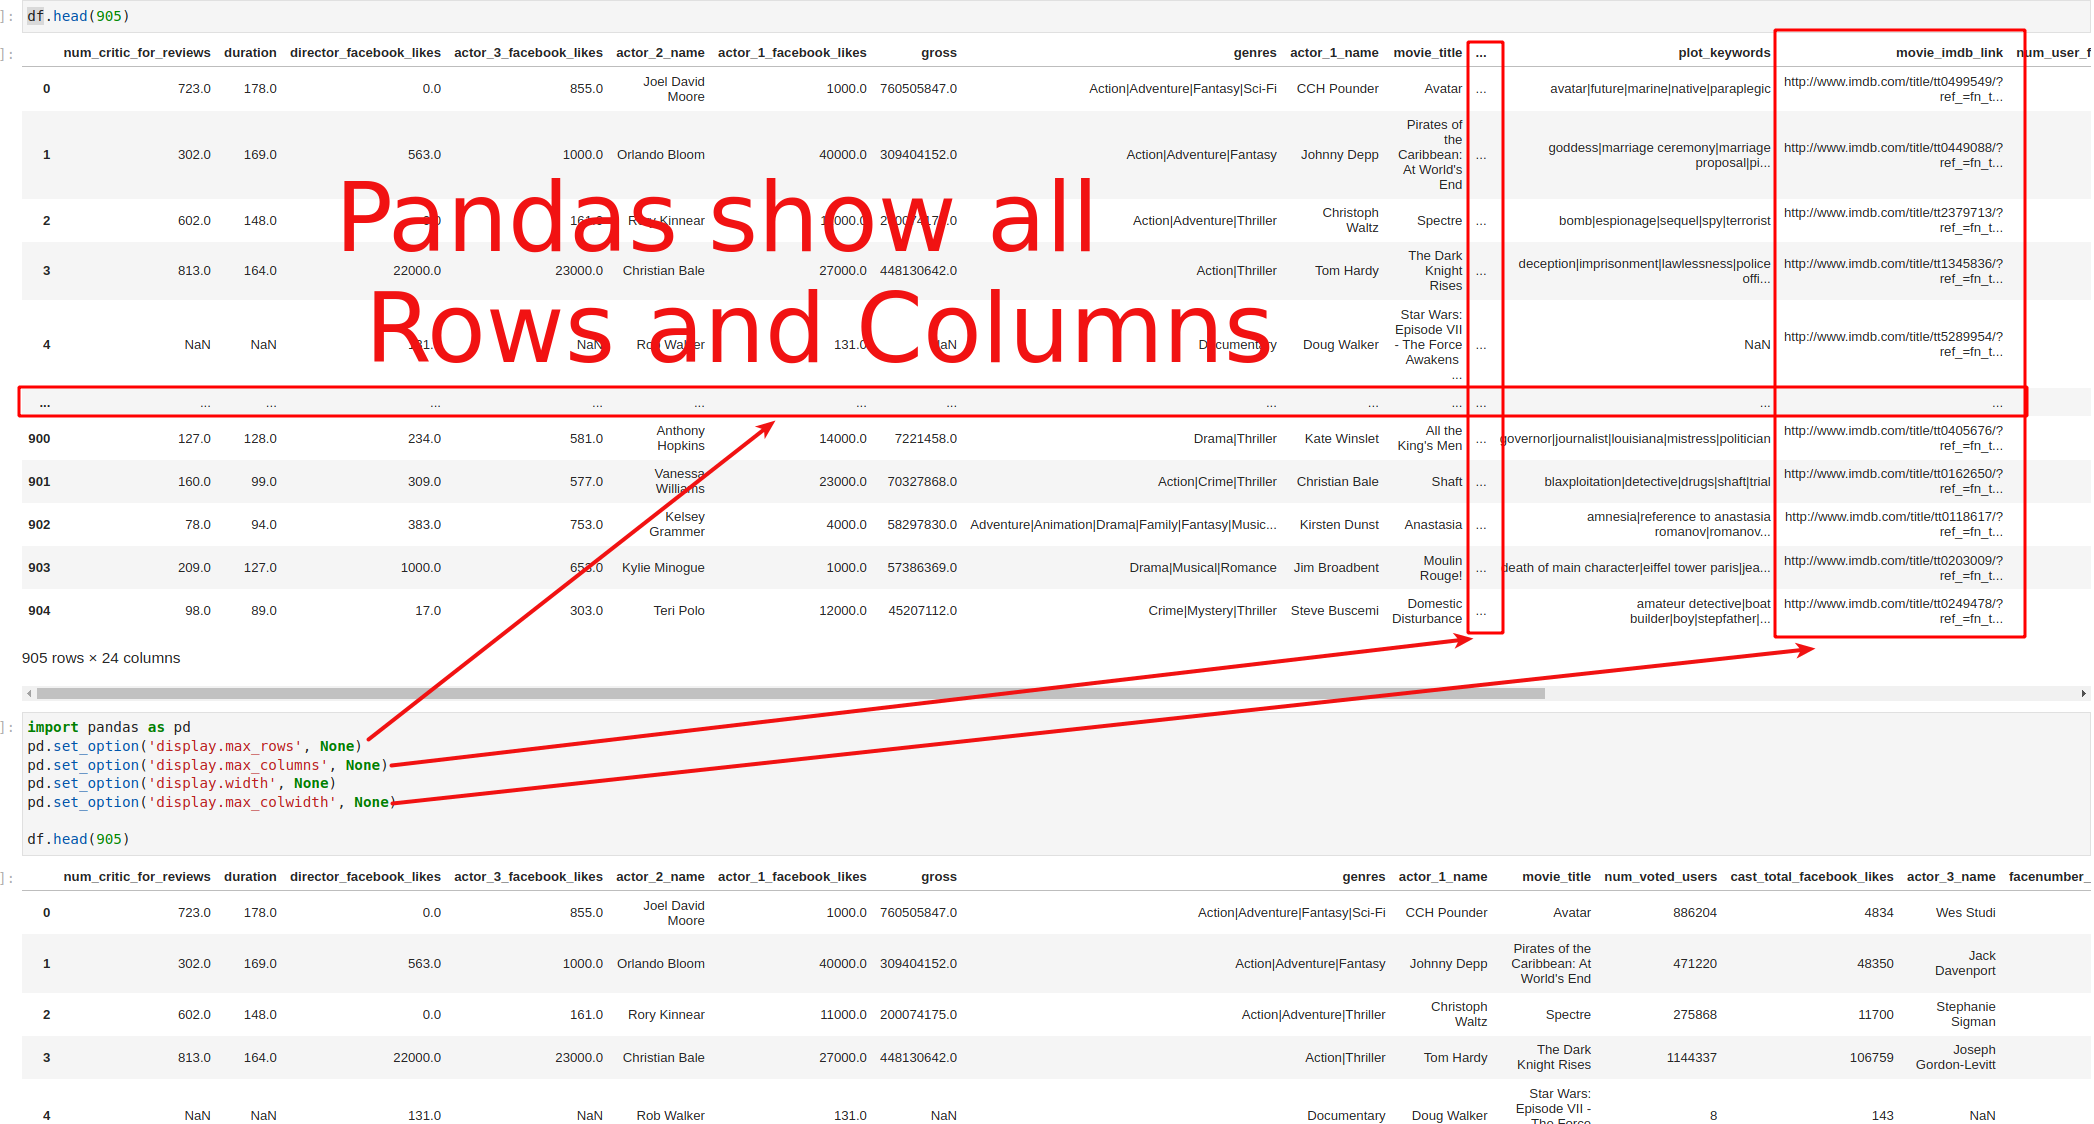
The most direct approach to forcing pandas to render every row is to modify the pd.set_option function. Specifically, you target the display.max_rows parameter. Setting this value to a number larger than your DataFrame's total row count ensures that truncation logic is never triggered. The following snippet demonstrates how to implement this change:
import pandas as pdpd.set_option('display.max_rows', 500)
By inputting a sufficiently large number, you effectively disable the automatic truncation, allowing the console or notebook to render the entire dataset from top to bottom.
Method 2: The Context Manager for Temporary Changes
While adjusting the global option is effective, it can lead to unintended side effects in subsequent code cells, especially in interactive environments. Pandas offers a more elegant solution through the option_context manager. This method allows you to apply the setting change only for the duration of a specific block of code. Once the block is exited, the original settings are automatically restored, ensuring that your environment remains clean for other operations.
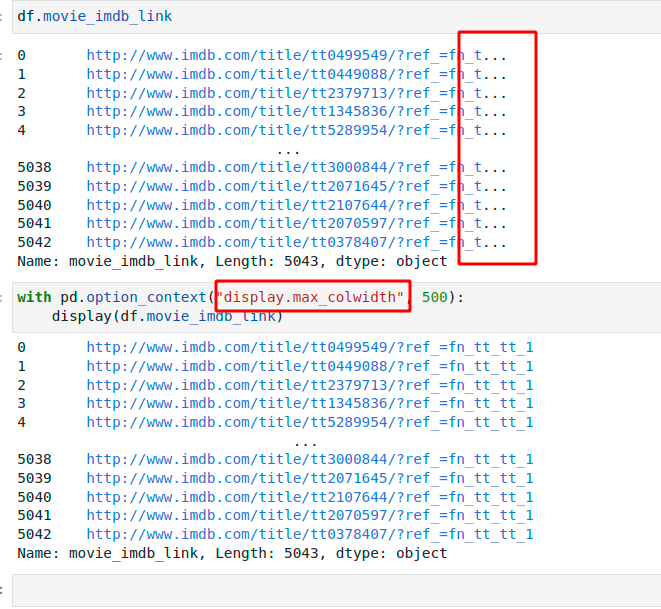
To utilize this method, you wrap your printing logic inside a with statement, specifying the temporary limit for max_rows. This is particularly useful when you are debugging a specific section of code without altering the global state for the entire session.
Handling Extremely Large Datasets
It is important to consider the practical implications of printing every row. While adjusting the option solves the technical problem, displaying a DataFrame with millions of rows can crash your Python kernel or make the output impossible to read. In such scenarios, it is often more efficient to rely on alternative verification methods. For instance, using df.head(100) to check the top entries or df.sample(10) to inspect random rows provides a safer way to validate data integrity without overwhelming your system resources.
Verification and Output Formatting
After applying the configuration change, executing the print command will yield a linear list of all rows indexed on the left side. You will observe that the省略 (ellipsis) disappears, replaced by the complete index of your dataset. This allows for thorough manual verification, ensuring that data types are consistent, indexes are sequential, and there are no unexpected missing values lurking in the middle of your transaction log or time series data.