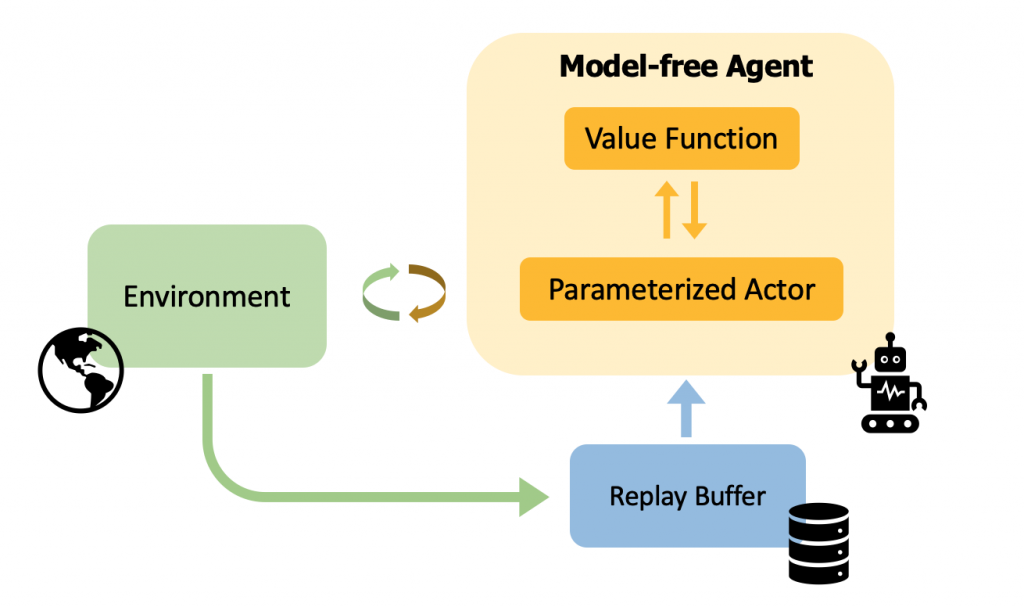
Overview of Autonomy Off-Policy Rl
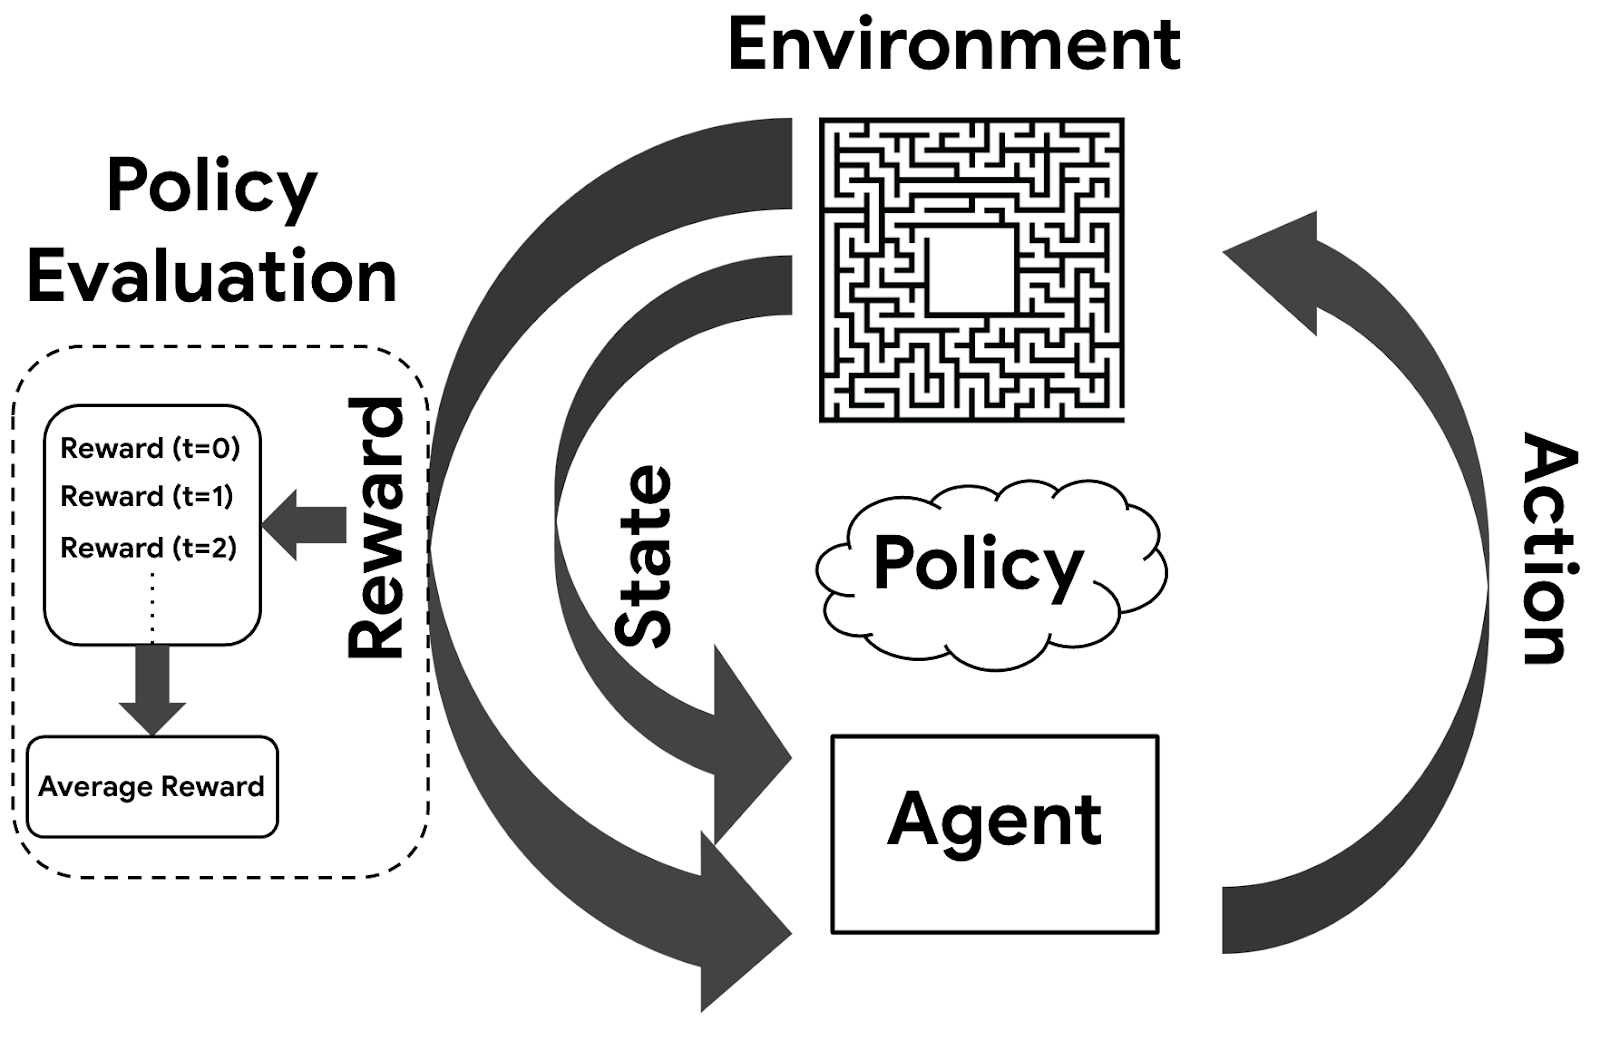
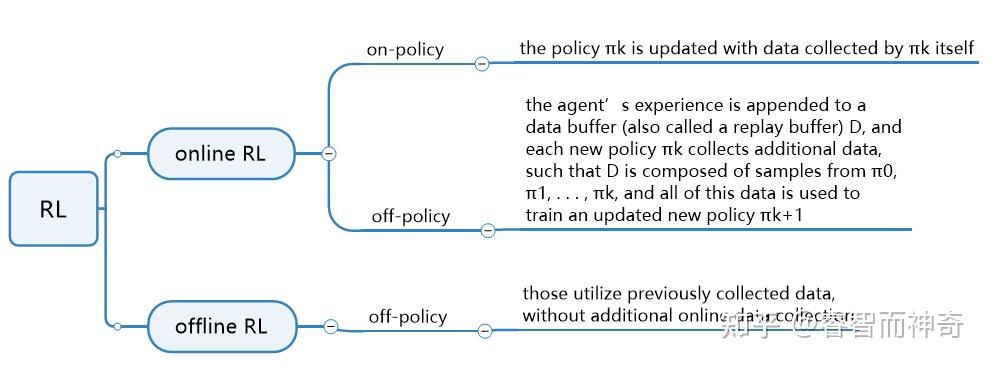
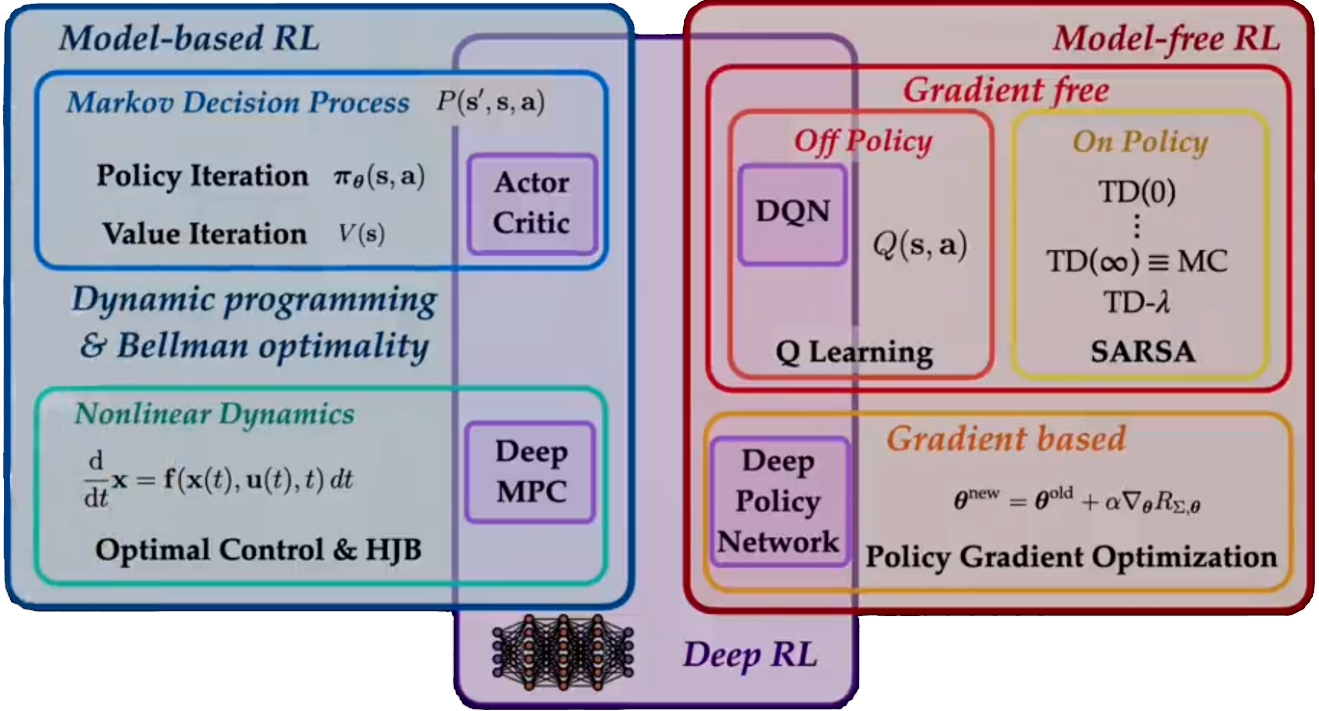
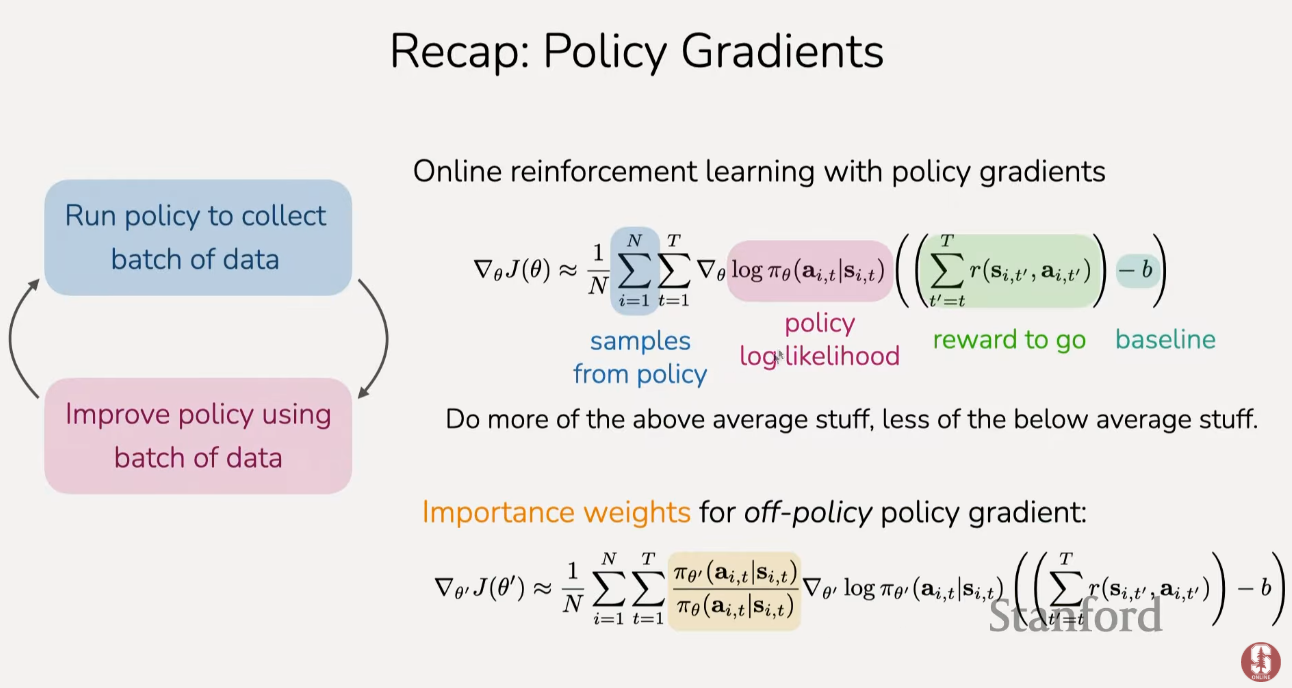
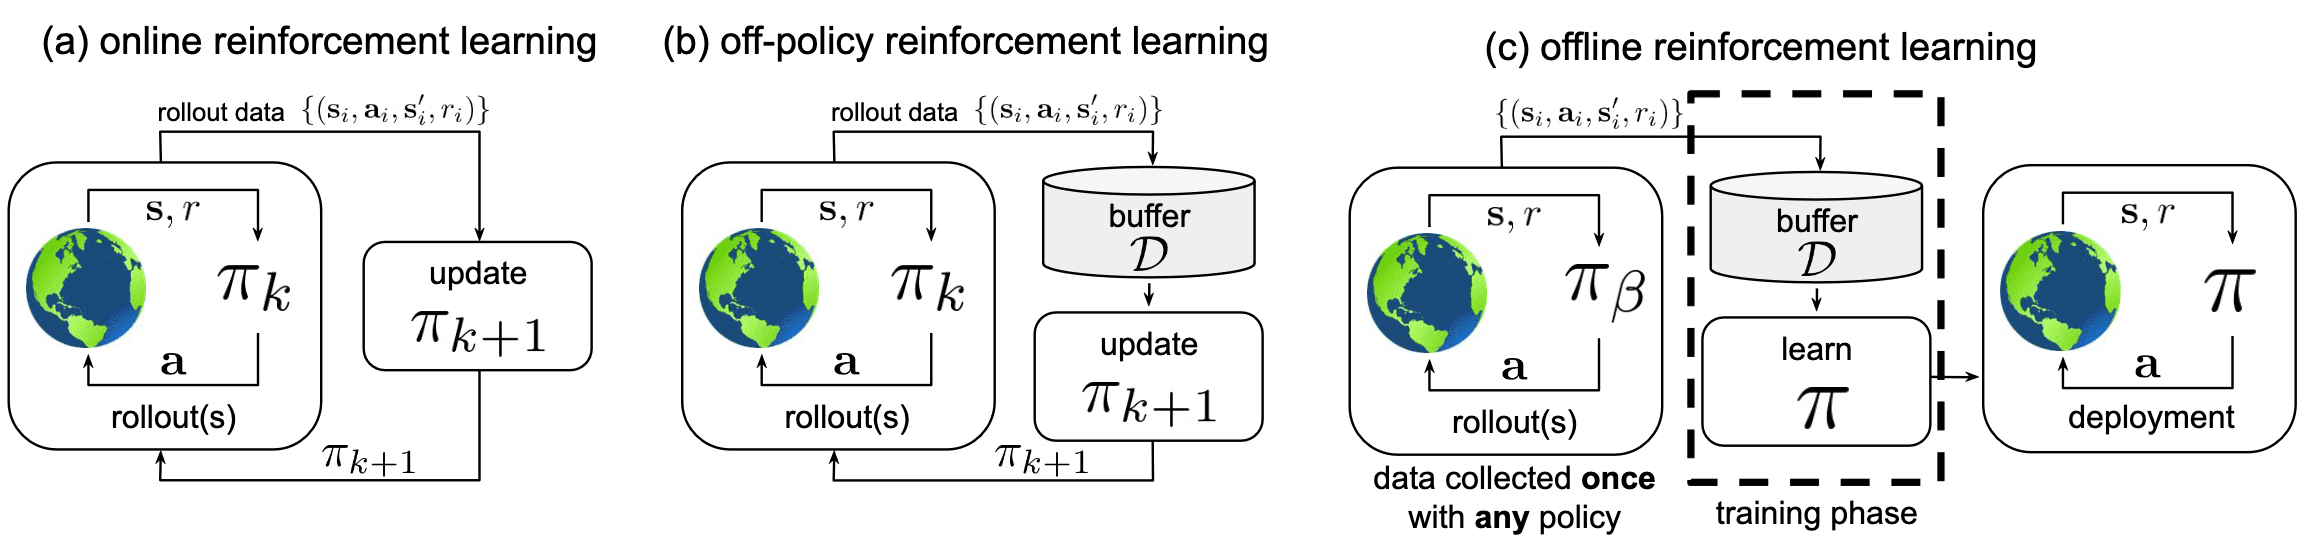
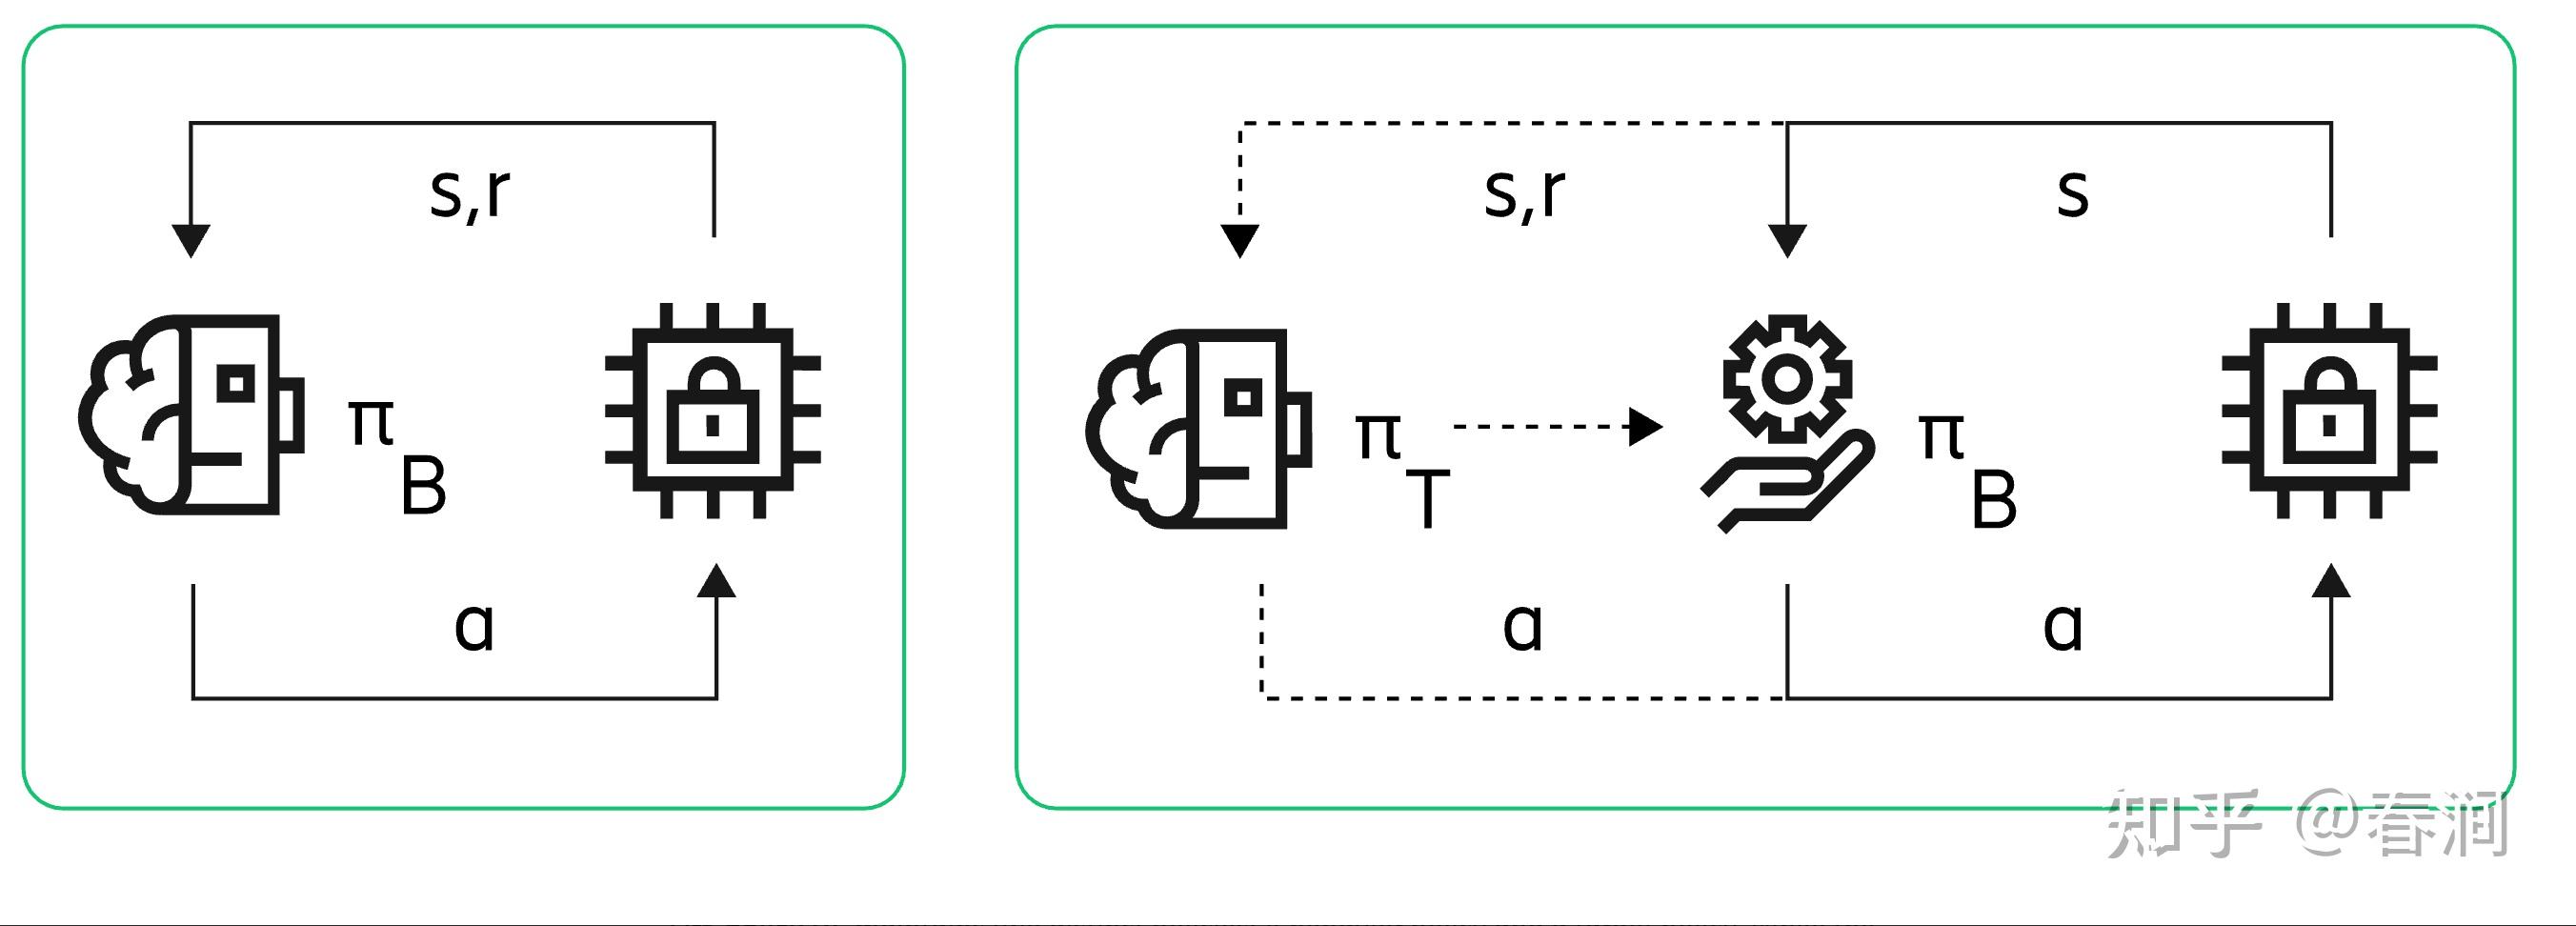
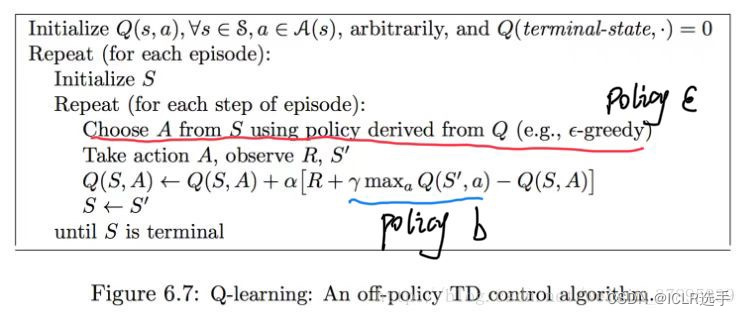
In the world of Reinforcement Learning ( RL ), two primary approaches dictate how an agent (like a robot or a software program) learns from its environment: On- policy methods and Off-policy methods. Understanding the difference between these two is crucial for grasping the fundamentals of RL .

Moving forward, it's essential to keep these visual contexts in mind when discussing Autonomy Off Policy Rl.
Residual Off
We present a recipe that combines the benefits of BC and RL through a residual learning framework. Our approach leverages BC policies as black-box bases and learns lightweight per-step residual corrections via sample-efficient off-policy RL .
More Context About Autonomy Off Policy Rl
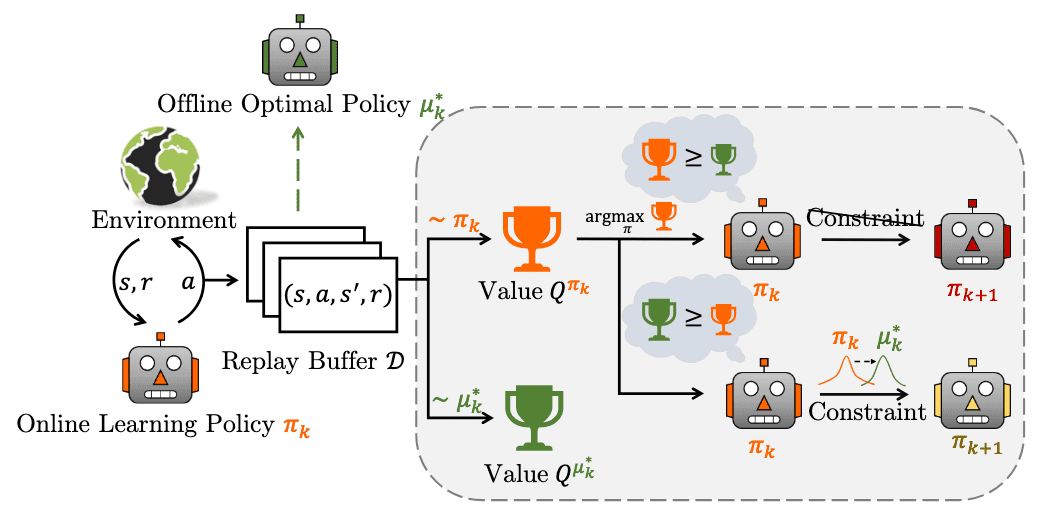
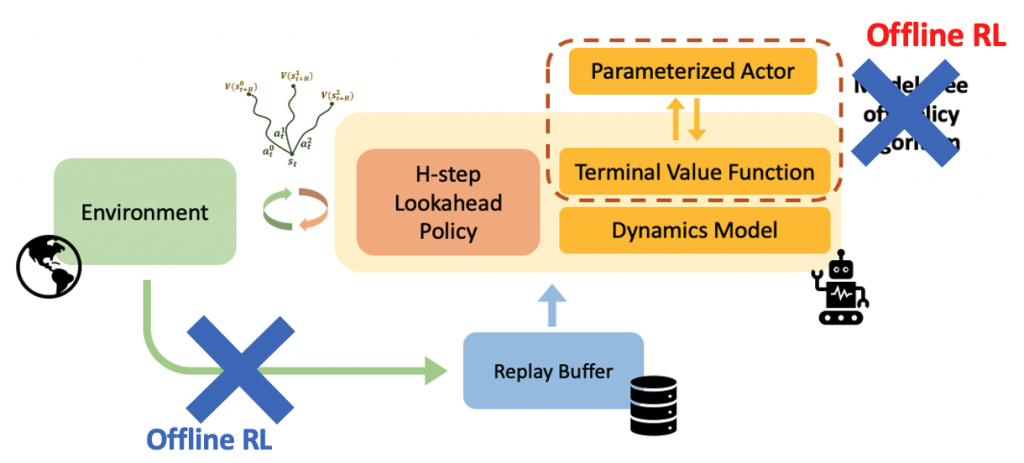
Improving RL with lookahead: learning off-policy with online planning. This note connects the source idea with the visuals in a simple, reader-friendly way.
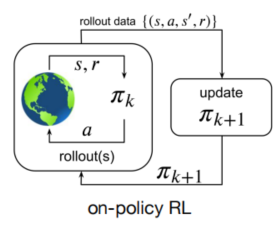
Illustration of classic on-policy RL (a), classic off-policy RL (b. It gives the article a little more context before the image collection begins.
Off-policy RL controller for adaptive tip-tracking control of TLFM. This note connects the source idea with the visuals in a simple, reader-friendly way.
Looking at multiple sources also helps separate the main idea from small decorative details.
These notes are added so the page offers more than images and gives each visitor a clearer reason to keep reading.