In the early days of digital publishing, managing content was a chaotic affair. Teams juggled inconsistent file formats, proprietary software lock-ins, and a constant struggle to keep print and digital outputs in sync. XML emerged as the quiet revolution that brought order to this chaos, providing a structural language that could separate content from presentation. Today, XML-based publishing systems are the invisible engines powering everything from global regulatory filings and technical documentation to multi-channel retail catalogs. Understanding how these systems function is essential for any organization looking to scale content production, automate workflows, and future-proof their digital assets.
The Separation of Content and Format
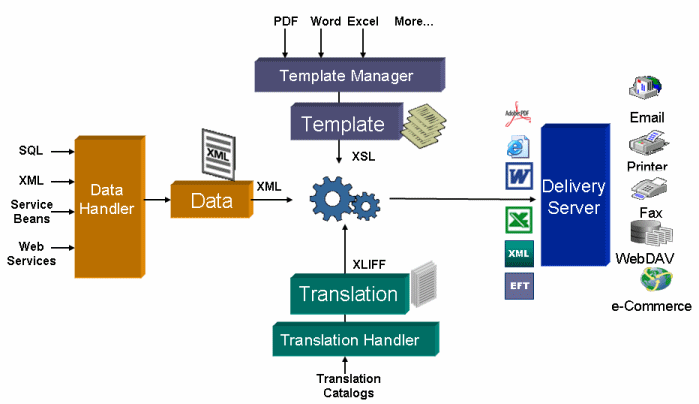
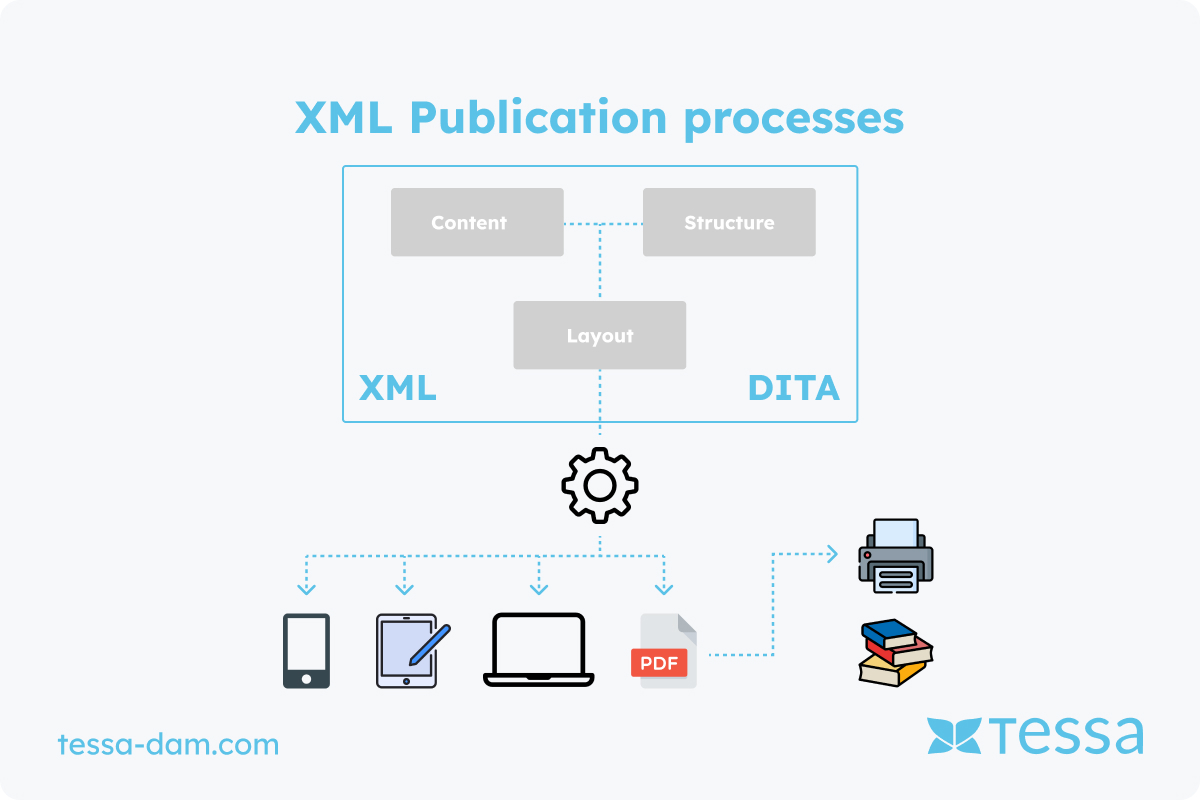
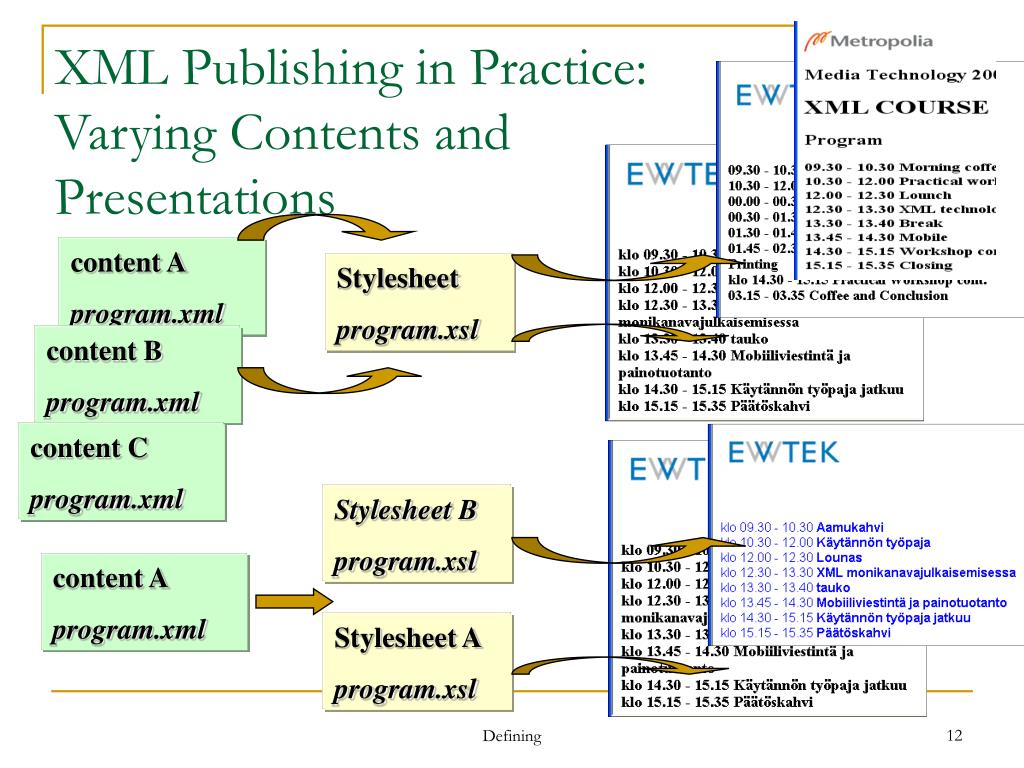
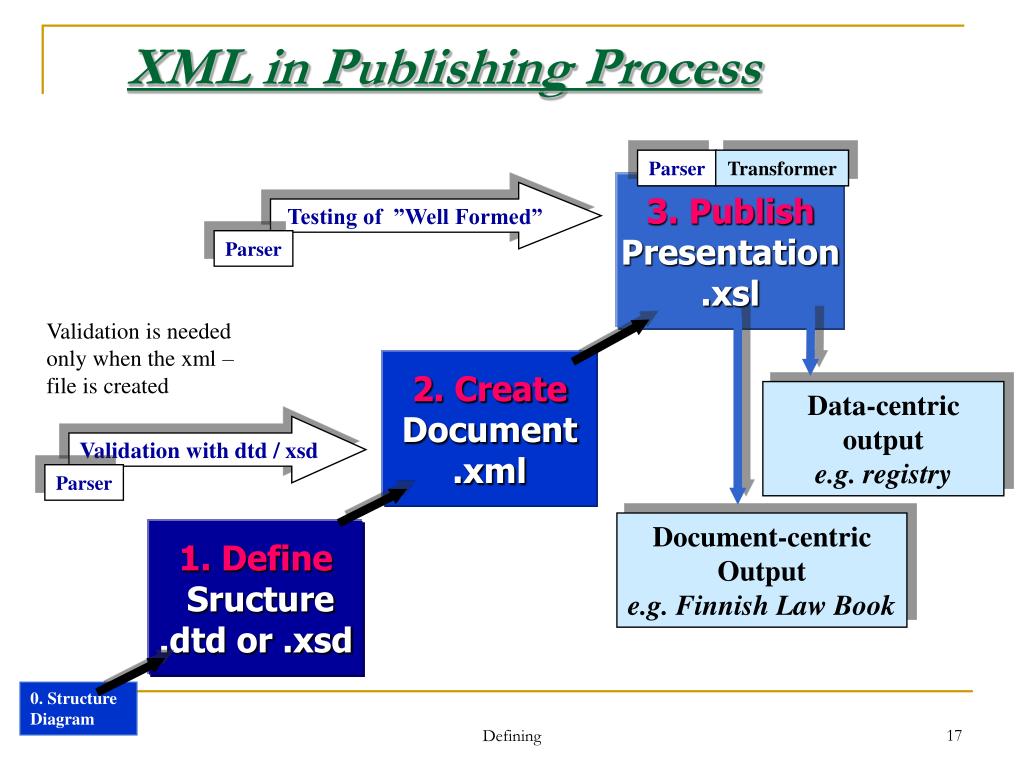
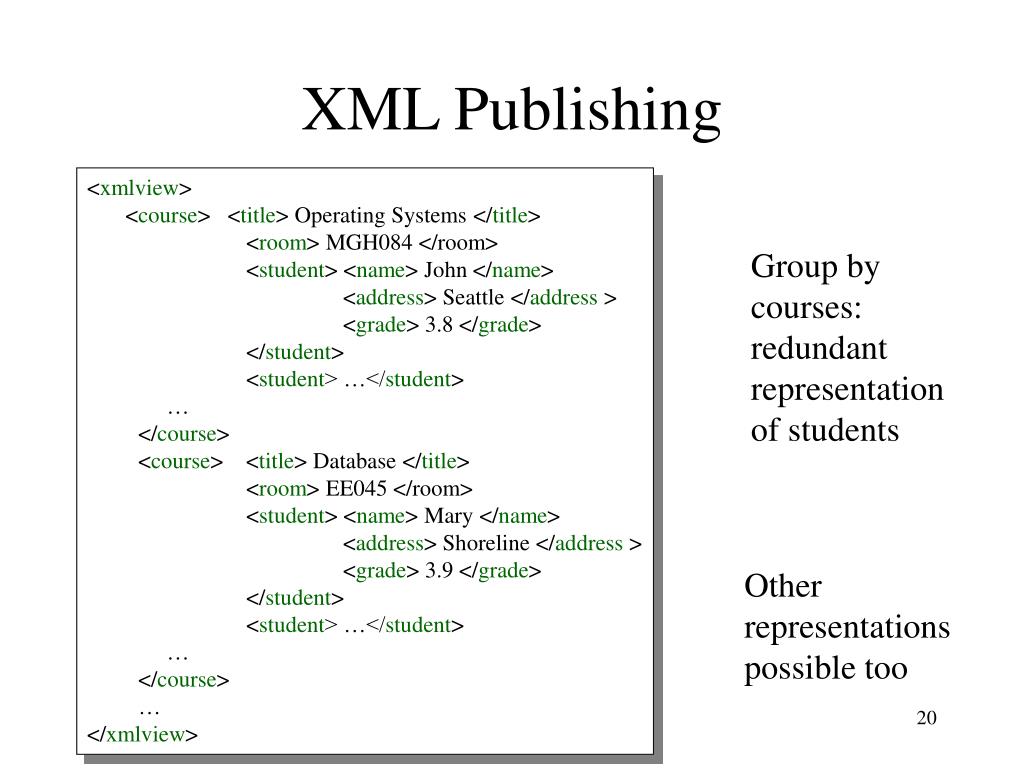
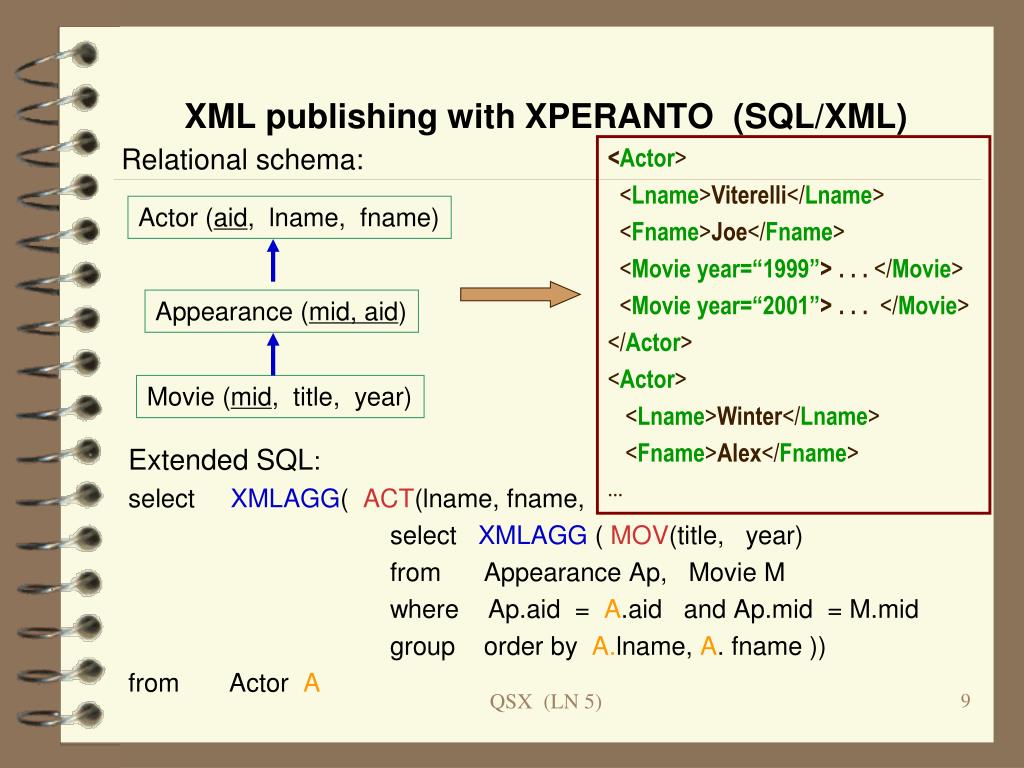
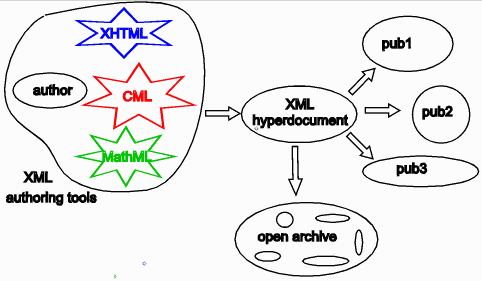
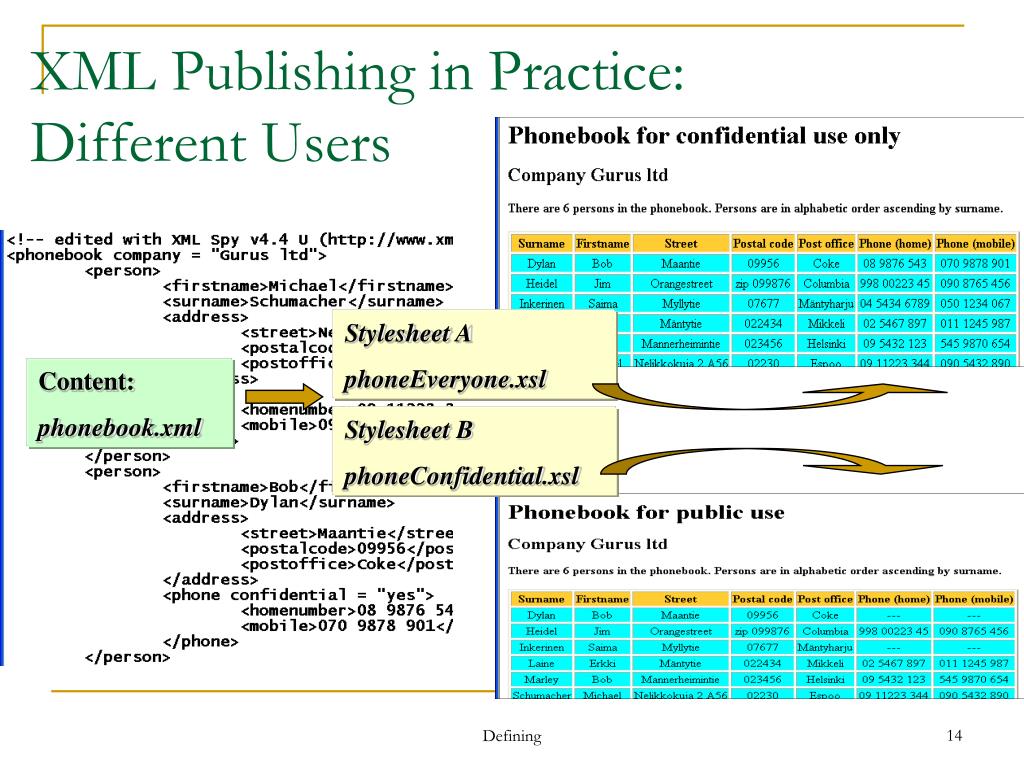
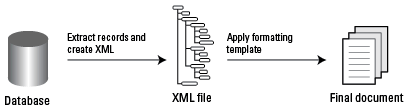
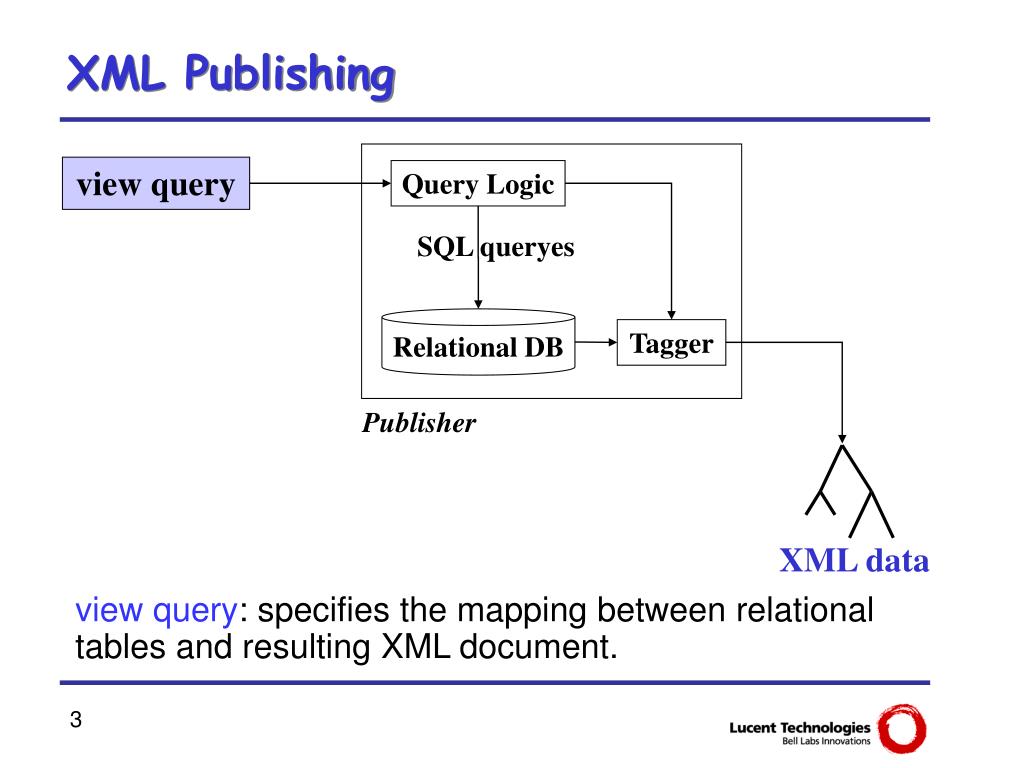
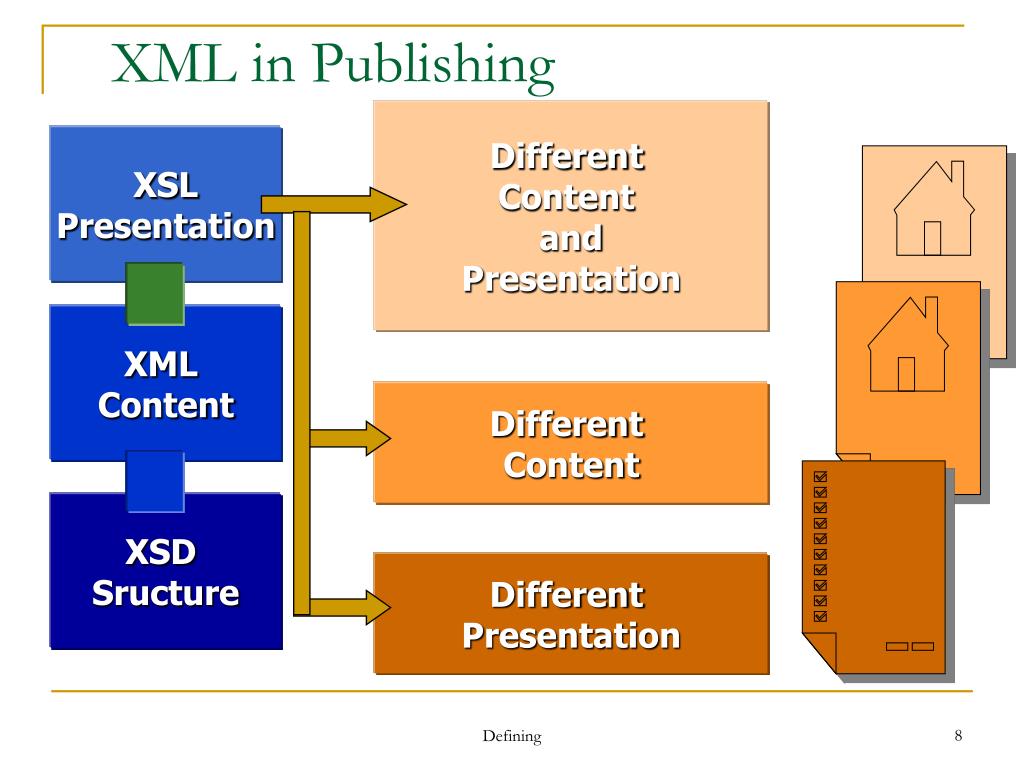
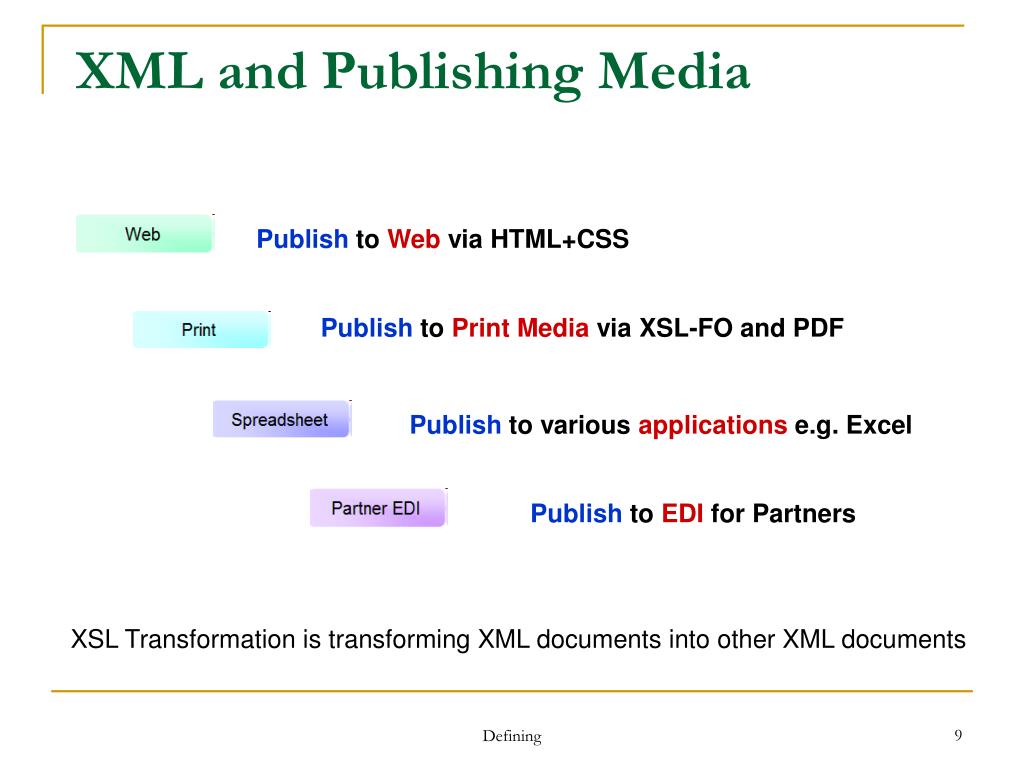
The fundamental principle behind XML-based publishing lies in the strict separation of content and formatting. In a traditional word processing environment, what you see is what you get. An author applies a bold style, sets a font size, and hopes for the best when the document is repurposed. XML flips this model entirely. The content is marked up with descriptive elements such as <heading>, <paragraph>, and <listitem>, which describe what the content is, not how it looks. The visual styling is then applied later through transformation languages like XSLT. This decoupling means a single XML source file can be transformed simultaneously into HTML for the web, an EPUB for e-readers, a PDF for print, and even JSON for an API, without redundant manual effort.
Why Structure Matters
Without enforced structure, large-scale publishing is impossible. Consider a pharmaceutical company submitting documentation to regulatory bodies across fifty countries. If content is unstructured, a minor change in safety guidelines requires a human editor to hunt through thousands of pages. In a structured XML environment based on a standard like DITA, the safety update is made once in the core module. The publishing engine then ripples that change across every language variant and output format automatically. Structure creates predictability; predictability creates automation.

Key Standards and DTDs
XML is a meta-language, meaning it provides the rules for building specific languages tailored to publishing needs. These specific languages are governed by Document Type Definitions (DTDs) or XML Schemas, which define the exact vocabulary and hierarchy a document must follow. Several industries have gravitated toward specific standards because of this rigor. For example, the scholarly publishing world relies on the JATS standard, while the aerospace and defense sectors use S1000D.
The following table highlights a few of the most influential XML schemas in the publishing landscape:
| Standard | Primary Industry | Core Benefit |
|---|---|---|
| DITA | Technical Documentation | Reusable, modular topic-based authoring |
| JATS | Journal Publishing | Interoperable archival of scholarly articles |
| TEI | Humanities & Literature | Deep encoding of historical and literary texts |
| DocBook | Software & General IT | Book-oriented semantic markup with robust tool support |
The Role of XSLT in Transformation
An XML file sitting on a server is useless to a reader until it is transformed into something presentable. This is where Extensible Stylesheet Language Transformations (XSLT) comes into play. Think of XSLT as the definitive translator between the pure, structural world of XML and the chaotic, pixel-based world of human reading. An XSLT stylesheet reads the XML nodes and applies specific rules to them. If it encounters a <warning> tag, the XSLT might render it with a red border and an icon in the PDF, but with a specific ARIA role for screen readers in the HTML5 output. Because XSLT separates the transformation logic from the content, changing the entire visual branding of a publication often requires editing a single stylesheet rather than millions of content files.

Component Content Management Systems (CCMS)
XML-based publishing is rarely handled through standalone text editors in modern enterprises. It is managed through Component Content Management Systems (CCMS). Unlike traditional CMS platforms that store entire pages as single blobs of text, a CCMS breaks content down into granular, reusable components. While a standard WordPress page might mix chassis, engine specs, and safety warnings into one block of text, a CCMS treats each of these as discrete XML modules. Authors assemble new documents by referencing these existing components. If a manufacturer changes an engine specification across a product line, the engineer updates that single component in the CCMS. The next time any output is generated, from a quick-start guide to a full service manual, the updated spec is instantly reflected.
SEO and Multi-Channel Delivery
The relationship between XML publishing and SEO is direct and profound. Search engines love structured data. When content is heavily marked up with semantic HTML generated from a clean XML source, search bots can immediately identify the hierarchy and relevance of the information. An XML-based workflow allows publishers to dynamically inject schema.org metadata or Open Graph tags during the transformation process, ensuring that the content not only ranks well but renders beautifully in search snippets and social shares. Furthermore, as voice search and AI summaries become primary interfaces, the ability to query pure, structured data will make these systems indispensable.
The Future of Semantic Content
As industries move toward true omnichannel delivery, the rigidity of traditional publishing bottlenecks is being replaced by the fluidity of XML. Content is no longer written for a destination; it is written for consumption. Whether a user is reading an offline PDF, querying a chatbot, or parsing an RSS feed, the underlying XML ensures the information remains consistent and machine-readable. The greatest advantage of an XML-based ecosystem is its future-proof nature. Because the content is stripped of proprietary formatting, it remains accessible and transformable as technologies inevitably shift. No matter what the next fifteen years hold for digital interfaces, well-structured content will always be the bridge between information and understanding.