Mastering Java XML NodeLists: A Comprehensive Guide
In the realm of Java programming, working with XML documents is a common task. The Document Object Model (DOM) is a popular way to parse and manipulate XML data, and the `NodeList` interface is a crucial part of this process. This guide will delve into the world of Java XML `NodeList`, providing a comprehensive understanding of its functionality, methods, and best practices.
Understanding Java XML NodeList
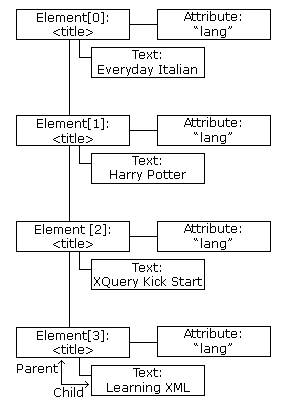
In the context of Java DOM, a `NodeList` is a live, dynamic list of nodes. It represents a collection of nodes that match a certain criteria, such as all the child nodes of an element. The `NodeList` interface is defined in the `org.w3c.dom` package, which is part of the Java standard library.
Key Features of NodeList
- Live and Dynamic: A `NodeList` is live, meaning it reflects the current state of the document. If the underlying document changes, the `NodeList` updates automatically.
- Unordered: The nodes in a `NodeList` are not guaranteed to be in any particular order. The order is typically the order in which they appear in the document.
- Zero-based Index: Like arrays in Java, the index of the first node in a `NodeList` is 0.
Creating and Accessing NodeLists
In Java DOM, `NodeList` objects are typically obtained by calling methods on `Node` objects. Here are some common ways to create and access `NodeLists`:

| Method | Description |
|---|---|
Node.getChildNodes() |
Returns a `NodeList` of all the child nodes of the specified node. |
Element.getElementsByTagName(String tagName) |
Returns a `NodeList` of all the elements with the specified tag name that are children of the specified element. |
Document.getElementsByTagName(String tagName) |
Returns a `NodeList` of all the elements with the specified tag name in the document. |
Navigating and Manipulating NodeLists
Once you have a `NodeList`, you can navigate and manipulate it using the following methods:
int getLength(): Returns the number of nodes in the list.Node item(int index): Returns the node at the specified index.NodeList getElementsByTagName(String tagName): Returns a new `NodeList` of all the elements with the specified tag name that are descendants of the first node in the list.
Here's an example of using these methods:
```java NodeList list = document.getElementsByTagName("book"); int length = list.getLength(); for (int i = 0; i < length; i++) { Element book = (Element) list.item(i); // Process each book element } ```
Best Practices and Performance Considerations
While `NodeList` is a powerful tool, it's important to use it judiciously to avoid performance issues. Here are some best practices:

- Minimize Access: Accessing a `NodeList` multiple times can be expensive. If you need to access the same nodes multiple times, consider converting the `NodeList` to an array or a list.
- Use XPath Whenever Possible: For complex queries, consider using XPath instead of `NodeList`. XPath is generally faster and more flexible.
- Be Cautious with Live Lists: Remember that `NodeList` is live. If the underlying document changes, the `NodeList` may change as well. This can lead to unexpected behavior in your code.
Conclusion
Java XML `NodeList` is a versatile tool for working with XML documents in Java. Whether you're parsing an XML file, processing an XML stream, or manipulating an XML document in memory, understanding `NodeList` is crucial. With the right techniques and best practices, you can harness the power of `NodeList` to simplify your XML processing tasks.