Mastering PDF Manipulation with Python: Essential Libraries
In the digital age, Portable Document Format (PDF) files have become ubiquitous, serving as a universal standard for document exchange. Python, with its extensive ecosystem of libraries, offers powerful tools for PDF manipulation. This article explores some of the most robust and user-friendly Python libraries for working with PDFs, enabling you to create, modify, and extract data from PDF documents with ease.
Why Use Python for PDF Manipulation?
Python's simplicity and readability make it an excellent choice for PDF manipulation tasks. Its vast array of libraries cater to various needs, from simple text extraction to complex document generation. Moreover, Python's cross-platform compatibility ensures that your scripts will run seamlessly on Windows, macOS, and Linux.
Top Python Libraries for PDF Manipulation
Here, we present some of the most popular and feature-rich Python libraries for PDF manipulation, each with its unique strengths:

- PyMuPDF: A fast and lightweight library that supports PDF creation, modification, and extraction. It offers excellent performance and a user-friendly API.
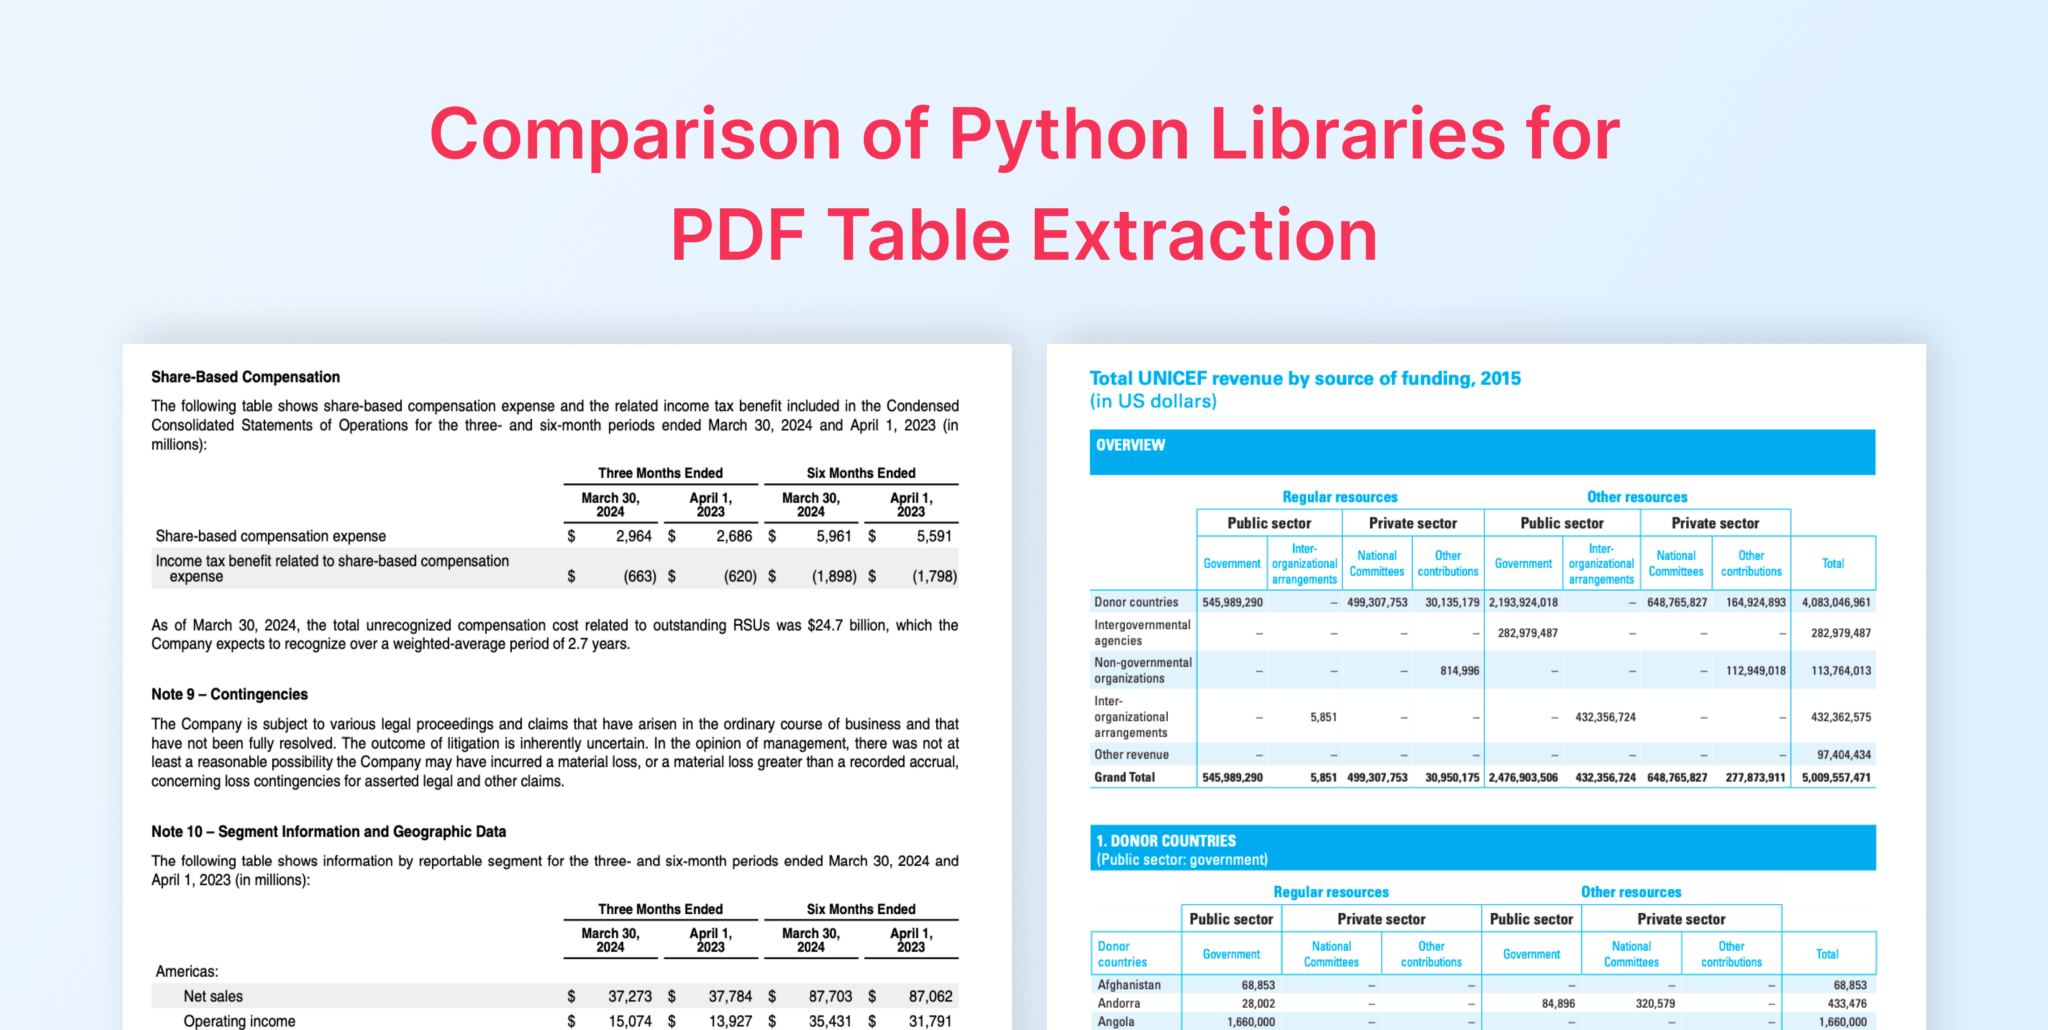
- pdfplumber: Designed for extracting text and tables from PDFs, pdfplumber provides accurate and reliable results. It's particularly useful for data extraction tasks.
- FPDF: A simple yet powerful library for creating PDF documents. FPDF allows you to generate PDFs with ease, supporting various font types and page formats.
- PyPDF2: A versatile library that offers a wide range of features, including PDF splitting, merging, and encryption. It's built on the PDF reference library, providing a robust set of functionalities.
- pdfminer: A popular library for extracting text, tables, and metadata from PDF documents. It's particularly useful for converting PDFs to other formats like HTML or plain text.
- ReportLab: A comprehensive library for creating and manipulating PDF documents. It offers advanced features like drawing shapes, adding annotations, and creating interactive forms.
Comparing Python Libraries for PDF Manipulation
Here's a comparison of the libraries mentioned above, highlighting their key features and use cases:
| Library | Creation | Modification | Extraction | Performance | Ease of Use |
|---|---|---|---|---|---|
| PyMuPDF | ✅ | ✅ | ✅ | ✅✅ | ✅✅ |
| pdfplumber | ❌ | ❌ | ✅✅ | ✅ | ✅✅ |
| FPDF | ✅✅ | ❌ | ❌ | ✅ | ✅✅ |
| PyPDF2 | ✅ | ✅✅ | ❌ | ✅ | ✅ |
| pdfminer | ❌ | ❌ | ✅✅ | ✅ | ✅ |
| ReportLab | ✅✅ | ✅ | ❌ | ✅ | ✅ |
Getting Started with Python and PDF Manipulation
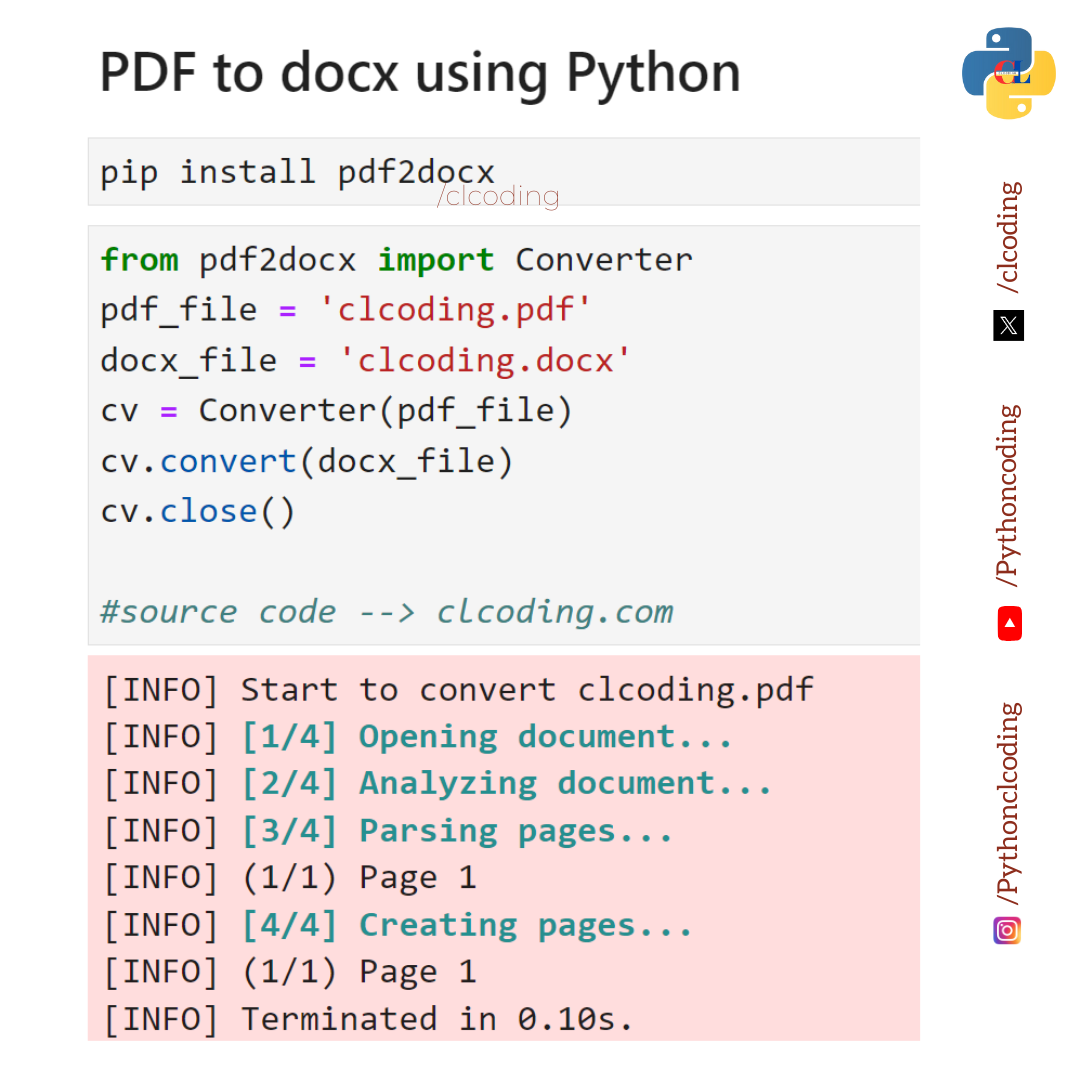
To begin working with PDFs in Python, you'll first need to install the required libraries. You can use pip, Python's package installer, to add these libraries to your project. For example, to install PyMuPDF, run:
pip install PyMuPDF
Once installed, you can import the library in your Python script and start manipulating PDF documents. Here's a simple example using PyMuPDF to extract text from a PDF:
import fitz  # import the PyMuPDF library

doc = fitz.open("example.pdf")  # open the PDF document
text = ""
for page in doc:
    text += page.getText()

print(text)  # print the extracted text
Python's extensive ecosystem of libraries for PDF manipulation enables you to tackle a wide range of tasks, from simple text extraction to complex document generation. By familiarizing yourself with these powerful tools, you'll be well-equipped to handle PDF-related challenges in your projects.