"Convert PDF to XML with JavaScript: Easy & Fast"
In today’s data-driven landscape, converting documents from one format to another is no longer a luxury—it’s a necessity. Among the most frequent transformations professionals encounter is the conversion of PDF files into XML. When paired with a versatile, browser-friendly language like JavaScript, this process becomes remarkably efficient, secure, and scalable for web-based applications. Understanding how to perform a PDF to XML conversion using JavaScript unlocks powerful automation possibilities, from invoice processing to publishing workflows.
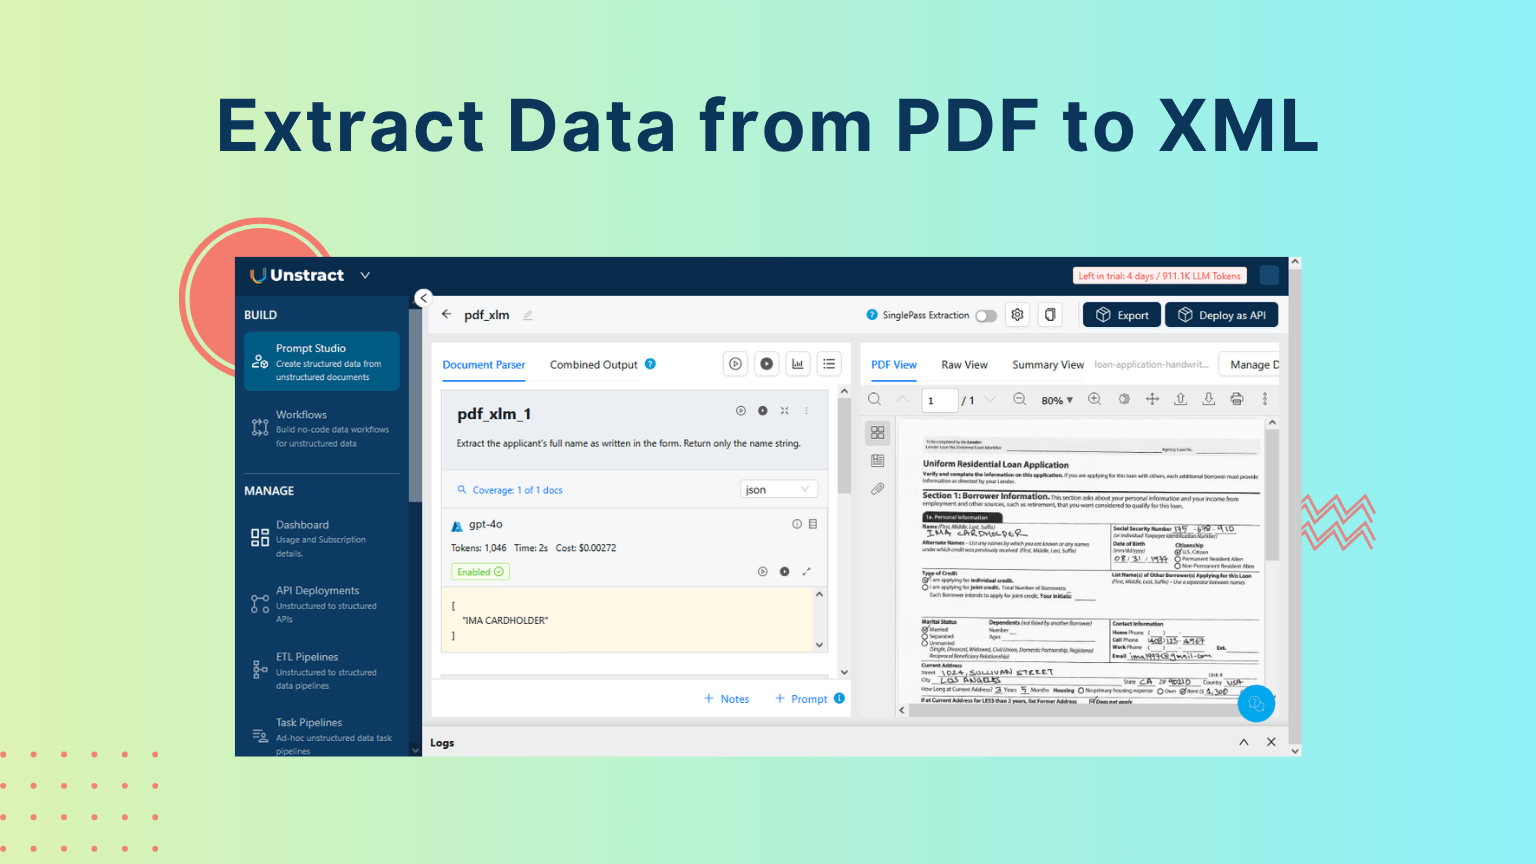
Why Convert PDF to XML?

Portable Document Format (PDF) excels at preserving visual layout and ensuring consistent rendering across platforms. However, its rigidity makes extracting structured data cumbersome. eXtensible Markup Language (XML), by contrast, stores information in a hierarchical, machine-readable structure that databases, APIs, and other systems can ingest seamlessly. Converting a PDF to XML transforms static content into dynamic, reusable data—enabling search engines, enterprise software, and custom scripts to parse invoices, scientific reports, legal filings, or technical manuals with precision.
Core Approaches and Popular JavaScript Libraries

JavaScript offers several paths to accomplish a PDF to XML conversion. Some developers favor a client-side-only solution, while others optimize for Node.js environments on the server. Key libraries and techniques include:
- pdf-parse – a lightweight, pure-JavaScript parser that extracts raw text from PDFs; ideal when you only need the semantic content and can construct your own XML wrapper.
- Pdf2json – broken-down numerical coordinates and text fragments, helpful if character or word-level positioning must be reflected in the XML output.
- @xmldom/xmldom – a standards-based DOM implementation for Node.js; effortlessly lets you build well-formed XML trees from extracted data.
- PDFKit + custom logic – primarily a PDF generation engine, but combined with userland reading logic it can round-trip into XML schemas.
Step-by-Step Conversion Workflow
Regardless of the specific toolset, a typical PDF to XML JavaScript workflow consists of four logical stages:
- Input Acquisition: Load the PDF from a file picker, a drag-and-drop UI widget, or a REST endpoint that delivers a base64 string.
- Content Extraction: Hand the binary blob to a PDF parser that returns clean text, tables, or an intermediate JSON object.
- Data Segmentation: Segment the plain-text or structured payload into nodes—headings, paragraphs, line-items, form fields, or images (with Base64 or URLs).
- XML Serialization: Use an XML library to map the segments into an
-based hierarchy, programmatically inserting attributes and namespaces where required.
Sample Snippet: Converting a Simple PDF with pdf-parse
const fs = require('fs');
const pdfParse = require('pdf-parse');
const { DOMImplementation } = require('@xmldom/xmldom');
const { XMLSerializer } = require('@xmldom/xmldom');

async function convertPdfToXml(filePath) {
  const buffer = fs.readFileSync(filePath);
  const data = await pdfParse(buffer);

  const dom = new DOMImplementation();
  const doc = dom.createDocument(null, 'document', null);
  const root = doc.documentElement;

  const pageNode = doc.createElement('page');
  pageNode.appendChild(doc.createTextNode(data.text));

  root.appendChild(pageNode);

  return new XMLSerializer().serializeToString(doc);
}

convertPdfToXml('invoice.pdf')
  .then(console.log);
Server vs. Client Execution: Pros and Cons
| Criteria | Client-Side | Server-Side (Node.js) |
|---|---|---|
| Data Privacy | File never leaves the browser | Original PDF must be uploaded |
| Performance | Limited by device CPU / RAM | Scales with VM resources |
| Offline Capability | Yes – works without network | Requires persistent connection |
| Library Ecosystem | Fewer heavy-weight parsers | Full Node.js npm registry |

Metadata Retention and Custom Schemas
Enterprise integrations rarely hinge on raw naked text alone. Metadata—author, creation date, embedded bookmarks, form fields, and even image shapes—is often mission-critical. JavaScript’s flexibility allows you to:


- Map PDF info dictionary entries to <meta> tags.
- Convert interactive form widgets into XML elements like <field name="invoiceDate" type="text">.
- Preserve image captions and embedded binary blobs as Base64 strings or external links.
- Enforce industry schemas such as Factur-X for e-invoices or JATS for scientific articles.
Performance Tips for High-Volume Conversion
When throughput is paramount, a few JavaScript-specific strategies can make a measurable difference:
- Chunk incoming files and process multiple pages concurrently using
Promise.all()or worker threads. - Use streaming parsers that emit page-level events rather than buffering the entire PDF in memory.
- Cache repeated XSLT templates so that schema validation happens in a single pre-parsed loop.
- Offload CPU-heavy steps—especially OCR for scanned PDFs—to WebAssembly modules delivered through JavaScript bindings.
Drag-and-Drop Front-End Implementation
Applying this technology in a real-world scenario doesn’t have to expose obscure terminal commands. By connecting a simple HTML file input with an in-browser FileReader and one of the JavaScript parsers mentioned above, line managers can drag a batch of invoices onto a web form and instantly download neatly-structured XML files—no backend deployment necessary. That convenience translates directly into faster turnarounds and fewer manual copy-paste errors.
Wrapping Up
Converting a PDF to XML with JavaScript is not merely a matter of swapping suffixes. It is the essential bridge between human-consumable documents and machine-ready data streams. Through thoughtful library selection, careful metadata mapping, and sound performance techniques, developers can embed robust, privacy-aware conversion pipelines into anything from a single-page utility to a sprawling micro-services ecosystem. The next time a vendor sends you an obscure PDF report, remember—with a splash of JavaScript and a few lines of XML-building logic, that static file can spring to life in your data lake.